Org Mode requests: [FR] Ensure Org features work with envrc, ben, quickenv, direnv, and similar
-1:-- [FR] Ensure Org features work with envrc, ben, quickenv, direnv, and similar (Post Org Mode requests)--L0--C0--2026-11-15T17:23:36.000Z
Over at the Emacs subreddit, Sahkopi4 recounts his journey from Vim to Emacs. Actually, his journey was from Nano to Emacs by way of Vim. When he first started using Linux, Nano was the default editor and he began with that. Eventually he wanted more power and because Vim seemed more popular in the forums he inhabited, he learned Vim. He really like it and the power that it brought him was an eyeopener.
He experimented with other Vim-like implementations but they didn’t work for him so he stuck with Vim. Eventually he tried Emacs and almost immediately became a convert. Like me, he jumped right in and didn’t try to use Evil or some other Vim emulation. Like many of us, he loved the experience and now wants to do as much as he can in Emacs.
As always, a lot of the action is in the comments. Many said that immigrants from Vim should use Evil because it gives you the best of both worlds: the modal, composable editing commands of Vim and the power and flexibility of Emacs. Others said that Evil induces a sort of cognitive dissonance where neither system is fully in control.
There is, of course, the occasional post proclaiming loudly that Emacs is no good because it uses Lisp with all those parentheses. The ankle biting aside, the comments offer an intelligent and useful commentary on Sahkopi4’s journey.
-1:-- Vim To Emacs (Post Irreal)--L0--C0--2026-11-15T15:58:46.000Z
For me, landing changes in Emacs upstream always felt somewhat out of reach, so I kinda postponed it for a long while. Perhaps the biggest hurdle was getting over the process to assign copyright to the Free Software Foundation, which does feel a bit archaic (download, sign, and return a PDF) and slow (mostly waiting for an email response), though hey, I have nothing but sympathy. Open source is unsustainably tricky. As consumers, we often like free as in freedom and free as in beer, but neither pay the bills. We hope some company steps in to fund these projects, but that rarely happens. As a result, most open source projects are starved (even popular ones), run by volunteers working for free.
All that is to say, if the upstream Emacs contribution/onboarding process seems less than ideal, cut it some slack. The project as a whole primarily runs on the blood, sweat, and tears of unpaid contributors. If you can, fund the maintainers you rely on (or better yet, get your employer to do so).
If you've been thinking of contributing to Emacs upstream, don't procrastinate like me and just give it a try. Compared to the typical GitHub pull-request process, your first Emacs contribution may feel a little daunting and dated, but there's a lovely fuzzy light at the end of the tunnel. You see, Emacs has been around for 50 years. Very few software projects get to live this long. Landing contributions on a project with such a rich history is a real treat!
But I digress… Let's get moving. Once I got over procrastinating, I finally got a handful of small contributions landed on the master branch. Thank you, Eli Zaretskii, Stefan Kangas, and Gerd Möllmann, for your help. From then on, I eagerly waited for them to formally make it to a stable release.
Emacs 31 shipped the lot.
I do enjoy a visual (and functional) tweak here and there, and a Dired tweak felt small enough to be the perfect candidate for my very first Emacs contribution.
With that in mind, I tweaked dired-hide-details-mode by adding the dired-hide-details-hide-absolute-location user option, which hides the directory's absolute path, typically displayed at the top of Dired buffers (bug#72272, commit).
More on this in my Hide another detail post.

At some point, I ran into a snag trying to run macosrec from my beloved eshell. The process just crashed with a cryptic abort trap: 6, so the issue wasn't super obvious. It turned out the utility required granting an OS permission that can only be requested by the host app (Emacs) if it includes the relevant description in its Info.plist file.
As of version 31, Emacs includes NSSpeechRecognitionUsageDescription in its Info.plist (bug#72827, commit).
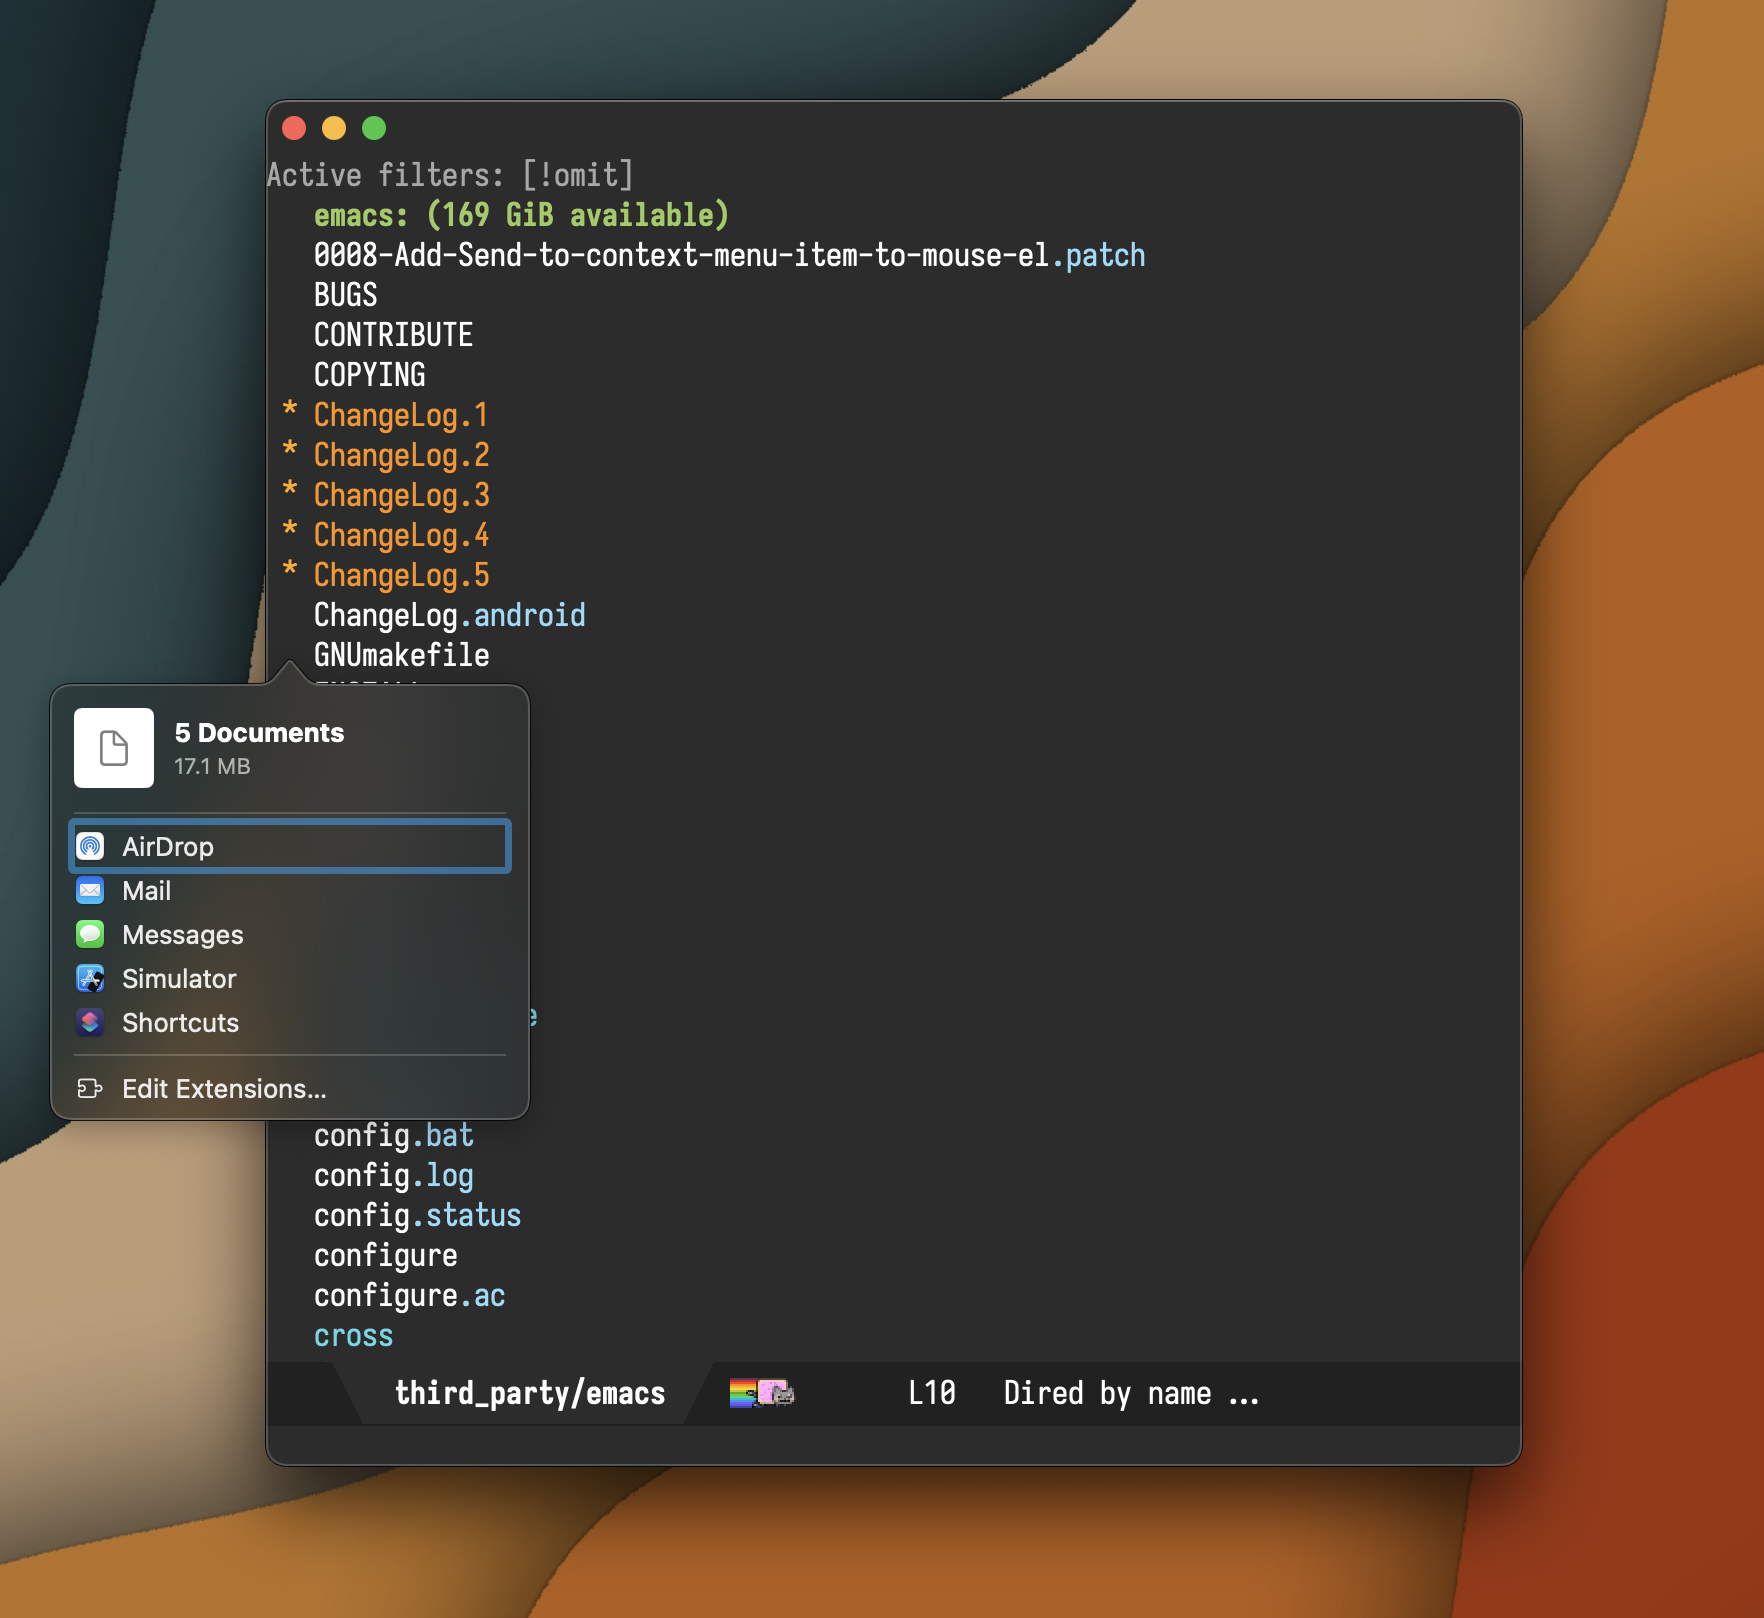
context-menu-mode now includes a "Send to…" item, enabling sending the current file(s) or region text to external apps or services. You can also invoke M-x send-to directly. On macOS, it's powered by the native sharing picker (I use it frequently to AirDrop things to my iPhone). Elsewhere, it falls back to shell-command-do-open (bug#76120, commit, follow-up fix). These two implementations plug into new generic plumbing (send-to-handlers), so you could, for instance, add a handler sharing via Android's native share sheet (android-browse-url can do the heavy lifting) or KDE Connect on Linux (kdeconnect-cli --share).
More in my Emacs send-to (aka macOS sharing) merged upstream post.


Emacs 30 lost macOS dictation when migrating to NSTextInputClient. Implementing selectedRange in nsterm.m brought it back (bug#79070, commit). With LLMs/agents being a thing these days, dictating into your Emacs buffer may be just the thing to complement your AI workflow.
I covered this in my macOS dictation returns to Emacs (fix merged) post.

Are you getting value from any of my upstreamed changes or my Emacs packages? Please consider sponsoring to keep the work going. While my patches may seem relatively straightforward, some took quite a bit of effort to land upstream.
My Emacs work not your cup of tea? No worries. As mentioned earlier, sponsor the maintainers you rely on instead.
-1:-- My Emacs 31 contributions (Post Alvaro Ramirez)--L0--C0--2026-11-15T00:00:00.000Z
Charles Choi has a nice hint for those of you who travel and phone home with Emacs. Here’s the situation: you are travelling and log into your home server with SSH and emacsclient. It’s wonderful. Just like being at home except the date/time stamp is wrong. The time and date are whatever your home server thinks they are but you want them to be local time.
The answer is simple. You simply need to change the TZ (timezone) environment variable to reflect your current location. For example, if you’ve travelled to New York (in the US) you would set TZ to “America/New_York”. Emacs, of course, provides a command to do this: (setenv "TZ" "America/New_York").
The zone codes can be a bit opaque so Choi has added a command to the latest Casual suite to set the TZ variable complete with completion. Take a look at his post if you’re interested.
-1:-- Setting The Timezone In Emacs (Post Irreal)--L0--C0--2026-11-14T15:37:33.000Z
-1:-- [FR] Fontify leading whitespace in multi-line links in a list better (Post Org Mode requests)--L0--C0--2026-11-13T22:29:16.000Z
Emacs already tells you when a version-controlled file has local changes, but it does it with a punctuation mark: a clean file shows Git-master in the mode line, and a modified file shows Git:master. The only difference is the separator, and if the theme leaves the VC state faces unspecified there is not even a colour change. I wanted something I could see without stopping to parse the mode line, without adding another package or another Git subprocess. The result is a single bold status letter at the start of the mode line: M for modified, A for added, D for deleted, U for a conflict, and L for a lock.
The built-in vc integration puts a backend/state string in the mode line. For Git it looks like this:
| State | Mode line | Indicator |
|---|---|---|
| Clean | Git-master |
- |
| Modified | Git:master |
: |
| Added | Git@master |
@ |
| Conflict/removed | Git!master |
! |
| Missing | Git?master |
? |
Hovering over the string gives the full description ("Locally modified file under the Git version control system"), and clicking it opens the VC menu. That is all useful, but the separator is not a status indicator you notice at a glance. C-x v = and C-x v d are there when you want the details.
The mode line string is a propertized string, and its face encodes the VC state. Reading that face is cheap: no vc-state call, no git status, just a property lookup on a value VC has already computed. I map the faces to the same letters Git uses:
(defface my/vc-dirty-indicator-face
'((t :weight bold))
"Face for the mode-line local-changes indicator.
Only the weight is set, so the foreground and background follow the
mode line's normal colours."
:group 'vc)
(defun my/vc-dirty-indicator ()
"Return a Git-style status letter for local VCS changes."
(let* ((face (and (bound-and-true-p vc-mode)
(stringp vc-mode)
(> (length vc-mode) 1)
(get-text-property 1 'face vc-mode)))
(info (pcase face
('vc-edited-state '("M" "Locally modified file"))
('vc-locally-added-state '("A" "Locally added file"))
('vc-conflict-state '("U" "File contains merge conflicts"))
('vc-removed-state '("D" "File removed from version control"))
('vc-missing-state '("D" "Tracked file missing from disk"))
('vc-locked-state '("L" "File locked by another user")))))
(when info
(propertize (concat (car info) " ")
'face 'my/vc-dirty-indicator-face
'help-echo (cadr info)))))
Then put it at the start of the mode line. The install function removes any previous copy first, so reloading the config does not give you two indicators:
(defun my/vc-dirty-indicator--install ()
"Insert the dirty indicator at the start of `mode-line-format'."
(let* ((indicator '(:eval (my/vc-dirty-indicator)))
(fmt (default-value 'mode-line-format)))
(when (and (listp fmt) fmt)
(setq fmt (delete indicator fmt))
(let ((new nil)
(inserted nil))
(dolist (item fmt)
(push item new)
(when (and (not inserted) (eq item 'mode-line-front-space))
(push indicator new)
(setq inserted t)))
(unless inserted
(push indicator new))
(setq-default mode-line-format (nreverse new))))))
(my/vc-dirty-indicator--install)
The face sets only :weight bold, so the letter uses whatever foreground and background the mode line already has. I tried a red background first; it was too loud, and the bold letter is enough.
M at the start of the mode line.git add: A.D.U.D with a "missing from disk" tooltip.
The existing ** indicator still means the buffer has unsaved edits; the version-control letter follows the state VC knows about and updates when VC refreshes the mode line, such as after saving or a VC operation. Untracked files do not get a ? letter because vc does not install a mode-line state for unregistered files; C-x v d or git status remains the place to see those.
The mode-line letter answers the smaller, more frequent question: is this file carrying local changes right now? One character, no extra processes, and no guessing what a colon means.
-1:-- Making Git Changes Obvious in the Emacs Mode Line (Post James Dyer)--L0--C0--2026-11-13T15:50:00.000Z
In the recent years, I've been configuring and
building GNU Emacs from source, specifically the
master branch of the emacs.git repository.
Doing so allows me to use and test latest Emacs
features, test my Emacs Lisp code with the laest
developments in Emacs, and easily contribute my
own changes to Emacs.
Before we start, I recommend reading the INSTALL
file in the Emacs source repository for building
Emacs from source tarballs, and also INSTALL.REPO
for details about building Emacs from its source
repository. The information provided here were
built upon the details documented in those files.
When in doubt, consult those files as the main,
authoritative source of information for how to
build Emacs from source.
To build GNU Emacs from its source repository, we
first need to install the various required tools
and build dependencies of Emacs. On Debian-based
systems, this can be done using apt. First, we
need to add the source packages for the current
release of our Debian-based distribution in apt's
configuration by adding the corresponding deb-src
lines in an apt source list file. For currently
existing and older Debian releases, that would be
done by adding a corresponding deb-src line for
each deb line in /etc/apt/sources.list, such as:
deb http://deb.debian.org/debian/ trixie main deb-src http://deb.debian.org/debian/ trixie main
In systems with recent apt versions with so-called
modernized sources that might look editing a file
like /etc/apt/sources.list.d/debian.sources and
adding deb-src to the Types lines:
Types: deb deb-src URIs: http://deb.debian.org/debian/ Suites: trixie Components: main Signed-By: /usr/share/keyrings/debian-archive-keyring.gpg
Then run sudo apt update to have apt download
package information from the configured sources.
We can now run sudo apt build-dep emacs to have
apt download and install the build dependencies of
Emacs. Debian-based distributions have packages
for a few different configurations of Emacs, like
emacs-pgtk with PGTK support for Wayland, and
emacs-nox for Emacs without GUI support, which
we can use with apt build-dep to download the
specific dependencies of those configurations.
After installing Git using sudo apt install git
if not already installed, we're now ready to clone
the Emacs source repository from GNU Savannah:
git clone https://https.git.savannah.gnu.org/git/emacs.git
We can add --depth 1 to make a shallow clone of
the repository, if we don't care about having a
complete log of previous commits to the Emacs
repository (shallow clones are much faster).
If cloning over HTTPS is slow, we can try cloning over Git's own protocol (with the caveat that the repository is cloned over an insecure channel) or over SSH if we have a Savannah account, using one of the following URLs instead of the one above:
git://git.git.savannah.gnu.org/emacs.git ssh://git.savannah.gnu.org/srv/git/emacs.git
We now change to the Emacs repository directory
we just cloned, and run the autogen.sh script
once to generate the configure script, which
we will use to configure Emacs to our liking:
cd emacs ./autogen.sh
To configure Emacs, the simplest approach is to
run configure without any additional options,
to have it use the defaults. We can get a list
of available configuration options by running:
./configure --help
As I rebuild Emacs frequently, I normally don't
"install" it, but for a typical setup, we'll
want to specify the installation directory using
--prefix, e.g.:
./configure --prefix=$HOME/.local
Later, make install will install Emacs under
the specified directory.
By default, some of the files (such as *.el)
will be compressed during installation. We can
prevent that using --without-compress-install.
For my builds, I always use these configuration options:
--without-gconf --without-gsettings --without-gpm --with-native-compilation
As I don't use the GNOME desktop, the GConf and GSettings integrations are always more trouble than useful for me, so I disable them. Further, I disable the GPM support, since I never use the mouse when using Emacs in the terminal. Lastly, I explicitly enable native compilation support.
In Wayland environments, I usually use PGTK:
--with-pgtk
And in X11 environments (e.g. EXWM), I either use the Lucid toolkit:
--with-x-toolkit=lucid --with-xaw3d
Or no toolkit at all:
--with-x-toolkit=no --without-xaw3d
Later after building Emacs, we can view the
configuration options in Emacs by inspecting
the system-configuration-options variable.
After running ./configure, we can now finally
build Emacs by running make. The first build
will take a while, since all of Emacs is being
built from scratch. Subsequent builds will
generally be faster.
We can optionally run make install to install
Emacs into the prefix specified earlier, or the
default /usr/local. Note that this step might
require using sudo if our user doesn't have
write permission for the prefix.
After building Emacs, we run it either from
the install location if we ran make install
earlier, or directly from the source repository.
Currently, Emacs's build system makes a symlink
to the latest built binary in the repository at
src/emacs, and for emacsclient and other
auxiliary binaries under the lib-src directory.
When skipping make install, we might still want
to be able to easily launch Emacs from anywhere
by typing emacs. We can do that by making
symlinks to emacs and its auxiliary binaries
inside a directory in our $PATH, such as
$HOME/.local/bin, like so:
cd $HOME/.local/bin ln -s $HOME/src/emacs/src/emacs . for e in \ ebrowse emacsclient etags make-docfile\ make-fingerprint hexl rcs2log; do\ ln -s $HOME/src/emacs/lib-src/$e .; done
For non-install setups like this, I augment
Info-directory-list in my init file with
the location of the info manuals in the
repository to make them known to Emacs:
(defvar Info-directory-list)
(with-eval-after-load 'info
(setq
Info-directory-list
`(,@Info-directory-list
,(expand-file-name
(convert-standard-filename "info/")
source-directory)
"/usr/share/info/")))
We can pull in the latest changes in the Emacs
repository using git pull, then rebuild our
Emacs by running make.
Occasionally, rebuilds may fail due to bad
interaction of changes with leftover build
artifacts. In such cases, the easiest thing
to do would be a make bootstrap for an
almost-from-scratch build. On even rarer
occasions, make bootstrap might also fail.
We would then want to run git clean -xdf to
remove every file that's not tracked by Git,
as if we freshly cloned the repository.
In such cases, we would need to configure the
build again using ./configure and provide the
desired options before running make again.
Protesilaos's similar post from early 2025 was part of the inspiration for writing and sharing my version:
https://protesilaos.com/codelog/2025-03-22-emacs-build-source-debian/Lastly, to reiterate, Emacs's own INSTALL and
INSTALL.REPO files for building from source:
https://cgit.git.savannah.gnu.org/cgit/emacs.git/tree/INSTALL
https://cgit.git.savannah.gnu.org/cgit/emacs.git/tree/INSTALL.REPO
Take care, and so long for now.
-1:-- Building GNU Emacs from source (Post Amin Bandali)--L0--C0--2026-11-13T14:09:42.000Z
nvALT icon
Product: nvALT
Price: Free
Christmas came early this year. Brett Terpstra released a new version of nvALT. Compatible with modern versions of macOS, it left me dancing with joy.
nvALT
Before Obsidian, and its ilk, nvALT was the notes app I lived in. It was distinguished by its simplicity. You typed in the unibar to both search your notes and create new notes. I was in plain text mode and it was fantastic.
Over time, other programs came along and I moved away from it. I remember that I loved the program for how simple it was. No friction. Just notes. Easy creation and efficient search.
Brett Terpstra has revived nvALT to be compatible with modern versions of macOS. He has been active in the development of nvALT in the last few weeks. I am not going to try to explain the features of the product. It is something you need to discover on your own. I am going to instead talk about simplicity and its alternative.
I used to love Obsidian. It is a great product. It is extended through community plugins. It does a whole lot of stuff. You need to live in it for a while to be comfortable in it. There is nothing wrong with the program. It is capable, full-featured and does a whole host of things. There are people living in it and enjoying the experience. It is not for me. Firstly, it is Electron. So it eats memory. It is responsive, that is not the problem. It just takes too much memory. Secondly, it is by design something that is a distracting mess. Let me explore this idea in more detail.
I use Emacs, I live in it. I use it for everything I can. It has the steepest damn learning curve that I have ever tackled in a program. However I am comfortable with it. Took me a long time to get here. But I am happy now. I don’t make too many changes to the setup. I have it working, I am happy with it, there is no reason to monkey with something which works. Every bit of the configuration is something I understand and know. There is comfort in that. If I feel the need to change something, I can. It is not a burden anymore. I have learned the keyboard commands I need. I live in it.
I never got that feeling in Obsidian. It was distracting. I spent an inordinate amount of time playing with plugins. Trying to customize keyboard commands I wanted. Trying to figure out bases and canvas and somewhere in the middle of using it, it occurred to me that I was not taking notes but tweaking the system. That got old really quick. I stopped using it and moved everything into Emacs.
Don’t get me wrong. I spent a lot of time doing the same thing in Emacs. I am a tweaker. I try to tweak everything and Emacs is heaven when it comes to the ability to customize an editor. Somewhere in that exercise I got familiar with the fundamentals of the program. It was not a strain anymore. My familiarity with it changed how I reacted to it. I get my work done in it. It doesn’t get in the way anymore.
If I did the same kind of immersion into Obsidian, I would be as comfortable in it as I am today in Emacs. I could not see beyond the memory usage and moved on from Obsidian.
Back to the notion of simplicity. nvALT is simple. You set up the preferences once and then you are ready to go. There are keyboard commands. You can merge them to your muscle memory with continued usage.
There is no cognitive overload.
Conceptually I look at cognitive overload in two ways:
nvALT reduces the first part and that is the intrinsic feature of this program.
Creating and searching notes is simple. You don’t spend any energy on the program. You can concentrate on your notes/writing. It is liberating. It just works.
What are the downsides of this simplicity? Goes against all the models of knowledge management. You can link between documents. The old-style wikilinks work well. There are no back links. There are no useless graphs of your knowledge base. You are not going to have a canvas. You are not going to have database functions. No queries to manage. It is a bunch of text files in a folder and that is about it.
nvALT is not the only program which provides these features. The Archive is a paid solution ($19), which provides similar features and is great.
FSNotes is a free alternative which does more than both nvALT and The Archive. It lets you manage multiple folders and it does a great job of that.
Brett Terpstra and Fletcher T. Penney have a program which has been in beta for a long time. The product is called nvUltra, if and when it gets released, it is going to be a major competitor in this space. I have been on the beta from the start and love the program.
While I wait for nvUltra to be released, nvALT is a great resource which I am happy to be using after a long time. Download the program and use it for a while, you might also discover the charms of simplicity when it comes to your note-taking.
Recommended heartily.
macosxguru at the gmail thingie.
-1:-- Revival of nvALT (Post Bicycle for Your Mind)--L0--C0--2026-11-13T05:43:25.000Z
-1:-- Cross-article linking in Org/Hugo (Post Diego Zamboni)--L0--C0--2026-11-13T02:25:00.000Z
I record brief introductions for all the EmacsConf talks so that they can be played automatically. That way, hosts don't have to worry about pronunciations on air, and there's one less changeover that might introduce technical issues. We can cut to the next talk a bit abruptly because everything runs off a crontab-powered schedule to keep things running on time on multiple tracks, so it helps to have a little transition between Q&A and the next talk. It's also nice having some kind of pronunciation reference so that when people discuss the talks or even just think about them with their internal monologues, they might have a better sense of how to say the speakers' names. We ask speakers to say their names at the beginning of their presentation, but people don't often include their last names, so the intro gets that consistently. The intro videos are available on the talk pages after the conference, and I've occasionally used them to remember how someone's name is pronounced.
Here's an example intro from EmacsConf 2025:
Here's my process for preparing those intros with Emacs.
First, I create all the intro slides with LaTeX and TikZ using the function emacsconf-stream-generate-in-between-pages from emacsconf-stream.el. This year, the template I'm using is _template.tex and the background image is _template_bg.pdf.
I used to use an SVG and just replace the elements within it (template.svg, emacsconf-stream-generate-in-between-page-svg). This year, some of the talk titles are very long and SVG doesn't have widespread support for wrapping.
LaTeX handles wrapping and positioning beautifully. This even allows me to have ligatures like the "ff" in Jeff Trull's name.
I noticed those ligatures disappeared when I used Inkscape to convert to PNG, so I needed this command instead:
inkscape --pdf-poppler --export-type=png -w 1280 -h 720 --export-background-opacity=0 --export-text-to-path
This is the function that generates the individual intro slide:
emacsconf-stream-generate-in-between-page: Use LaTeX to generate the intro slide for TALK based on assets/in-between/_template.tex.
(defun emacsconf-stream-generate-in-between-page (talk &optional prev info force) "Use LaTeX to generate the intro slide for TALK based on assets/in-between/_template.tex." (interactive (list (emacsconf-complete-talk-info))) (let* ((prev (or prev (emacsconf-previous-talk talk info))) (dir (expand-file-name "in-between" emacsconf-stream-asset-dir)) (template (with-temp-buffer (insert-file-contents (expand-file-name "_template.tex" dir)) (buffer-string))) (default-directory dir)) (write-region (emacsconf-replace-plist-in-string (list :current-title (or (plist-get talk :title) "") :current-speakers (or (plist-get talk :speakers) "") :current-details (format "%s\\\\\n%s" (or (plist-get talk :absolute-url) "") (pcase (plist-get talk :q-and-a) ((rx "live") "Live Q\\&A after talk") ((rx "pad") "Etherpad") ((rx "IRC") "IRC Q\\&A after talk") (_ ""))) :previous-title (or (plist-get prev :title) "") :conf-name emacsconf-name :conf-year emacsconf-year :previous-speakers (or (plist-get prev :speakers) "") :previous-details (format "%s\\\\\n%s" (or (plist-get prev :absolute-url) "") (pcase (plist-get prev :q-and-a) ((rx "live") "Live Q\\&A after talk") ((rx "pad") "Etherpad") ((rx "IRC") "IRC Q\\&A after talk") (_ "")))) template) nil (expand-file-name (concat (plist-get talk :slug) ".tex") dir)) (shell-command (format "lualatex -shell-escape %s && inkscape --pdf-poppler --export-type=png -w 1280 -h 720 --export-background-opacity=0 --export-text-to-path %s" (expand-file-name (concat (plist-get talk :slug) ".tex") dir) (expand-file-name (concat (plist-get talk :slug) ".pdf") dir)))))
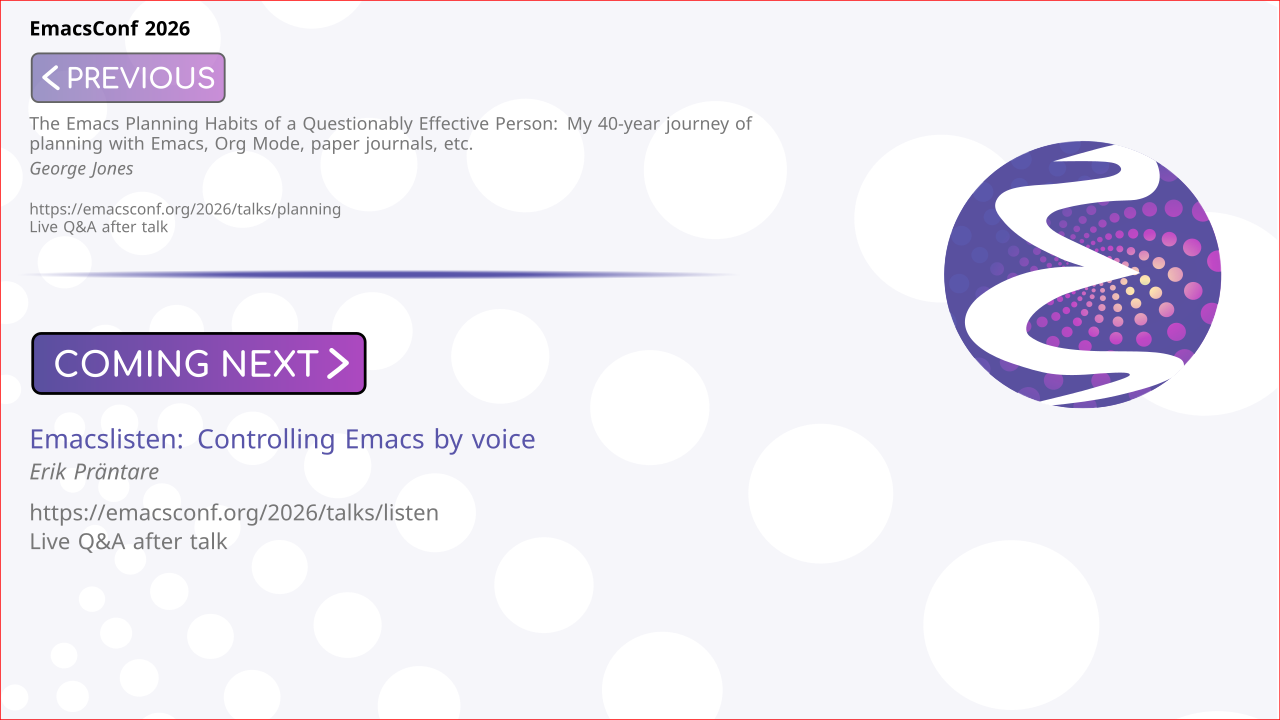
and here's an example slide it creates:
Once I had the intro slides, I prepared my script. I called emacsconf-subed-intro-subtitles from emacsconf-subed.el to create a VTT captions file that starts like this:
WEBVTT NOTE #+OUTPUT: emacsconf-2026-sat-open--saturday-opening-remarks--sacha-chua--intro.webm [[file:/home/sacha/proj/emacsconf/2026/assets/in-between/sat-open.png]] 00:00:00.000 --> 00:00:00.000 Next, we have "Saturday opening remarks", by Sacha Chua. You can ask questions via Etherpad. NOTE #+OUTPUT: emacsconf-2026-planning--the-emacs-planning-habits-of-a-questionably-effective-person-my-40year-journey-of-planning-with-emacs-org-mode-paper-journals-etc--george-jones--intro.webm [[file:/home/sacha/proj/emacsconf/2026/assets/in-between/planning.png]] 00:00:00.000 --> 00:00:00.000 Next, we have "The Emacs Planning Habits of a Questionably Effective Person: My 40-year journey of planning with Emacs, Org Mode, paper journals, etc.", by George Jones. You can ask questions via web conference by joining from the talk page or ask questions through Etherpad or IRC.
The text is based on the Org entry properties for each talk in our conf.org file. It used subed-record directives to define the output files and the visuals.
Then I used subed-record to start recording each segment. I pressed <left> (subed-record-retry) to re-record a segment as many times as I needed to. This adds or updates an #+AUDIO directive that points to the current recording and it also updates the timestamps. When I was satisfied, I pressed <right> (subed-record-accept-segment) to update the ending timestamp and move on to the next segment to record. Whenever I needed to take a break from recording, I used RET (subed-record-accept-and-stop) to accept the last segment and stop.
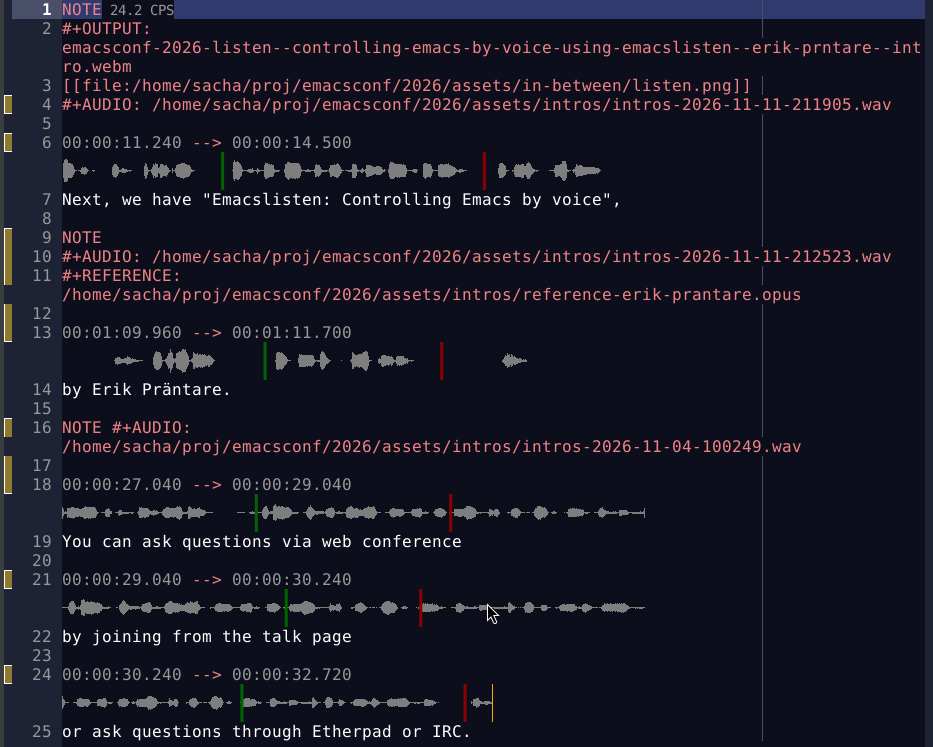
After recording, I used subed-waveform-show-all to see the waveforms for each segment. I left- and right-clicked on the waveforms to refine the start and end timestamp, getting rid of the sound from the keyboard shortcuts, and I used subed-split-subtitle to split each long cue into the proper lines for the subtitles.
Here's the livestream where I worked on some of the intros.
After editing the audio this way, I used subed-record-compile-video (C-c C-c after subed-record-set-up) to create all the videos by using compile-media and FFmpeg. I could also regenerate just one or two videos by selecting the region and then using the same function..
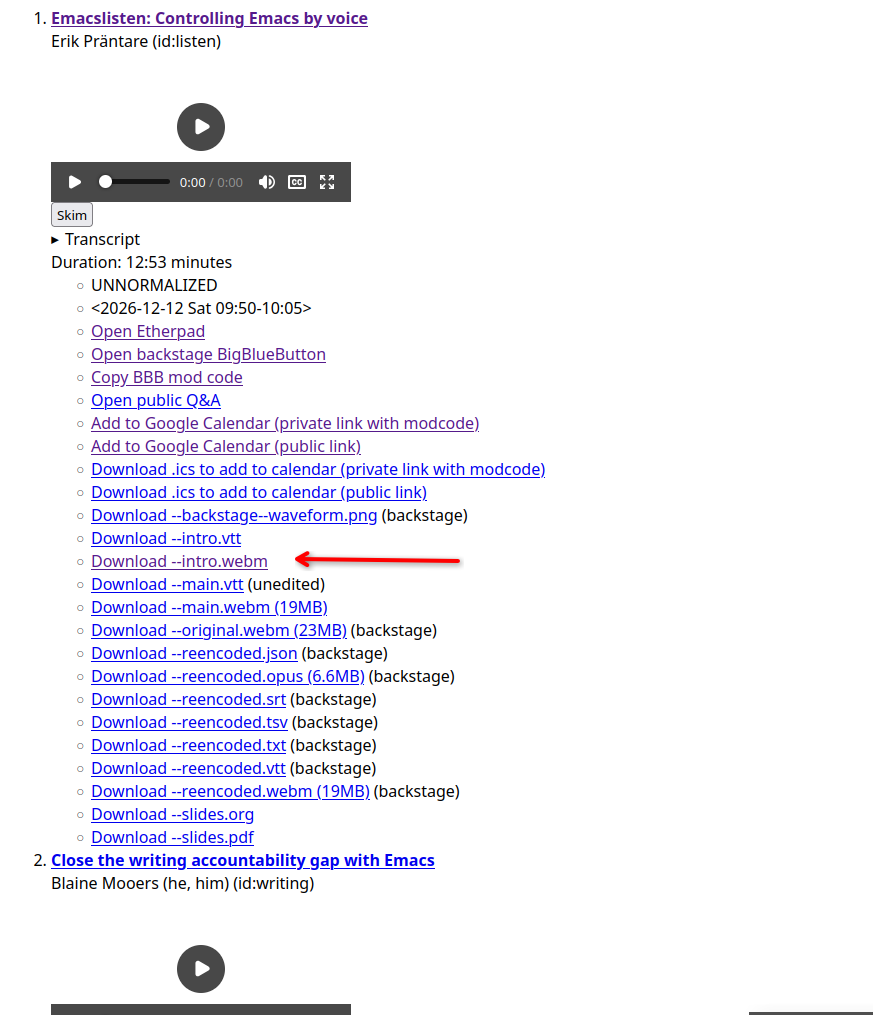
Once the videos finished, I uploaded them to our password-protected backstage area, and emacsconf-publish-backstage-index added them to the page.
Then I used emacsconf-mail-intro-to-all to send emails to all the
speakers with the links to the intros for review. Many speakers
confirmed that their pronunciations were fine, and some replied with a
recording of their name so that I could use it for reference. I added
those in the comments so that I could replay them while recording with
R (learn-lang-subed-record-play-current-reference) or
learn-lang-subed-record-play-reference-and-current-subtitle. I also
copied and pasted the relevant part of the caption file so that I
could record different variations with subed-record. It's just text,
after all, so it's easy to do all sorts of things the way that you
would do them normally in Emacs. For example, here's what it looked
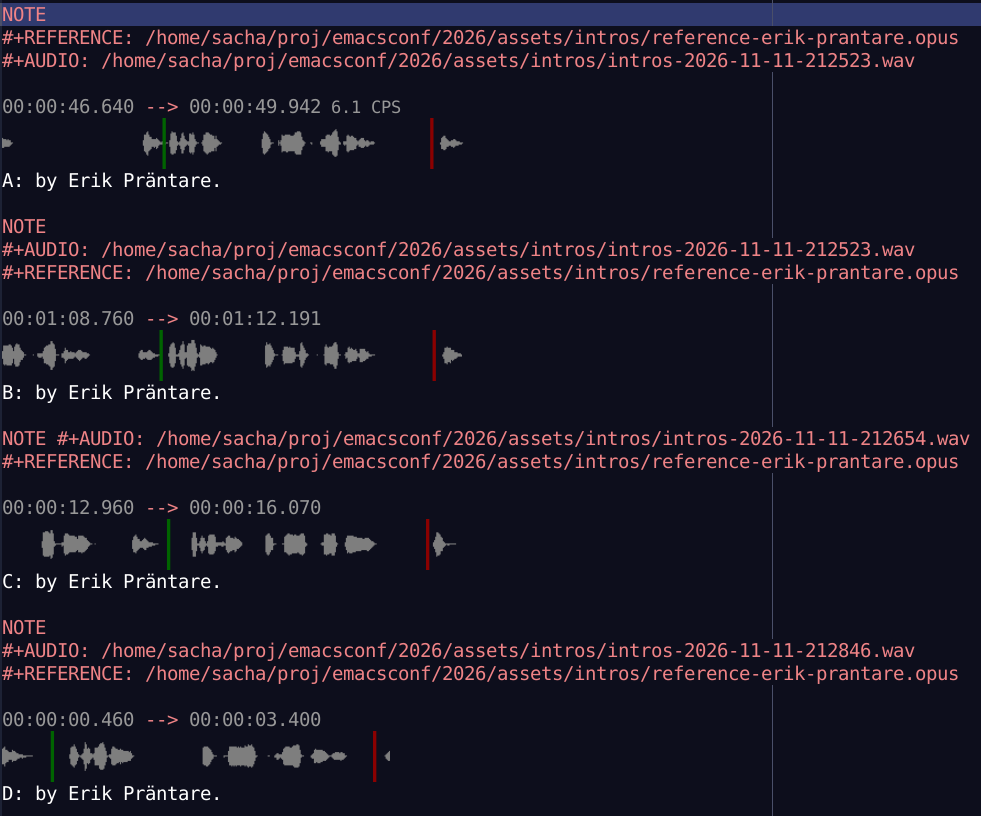
like when I was editing the versions for Erik's name:
Erik said option B sounds closest. It's not quite perfect, but it's closer than the pronunciation I started with. I might circle back around to this and try again sometime. =) Anyway, to use option B in the final video, I can just delete the cues for the other versions and remove the part where I said option B. Then I can select that part of the subtitles and compile just his video.
This makes it easy to update the intros whenever something changes. For example, if a speaker turns out to be available during the conference for a live Q&A session, I can update the Org entry for their talk (set :Q_AND_A: live), regenerate the intro slide, and re-record the Q&A explanation or even copy-and-paste one from a different intro. They can also change their talk title and that's totally okay. Yay Emacs!
You can comment on Mastodon or e-mail me at sacha@sachachua.com.
-1:-- EmacsConf: recording and re-recording introductions (Post Sacha Chua)--L0--C0--2026-11-13T02:17:31.000Z
-1:-- My Emacs Number Package Generates Random Numbers (Post Eric MacAdie)--L0--C0--2026-11-13T01:53:06.000Z
Here’s the problem: You are traveling in a different time zone from the Emacs server instance you are accessing remotely via ssh + emacsclient. All clock calculations in that Emacs session are using the local timezone relative to where the server is located. But what you really want is emacsclient to use the current timezone you are in, so things like the mode line clock render accordingly.
To adjust the timezone in an Emacs session, use the command setenv to set the environment variable TZ with a timezone defined in the zoneinfo database. This can be called from Elisp as shown below.
1 | |
The latest v3.1.0 update of Casual adds the command casual-timezone-set-tz that provides a completion interface for selecting a timezone to pass to setenv.
1 | |
Note that setting TZ impacts the Emacs session globally; any other running behavior depending on a clock should be taken into account.
-1:-- Setting the Timezone in Emacs (Post Charles Choi)--L0--C0--2026-11-12T21:35:00.000Z
Doug Hoyte writes to say that’s he’s making his excellent book Let over Lambda available on line and as a PDF. I’ve written about the book several times most importantly here and here but you can search Irreal for “let over lambda” for the the others.
I can’t overemphasize the effect this book had on me. I learned a lot about Lisp and even programming from it. Some people complained that they didn’t like his approach to structuring his Lisp but I never had a problem with it.
The book is about Lisp Macros and the tremendous powers they provide. As an example, Hoyte gives a macro implementation of the Scheme named let construct. There are a lot more things like that in the book.
Let Over Lambda is about Common Lisp but a large portion of it applies to Elisp too. If you’d like to become really good at Elisp, Let Over Lambda is a good resource. As I said, it’s mostly about Common Lisp but a surprising amount carries over to Elisp.
In any event, you can check out the book for free and if you like what you see, you can read the entire book. It is, believe me, well worth your while.
-1:-- Let Over Lambda Is Free To Read (Post Irreal)--L0--C0--2026-11-12T15:27:40.000Z
Zororg in emacs chat/universe.I'm happy that this topic erupted after I poked around in mastodon, maybe some day I'd like to hoist as well.
Before I write up on topic, I'm sure many emacs users might remember that there was a podcast channel called "Discovering Emacs", there was a Youtube channel (rip), mastodon presence in emacs.ch (rip) and everywhere in podcast apps. It was very promising and a professional ambience to hear someone speak of dear emacs. Thankfully git repo exists, and you see the notes and how good it was, wish it had continued or someone brings similar stuff to our small church of emacs. Obviously we are ever so thankful for sacha, protesilaos and emacs-devel people for their good faith and holding up emacs for what it is today even after 50 years.
We need more community users to hold the torch, contribute, volunteer and not be behind the shiny tool-era that is making us lazy and degenerate. Me included!
Back to topic, I usually discovered emacs features based on "good to have" or "cool to have" notion and kept on exploring or adding, sooner came to realize that I've not even grossed the emacs builtins batteries. Nowadays I only discover features based on need, if not it'd be a aha/TIL moment as always.
Emacs is one best example of a perfect software for humans, and by humans. Each object or data is so well connected, that by just using emacs you keep discovering new features every now and then. The docs are the greatest feat of any software that, docs exist for humans and code exists as docs for humans too. History of emacs itself is very funny, thanks for the archives gnu mailing list has and some code has many funny comments, this all brings a smile to users at some point when they again "discover" the legacy of emacs.
Thanks to Alternate Intelligence these days that many people don't recognize the charm of emacs anymore, and thanks to the every busy world that shiny tools keep popping up to be eye candy for all. But for those who recognize or stay, surely emacs got us treat for lifetime. Emacs was almost like Second brain to many users, but now their first brain has been almost replaced by Lazy Learner’s Machine (LLM) and emacs is out of equation now.
How often do you discover an Emacs feature?
Nowadays rarely, even r/emacs has no human posts, and mastodon #emacs seems to be quite. So for now I'm just getting things done using emacs for my needs. Hopefully could find gems via mailing lists now.
What was the most recent feature that you adopted?
A consult function to change buffer font by preview. Which is very cool, just like color theme playing with different font is fun to read as per mood. Discovered via r/emacs and hackernews.
Except for this I've been using ezemstov's fork of emacs which builds pure wayland backend using Skia GPU renderer, without GTK or cairo toolkit. Its snappier and 3-5x snappier than PGTK… read more Its even available in nix emacs-overlay (go try it out with nix shell)
Are you a “Set it and forget it” type of user?
Most config were that way, but later on trimmed them out and only keep essential ones now. Thats the reason I prefer using builtins now unless necessary. Config is now at 2K LOC.
Do you read Emacs-centric social media trolling for new things to try?
I wonder where is emacs trolling happening, but I glance actively over r/emacs and #emacs in mastodon, and obviously planet Emacs for all golden nuggets.
What’s the next feature that you’d like to try?
Canvas patch, IGC, and more than all Gnus upgrade to be async and snappier.
If you’re a Feature Creator, tell us about that!
Nope, but I've a public config that might be of interest. Also since I was missing two package needs, I tried building those (ofc with help of second brain).
-1:-- Discovery of Emacs Features (Post Dilip - Zororg)--L0--C0--2026-11-12T00:00:00.000Z
If you invoke org-capture and then create a note1 while the
capture is active (as I'm doing now), you might be very surprised
when you press C-c C-c to finish the note -- it vanishes!
Don't Panic!
In order to see the note, you'll need to press C-c C-c a second time
to complete the capture. Then org-capture adds the item into the
Org file, along with the note.
My preference in this situation is to write only the first phrase
or sentence of the note. Then I issue the two presses of C-c
C-c and complete the note at its destination. I do this
not only to avoid the "scary missing note" scenario; I also worry
about leaving work unsaved for any amount of time. The computers I
grew up with were prone to crashing at inopportune times, so I
adopted the motto, "Save Early; save often." An Org note is
composed in the *Org Note* buffer, which has no file associated
with it and therefore is not a good candidate for saving.
1 With C-c C-z (org-add-note)
-1:-- Creating a Note While org-capture is Active Can Be Confusing (Post Raymond Zeitler)--L0--C0--2026-11-11T19:04:13.152Z
Álvaro Ramírez just announced the release of Journelly 1.5. It’s the formal release of the beta version that I recently wrote about. I can’t say enough about this release. As I’ve said before, my Journelly database is over 4 thousand entries long and before this release Journelly was getting laggy and hard to use but this release resolved all those problems. Now Journelly is as snappy as it was when I had only a few entries and everything about it seems faster and easier.
But wait. There’s more. Ramírez has added an “on this day” feature as well as adding features that make searching for entries by date easier.
If you use Journelly as a journal, you may be interested in the new “on this day” feature. There’s a new button that will show you entries happening on the same day from other years. My particular use case for Journelly is as a memo book so I have no use for this feature. Fortunately, the new Journelly makes it easy to toggle it off if you don’t want it.
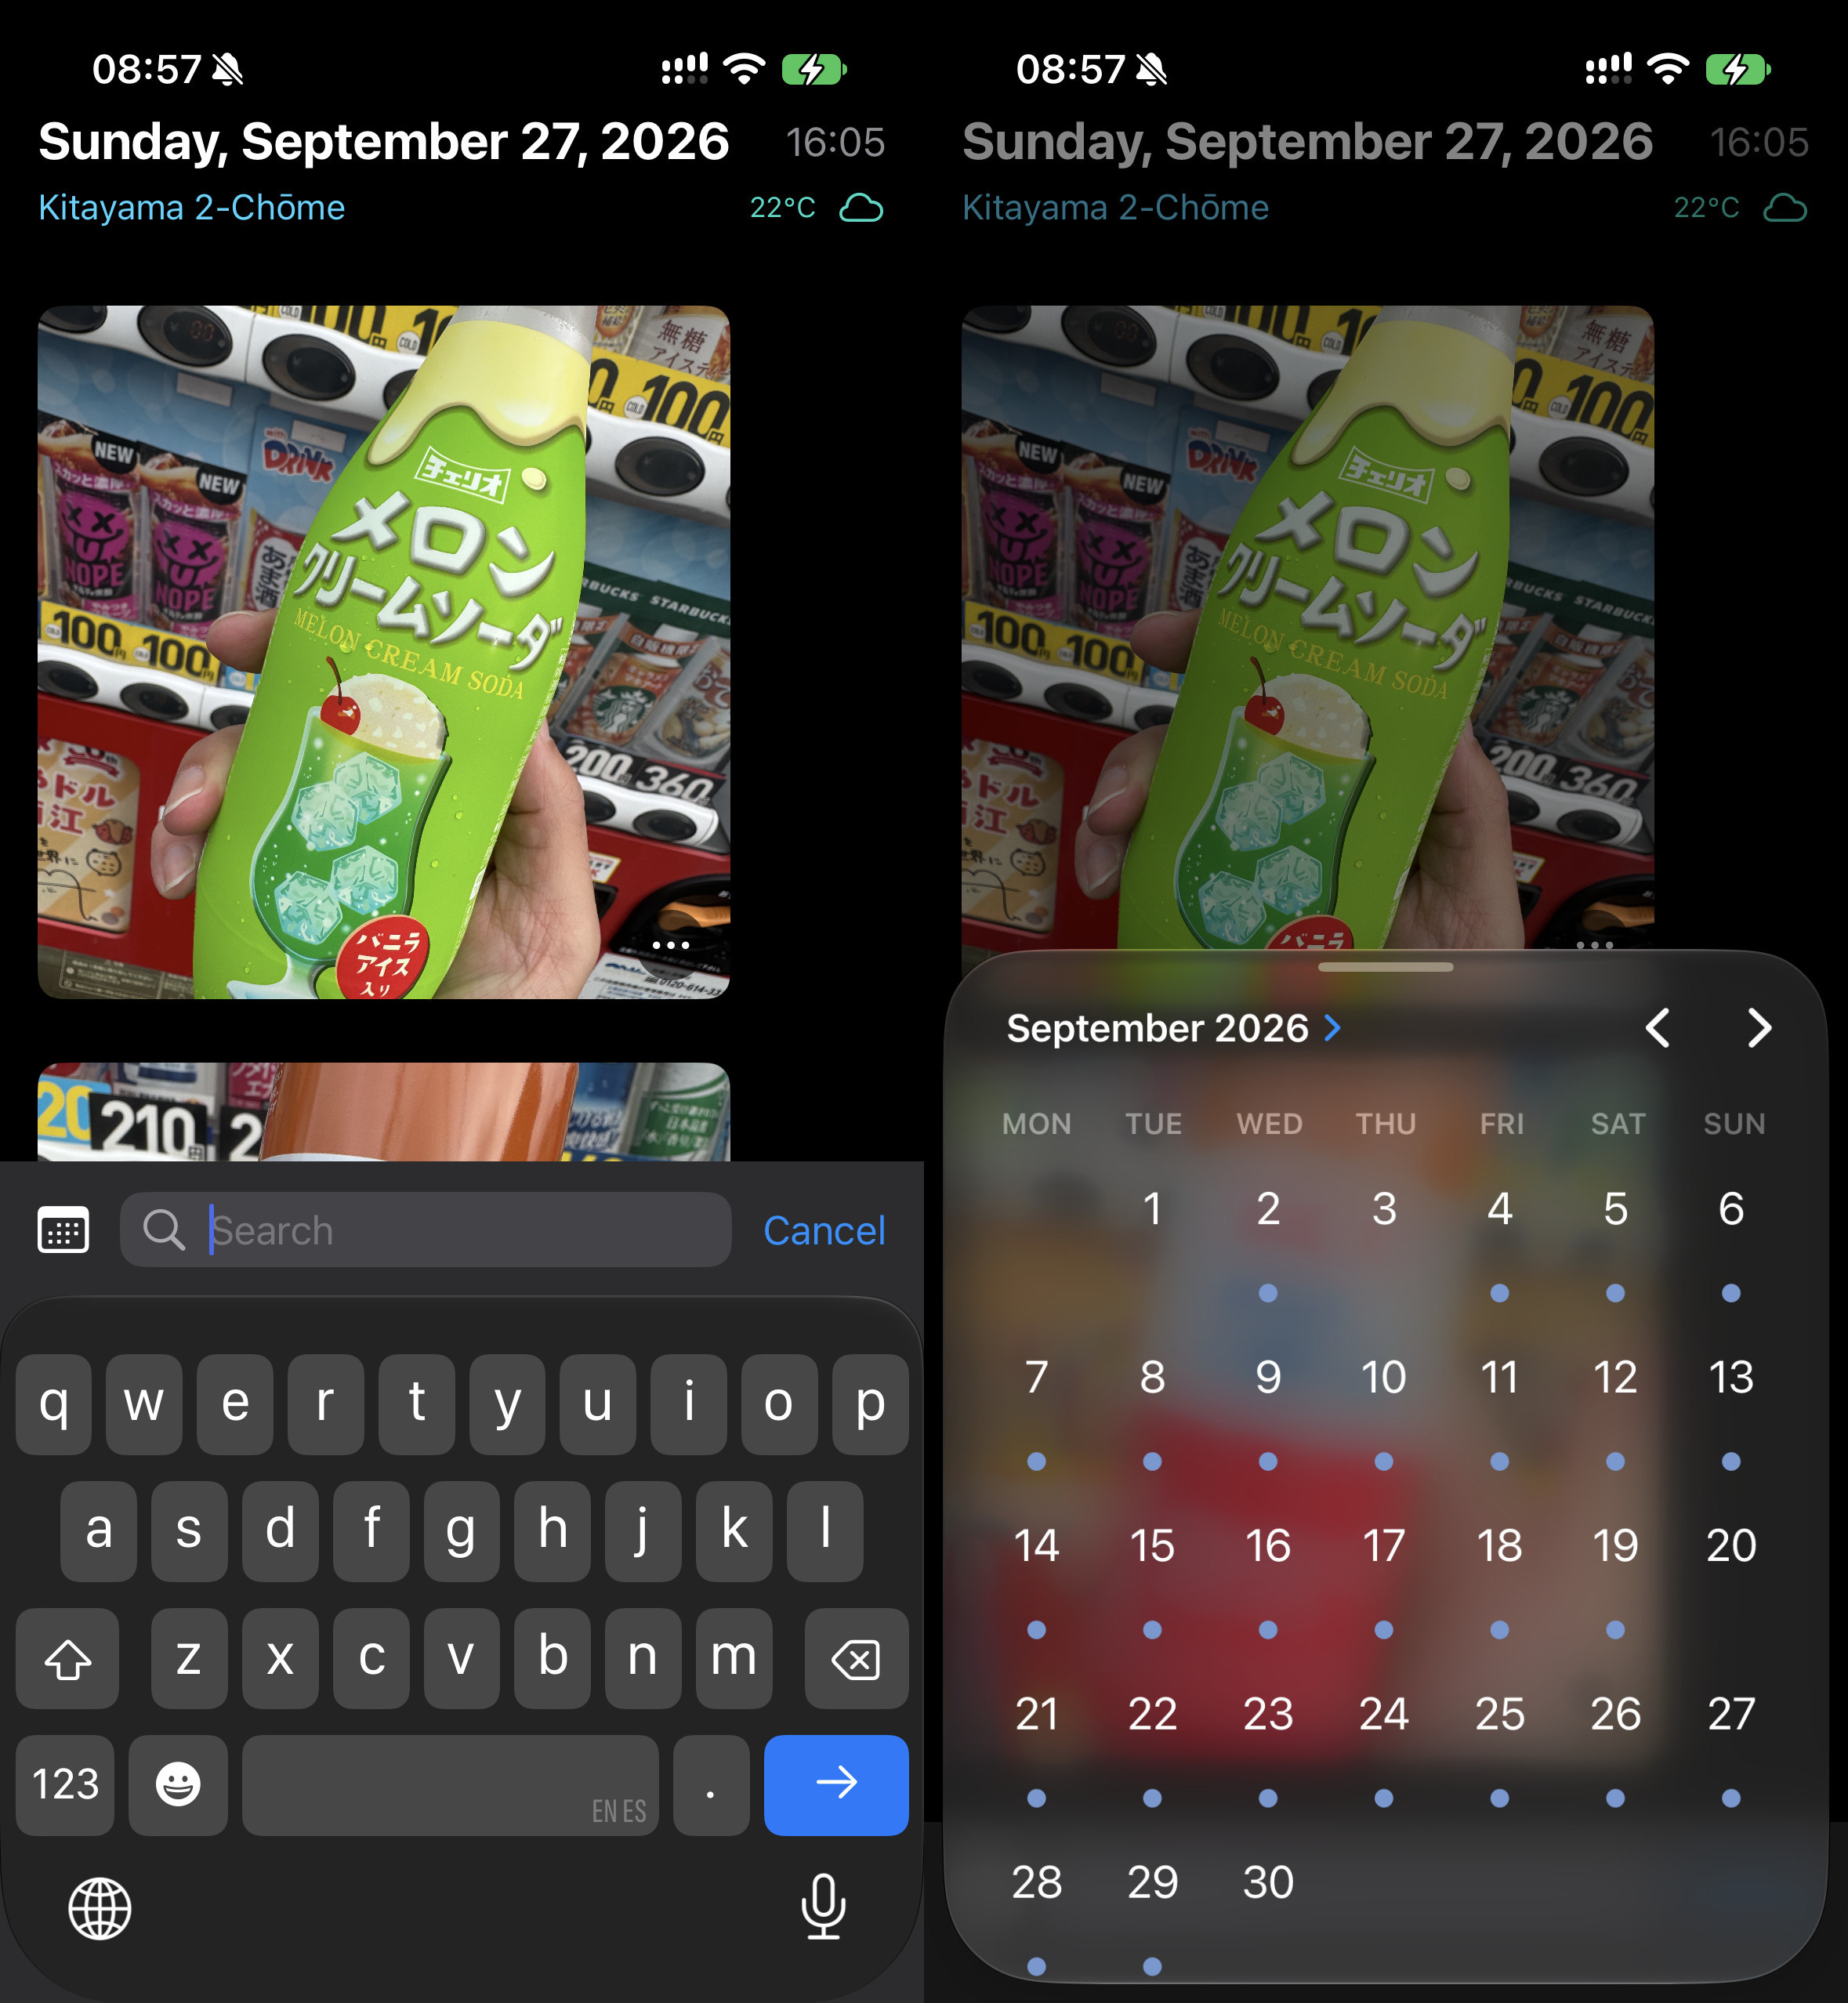
The other new significant feature is enhanced searching by date. In the search function you can use on: keyword with several different date formats to search for entries with a particular date. There’s also a calendar button that lets you choose the date from a calendar presentation if you prefer.
You may wonder why I have this entry tagged emacs. I consider Journelly intrinsically linked with Emacs because Journelly keeps its database in an Org file and that means that I can use Emacs and Org mode to search and edit that database. That doesn’t seem like much but I find myself doing it all the time. Journelly has become integrated into my Emacs workflow and become an important part of it.
In the mean time, those of you not in the Journelly beta program now have access to these updates. I can’t speak for Ramírez, of course, but if you’d like to be in the beta program, email Ramírez. He’ll probably be glad to add you.
-1:-- Journelly 1.5 (Post Irreal)--L0--C0--2026-11-11T16:37:06.000Z
Raw link: https://www.youtube.com/watch?v=BnFimCnnTzU
[ The stream will be recorded. You can watch it later. ]
Today I will develop a new package for Emacs. The idea is to have a quiz in a buffer and let the other pick their answer among predefined options. I expect this to take me more than three hours, but we will see.
As usual, I will keep the chat open and shall answer all questions.
UPDATE 2026-11-11 17:34 +0200: I created the Git repository right after the stream and also wrote the backronyms:
🔷 Consider making a donation.
-1:-- Emacs live ‘pub trivia’ package from scratch today 2026-11-11 at 14:00 Europe/Athens (Post Protesilaos)--L0--C0--2026-11-11T00:00:00.000Z
If you do a lot of exporting from Org Mode and hate all the rigmarole involved, Charles Choi may have precisely what you need. He’s just released Burnish, an app that largely automates the Org export process. The TL;DR is that when burnish-mode is active and a properly marked Org file is saved, the file is automatically exported and a preview is generated.
By default, the app supports exporting to:
but the app is highly configurable and you can add your own export types and export functions. The app comes with a user manual that explains how to do all this.
If you only occasionally export Org files, Burnish may be more than you need but if you export a lot of Org files, it may save you some time and effort.
-1:-- Burnish (Post Irreal)--L0--C0--2026-11-10T15:39:26.000Z
-1:-- yml.el: BLAZINGLY fast YAML parser for Emacs (Post Isa Mert Gurbuz)--L0--C0--2026-11-10T14:51:00.000Z
I’ve talked about journaling and its importance many times in this blog, but after not journaling for a while I have even more justification for it. At its core, journaling is where my brain grows and gets nourished. Without it, I’m just a dot in time, floating between past and future.
I don’t mean to sound depressing, but think about it. Experiencing life is important, but if you don’t reflect on it, you can’t fully grasp its meaning to you. You can be happy or sad, you can even learn a thing or two, but without having these experiences in front of you for a second pass, where you sit and connect the dots, how much of it can you really retain? If you’re new to journaling or considering it, I suggest you also look into one of my posts explaining its importance.
But let’s drop the philosophical coffee rant for a minute. What I want to get to is my process, after I realized I hadn’t journaled for a while, and the guides I set for myself to help with it.
My tools and techniques may be different from yours, so treat those with the personal flexibility you need. OK, here we go:
A bit of a ramble for Emacs folks (feel free to skip if you’re not one of those):
In Emacs, I also create past events I missed so they show up in my agenda. For example, let’s say I went grocery shopping and made a quick note about it in Journelly. In the evening, when I reflect and write my bullet points and pull my Journelly entries into the main journal (I might expand on this again), I also go to my events org file and write something like “grocery shopping @ Dan’s Fresh Market” along with an approximate time range I was there. The event file is included in the agenda (journal entries are not), and the timestamp shows me when I was there. That’s my quick reflection on what I did and where, when I want it in the future. Since I have the date in front of me, it’s also easy to find the journal entry for that day, since it’s reflected in the file name.
The above is a nice guide on how to write, but it doesn’t tell you what to write. Here is the other part of my quick self-guide. This is more a list of hints that should trigger the “hey, you might want to write about this” bulb in my head, so once again, change it so it fits your brain bulbs:
In general, this works well. If I leave home and go somewhere, it usually means I want to note it — the same goes when I do something with someone else, even if it’s a dinner at home. The idea to keep in mind is how unusual it is, or whether something different or important happened. As you can see, I left myself a comment that if it’s something I want to remember, I should note it (denote in my case) or turn it into a blog post, as I’m doing right now. Yep, this post is also a journal entry.
Emacs and org-mode are my essential tools when it comes to writing, and this blog is full of posts explaining how I write down things, but I wanted to make this post valuable for other folks as well. Still, I want to emphasize one final note: because Emacs is the best writing tool I have ever encountered, it also means I write more than I ever did before, which in turn means the benefits I mentioned at the start happen on a level that wouldn’t be possible with another tool (at least, not the way I see it). The point is, use something that works for you. Your baseline should be something you don’t think about much, like a reflex. Whether it’s a pocket notebook, quick self-recordings on your phone, or a text file saved somewhere, whatever it is: use it well. Use it often.
This is one of the benefits of journaling digitally: you can easily go back, press Enter a few times, and expand on something. With paper, this becomes harder to do. ↩︎
Expanding on digital vs. paper: on paper, you could write the bullet points first, then below, expand on each event. This will allow you to keep the bullet point list as a quick table of contents, or an index. If you like, you can add quick things to the bullet point itself: an underline below a topic you reflect on below (otherwise you just mentioned it), a star next to something you want to remember. I wrote more about my experience journalling in a pocket notebook, if you want to read more. ↩︎
-1:-- Getting back into journaling: my guide and triggers (Post TAONAW - Emacs and Org Mode)--L0--C0--2026-11-10T14:12:37.000Z
Journelly feels like tweeting, but for your eyes only.
A different take on note-taking or journaling for iOS, powered by plain text (Markdown + Org).
If you're an Emacs user, Journelly complements your Org journal file on the go.
Check out journelly.com for details.
Journelly v1.5's biggest gain is performance. It should bring you an overall snappier experience, especially on larger journals. This release also brings new search features.
A user reported migrating about ten years of journaling from Day One into Journelly: over 3,600 entries and thousands of images, converted from a Day One JSON export into Journelly's plain text format. With that much content, typing and navigating became sluggish.
Journelly v1.5 brings a nice round of performance work, so typing, saving, and navigating are now smoother for journals of all sizes. If you're considering a similar move, Journelly should now comfortably handle years of entries.
When you have entries from today's date in previous years, a new button appears on screen. Tap it to see what you were up to on this very day, years ago. The little badge shows how many matching entries were found.

Not your cup of tea? Hide the button via "Menu > View > On This Day."
Search now understands dates via a new on: filter:
on:2024 finds everything from 2024.on:2024-11 finds November 2024.on:November finds every November, any year.on:"November 3" (or on:11-03) finds every November 3rd, any year.on:"November 3, 2024" (or on:2024-11-03) finds that very day.Dates can be written in your own language too (on:"3 de noviembre", on:"11月3日"), and can be combined with regular search terms and hashtags (on:2024 #travel). Matching dates are highlighted in entry titles.
Prefer a calendar view? Tap the calendar button in the search bar to pick a day to search for. Days with entries are marked with a dot, offering a handy way to see when you wrote.

This release fills in some missing translations and improves the Simplified Chinese (简体中文) text.
Since launch, Journelly has remained a single-payment app. No subscriptions.
That said, sustainable development has been tough without regular downloads, which is why development has slowed down.
Help Journelly grow:
Hope you enjoy the v1.5 update.
Thank you for using Journelly and supporting indie development 💛💙❤️
-1:-- Journelly 1.5 released: faster all around (Post Alvaro Ramirez)--L0--C0--2026-11-10T00:00:00.000Z
This is a recollection of my comments from the EmacsConf 2026 community panel recording session this past weekend, where the panellists took turns answering the proposed questions, one minute per question per panellist.
In addition to the live Q&A session planned for Saturday 12 December 2026 during EmacsConf 2026, all Emacs users and community members are invited to share their thoughts on the panel questions or other questions before or after the conference.
https://emacsconf.org/2026/talks/community/
1. What made you start using Emacs, and what kept you using it?
I started using Emacs during my bachelor's studies. I actually learned about Vim first and was a Vim user, but I'd always found the configuration language (VimScript) a little bit clunky. Not long after, I discovered Emacs, and really loved reading and writing Emacs Lisp, so I stuck around.
In addition to reading and writing Elisp being fun and enjoyable for me, I love that Emacs has been a practical embodiment of software freedom, and I'm really fond of its surrounding culture of sharing freely. There's a lot to love and appreciate about Emacs, but as a practical personal example, I've been grateful for its excellent support for bidirectional text editing. It has empowered me to read and write in Persian, my mother tongue, with ease. (Persian has a right-to-left alphabet, like Arabic and Hebrew.)
2. What took you from using Emacs to actively contributing to the community - participating in forums, writing Elisp, organizing meetups, answering questions?
As I continued experimenting and writing bits and pieces of Elisp to scratch my own itches, I felt compelled to share them freely as a way of giving back to the community that gave me so much.
For me, the community and the people that make it up are the main deal. Emacs wouldn't be where it is and what it is today without its people, so besides programming contributions, I've tried to contribute in that area as well, for instance by reviving EmacsConf with Sacha Chua back in 2019.
3. How does Emacs show up for you in real life - colleagues, meetups, friends? How did those connections form?
I don't physically have people near me who use Emacs, but I've connected with many folks in our online communities, often starting with an email or IRC message. Some of those relationships started as acquaintanceship and were developed into true friendship over time, and I'm grateful to have had those friends with me.
4. If you know other software communities, what's one thing Emacs could learn from them?
I would encourage Emacs, our community, to focus on the people. We're living in particularly difficult times, with various kinds of hardships and uncertainty in our lives. Let's strive to treat each other with kindness, empathy, and mindfulness as we continue working together.
There are great examples of other free software communities whose members have banded together and are strengthening each other and their community, as well as cautionary ones where community members have been tiring and driving out their fellow members. We could learn valuable lessons from both in how to take care of our people and ourselves.
5. What's one concrete thing you wish existed in the Emacs community a year from now?
I echoed the sentiments of my fellow panellists Prot and Til about doing more of the same in terms of continuing to uphold the standards of excellence and perseverance. Also, drawing inspiration from what bashbunni said, to lower the barriers of entry for people, for example through organizing different kinds of events, and experimenting with ways to make people's lengthy, elaborate Emacs configurations more tangible and accessible to others, to share various workflows and demonstrate what's possible with Emacs.
I look forward to your thoughts on these and other community-related questions.
Take care, and so long for now.
-1:-- EmacsConf 2026 community panel - my comments (Post Amin Bandali)--L0--C0--2026-11-09T21:57:44.000Z
The Emacs Carnival topic for November is: Discovery of Emacs Features.
My biggest new feature discovery method is Emacs News. Normally I'll clear every other item out of my RSS feeds and then dedicate a single reading session to reading Emacs News because I open up so many links to read that it needs its own dedicated session.
Being fairly new in my Emacs journey I find new interesting features all the time, my biggest issue is the time to add them to me workflows. I've been in Emacs long enough now that I dream of being able to move most of my work into it. I open Obsidian to write and wonder why I'm not writing in Emacs. I have Kitty open and wonder why I don't just use Emacs?
There is so much to learn in Emacs, and so many things it could replace I'm sort of stuck wondering where to even start.
The newest feature I'm trying to wrap my head around is workspaces. I'd like to retire Kitty and Zellij to focus on Emacs, but navigation in Zellij is so ingrained in my muscle memory I need to find some way to make it that seamless in Emacs, and I haven't quite found it yet.
-1:-- Discovering Emacs Features - November Emacs Carnival (Post Curtis McHale)--L0--C0--2026-11-09T19:53:00.000Z
-1:-- A tip on removing functions from hooks interactively (Post Marcin Borkowski)--L0--C0--2026-11-09T18:41:00.000Z
Org mode is often celebrated for its ability to “write once, export anywhere.”
With such power comes added complexity: Exporting a file requires the user to typically go through a multi-step process (e.g. C-c C-e <some char> <some other char>). If the user is concerned with previewing changes to their file, then another step of viewing the exported output is required. Having to do this repeatedly gets tedious fast. Such is the motivation for Burnish.
Burnish is a new Elisp package I’ve made to automate the export and viewing of an Org file. It provides an Emacs minor mode (burnish-mode) that when enabled, does the following upon save of an Org file:
Most all of the default backends provided by Org mode are supported by Burnish. That said, Burnish is highly configurable, allowing for users to define for themselves the export and view workflow for existing or third party backends.
Read the Burnish User Guide to learn more about it. As it is new, feedback is always welcome. If you really find it useful, please show your gratitude by buying me a coffee.
Burnish v1.0 is now available on MELPA.
-1:-- Announcing Burnish (Post Charles Choi)--L0--C0--2026-11-09T16:15:00.000Z
More good news on the Emacs front. Sean Whitton writes to say that the Emacs 31.1.90 pretest is available. The Emacs point releases are generally to fix bugs and maybe refine an existing functionality but you shouldn’t expect any major new features. That will have to wait for Emacs 32. As always, the developers are asking for our help to test the release and let them know if we encounter any problems building or using it.
Be aware that there are some typos in Whitton’s post. In the first place, the pretest will eventually become Emacs 31.2 (not 31.1). More importantly, there are also typos in the URLs for the release. The correct URL is https://alpha.gnu.org/gnu/emacs/pretest/emacs-31.1.90.tar.xz and similarly for the signature file.
My usual thanks to the Emacs developers who work so hard for us and give us so much. As I always say, if one of us finds ourselves in the same bar as one of the devs, we’re buying.
-1:-- Emacs 31.1.90 Pretest (Post Irreal)--L0--C0--2026-11-09T15:23:59.000Z
: Added EmacsSF this Saturday.
The Emacs Carnival theme for November 2026 is Discovering Emacs features. Thanks to Raymond Zeitler for hosting. Looking forward to reading your thoughts!
There is a very long discussion about Human Emacs and LLM-assisted contributions on emacs-devel. It is a lot. I don't want to throw fuel on the fire. I'm mentioning it because it's a topic that a lot of people care very strongly about, and because there's a subdiscussion about slavery that might ripple out into the wider community. If you do decide to weigh in, please be kind and thoughtful. Thank you!
Links from reddit.com/r/emacs, r/orgmode, r/spacemacs, Mastodon #emacs, Bluesky #emacs, Hacker News, lobste.rs, programming.dev, lemmy.world, lemmy.ml, planet.emacslife.com, YouTube, the Emacs NEWS file, Emacs Calendar, and emacs-devel. Thanks to Andrés Ramírez for emacs-devel links. Do you have an Emacs-related link or announcement? Please e-mail me at sacha@sachachua.com. Thank you!
You can e-mail me at sacha@sachachua.com.
-1:-- 2026-11-09 Emacs news (Post Sacha Chua)--L0--C0--2026-11-09T12:56:50.000Z
Org’s new LaTeX preview system is out—time to celebrate! Not only does this mean that one can now enjoy reasonable previews without having to use a forked version of Org, but given that we are using the infinitely extensible text editor, this preview functionality can be used virtually everywhere. Let’s hack it into elfeed.
While its creator seems to disagree,
I still believe that elfeed is by far the best feed reader in existence.1
As RSS feeds are so static, it also feels like the ideal candidate to get a feeling for adapting org-latex-preview to other major modes.2
Previewing LaTeX is quite important when one is subscribed to arXiv’s feeds,3 as titles and descriptions obviously contain maths sometimes:
The only function that we’ll need to get these previews working is org-latex-preview-place.
It has two mandatory arguments, processing-type and entries.
The latter is just a list of buffer positions (beg end) in which to find the LaTeX fragments,
while the former sets the type of transformation you want to use.4
This means that the main thing we have to do is to collect all of the fragments:
(defun elfeed-latex-preview ()
"LaTeX preview the current elfeed buffer."
(interactive)
(save-excursion
(with-syntax-table (copy-syntax-table)
(modify-syntax-entry ?- ".") ; $x$-y is valid
(when-let* ((entries
(cl-loop
for (_ re pos _) in org-latex-regexps
append (cl-loop
initially (goto-char (point-min))
while (re-search-forward re nil t)
collect (list (match-beginning pos)
(match-end pos))))))
(org-latex-preview-place 'dvisvgm entries)))))
The cl-loop code is so close to natural language that I feel like it should be obvious even if you’ve never seen such a loop expression.
The only thing that’s slightly tricky is that Org doesn’t really recognise constructs of the form $x$-y as valid
LaTeX—as far as I know because it conflicts with one of its million syntax rules.
To hack around this, as I still want to use org-latex-regexps,5
we can treat the dash as punctuation while looking for fragments, since a punctuation character following the closing dollar is permitted.
To hook this function into elfeed, we can simply check if the arXiv view is selected in either elfeed-search-mode or elfeed-show-mode,
and then just call elfeed-latex-preview on the buffer:
(defun elfeed-latex (&rest _)
(when (or (string-match-p "arXiv" elfeed-search-filter)
(and elfeed-show-entry
(memq 'arXiv (elfeed-entry-tags elfeed-show-entry))))
(elfeed-latex-preview)))
(add-hook 'elfeed-search-update-hook #'elfeed-latex)
(add-hook 'elfeed-show-update-hook #'elfeed-latex)
(advice-add 'elfeed-search-update-entry :after #'elfeed-latex)
As the names suggest, the two hooks are for when things change in elfeed-search-mode and elfeed-show-mode, respectively.
The hooks for entering those major modes seem to run too early for LaTeX previewing to have any effect.
The advice is needed since opening a feed entry with elfeed-search-show-entry does update and redraw its title (e.g., marking it read),
but sadly elfeed bypasses the usual search-update machinery, and thus this doesn’t activate any of the required hooks.
Pretty feeds, at last.
Certainly better than a vibecoded C++ GUI thing…↩︎
Not that it makes much of a difference; the API as I see it is essentially plug-and-play.↩︎
If you can stomach the arXiv in 2026, that is. I know enough people who’ve just given up at this point, and are just scanning whose name they recognise. While this usually is a good way to filter out slop, it’s honestly quite worrying—but that’s not what this post is supposed to be about, so let’s stop here.↩︎
dvisvgm, dvipng, or imagemagick, at the time of writing.↩︎
Yes, the subset of TeX allowed in arXiv titles and descriptions is so minimal that one could probably get away with manually curated regexps.
However, this would result in more code, so this approach seems simpler.
It also has the nice benefit that some people don’t care what the arXiv allows or not, and will use \(…\)-style brackets, even though those are not rendered on the website.↩︎
-1:-- LaTeX Previews for Elfeed (Post Tony Zorman)--L0--C0--2026-11-09T00:00:00.000Z
After last night’s post, I realised I was probably just getting too invested in somehow using imdb for the “who’s that actor, anyway?” command for my Emacs-based video player.
Not only is it an extremely fragile setup that’s gonna stop working, but it’s also very slow — it takes half a minute to return the actor profile images.
So I just implemented a tmdb API shim and then I ask it for the actor profile photo instead. tmdb doesn’t have as large a data base, but… The API is free (for non-commercial use) and is extremely easy to use.
Things are now faster:
The main wait is from the response from the LLM — I’m using gemini-3.8-flash. I’ve tried gemini-3.1-flash-lite, and it’s much faster… but gives the wrong result most of the time. No, that’s not Roy Scheider, Gemini!
So now the setup is less Rube Goldberguesque. Sort of:
Couldn’t be simpler.
-1:-- OK, OK, I’ll just use tmdb (Post Lars Ingebrigtsen)--L0--C0--2026-11-08T11:48:11.000Z
The following is my recollection of comments I made during the recording of the EmacsConf 2026 community panel (the Q&A session will happen live during the conference): https://emacsconf.org/2026/talks/community/.
It is not a transcript though it is true in spirit.
We had 1 minute per answer.
1 What made you start using Emacs, and what kept you using it?
It is the potential of interconnectedness. With Emacs I can draw linkages between different parts of my workflow, such as from the email client or RSS feed reader to the agenda. It also is the transferability of skills: when I write a custom function that works, say, for programming then that same function can be used while writing emails (e.g. a “focus mode” that also enlarges the font size and switches the cursor from a box to a bar shape). Software freedom is another important consideration because it empowers me to do my personal computing as I want and Emacs is by far the best in this regard.
2 What took you from using Emacs to actively contributing to the community - participating in forums, writing Elisp, organizing meetups, answering questions?
One is organic. By using Emacs, I configure it by programming it. The more I do that, the more I learn how to write Emacs Lisp. I eventually reach a point where I can produce patches for existing libraries and also develop my own packages. This organic growth blurs the lines between user and developer as well as passive user and active contributor. The other part is a sense of stewardship. I am inspired to give back to the commons. I recognise that I benefit from the freedom I receive and thus assume the duty of empowering others to do the same.
3 How does Emacs show up for you in real life - colleagues, meetups, friends? How did those connections form?
I talk to Emacs users on video calls. I have even met a few in person who wanted to visit me for other reasons as well (one case was a funny story about “a Greek philosopher who is actually alive”). Those connections form naturally over time. I find that there is concordance of spirit. People who use Emacs have some character traits in common. I can see a little bit of myself reflected in them and a little bit of them reflected in me. Each person has their individuality. Though we all answer a certain call that compels us to explore the depths and the lengths.
4 If you know other software communities, what’s one thing Emacs could learn from them?
I think this is not specific to software. What is true for the Emacs community is true for communities in general. It is about the potential for participation. People must feel that they are part of something greater than themselves; something that will be there even after they are gone. Thriving communities create involvement through a variety of means and thus engender the belief that one can move from the notional periphery to the centre, from observer to member. Concretely, livestreams, bug squashing events, social gatherings, virtual or in-person conferences, and even face-to-face meetings, all help create a sense of belonging and togetherness.
5 What’s one concrete thing you wish existed in the Emacs community a year from now?
Uphold the standard of excellence. Keep doing what we do and increase it in intensity and/or frequency wherever possible. Those who chase fads have a spectacular rise followed by an equally spectacular fall. What has made Emacs—and communities in general—stand the test of time is unflinching commitment to their core tenets. Those are the qualities that made them interesting in the first place. In practice, this is about focusing on quality and letting the quantity come about organically. People come and go. To prioritise quantity is to attract opportunists and, in the process, to erode the soil we stand on.
🔷 Consider making a donation.
-1:-- EmacsConf 2026 community panel comments I made (Post Protesilaos)--L0--C0--2026-11-08T00:00:00.000Z
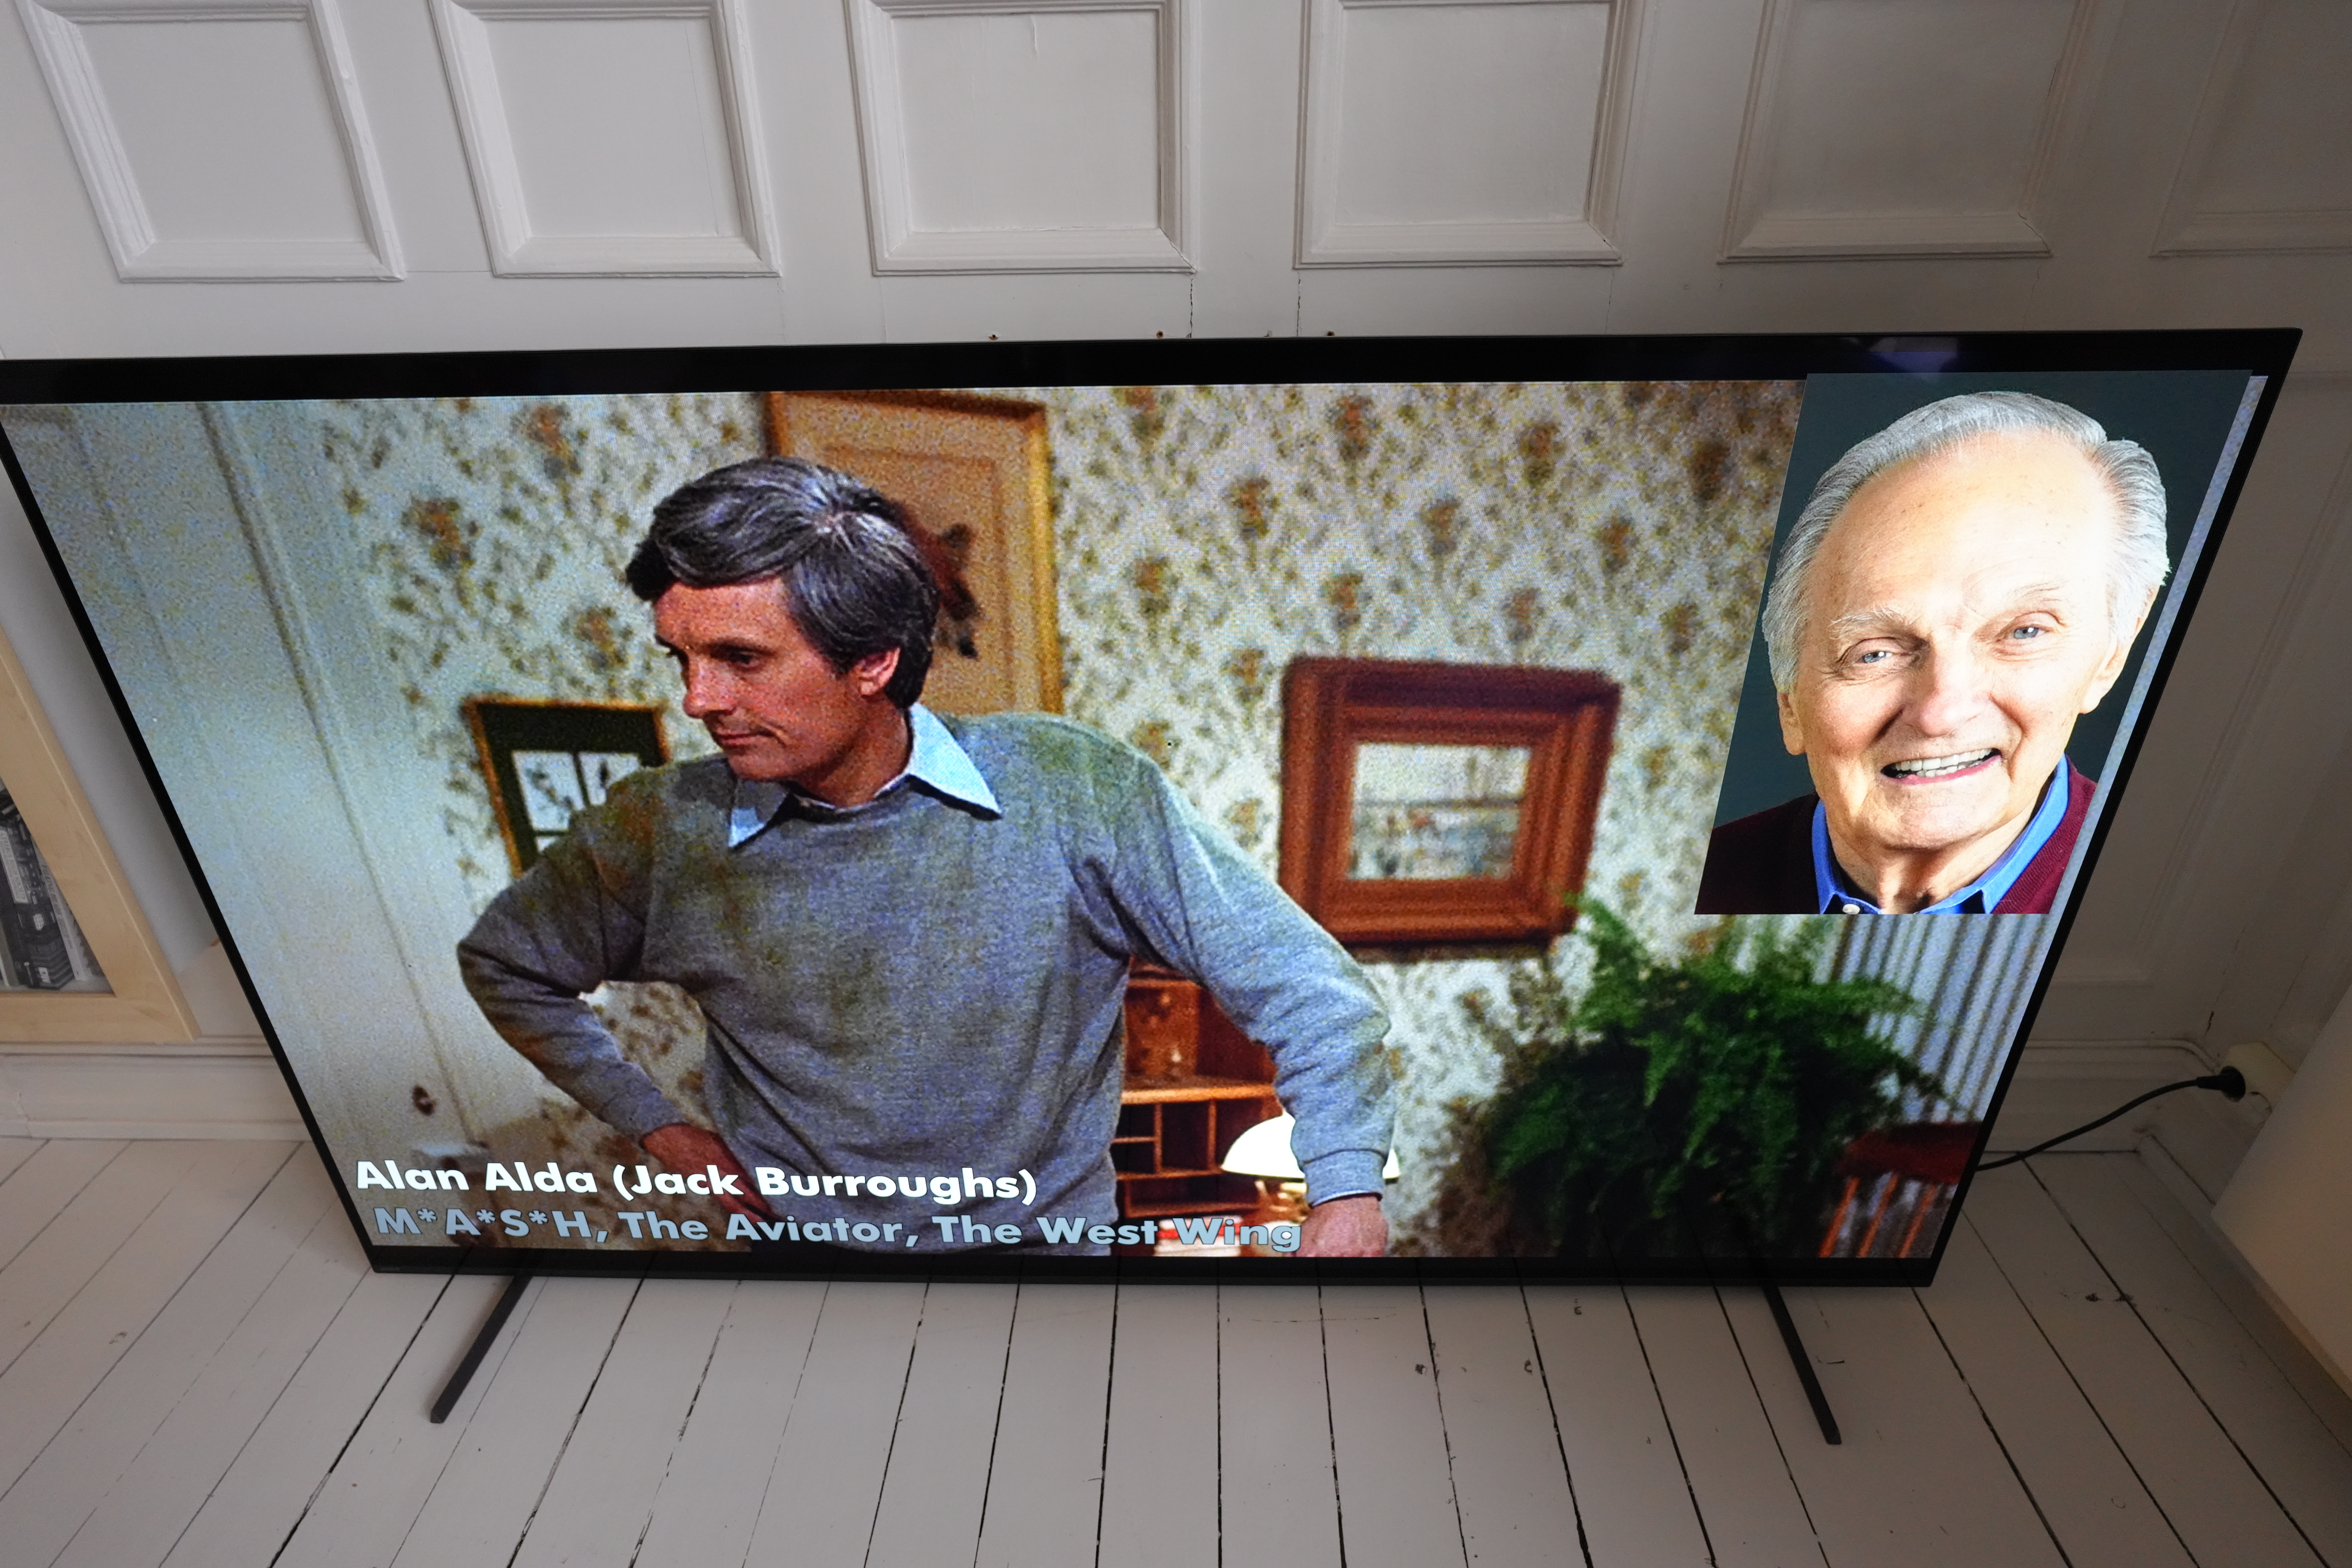
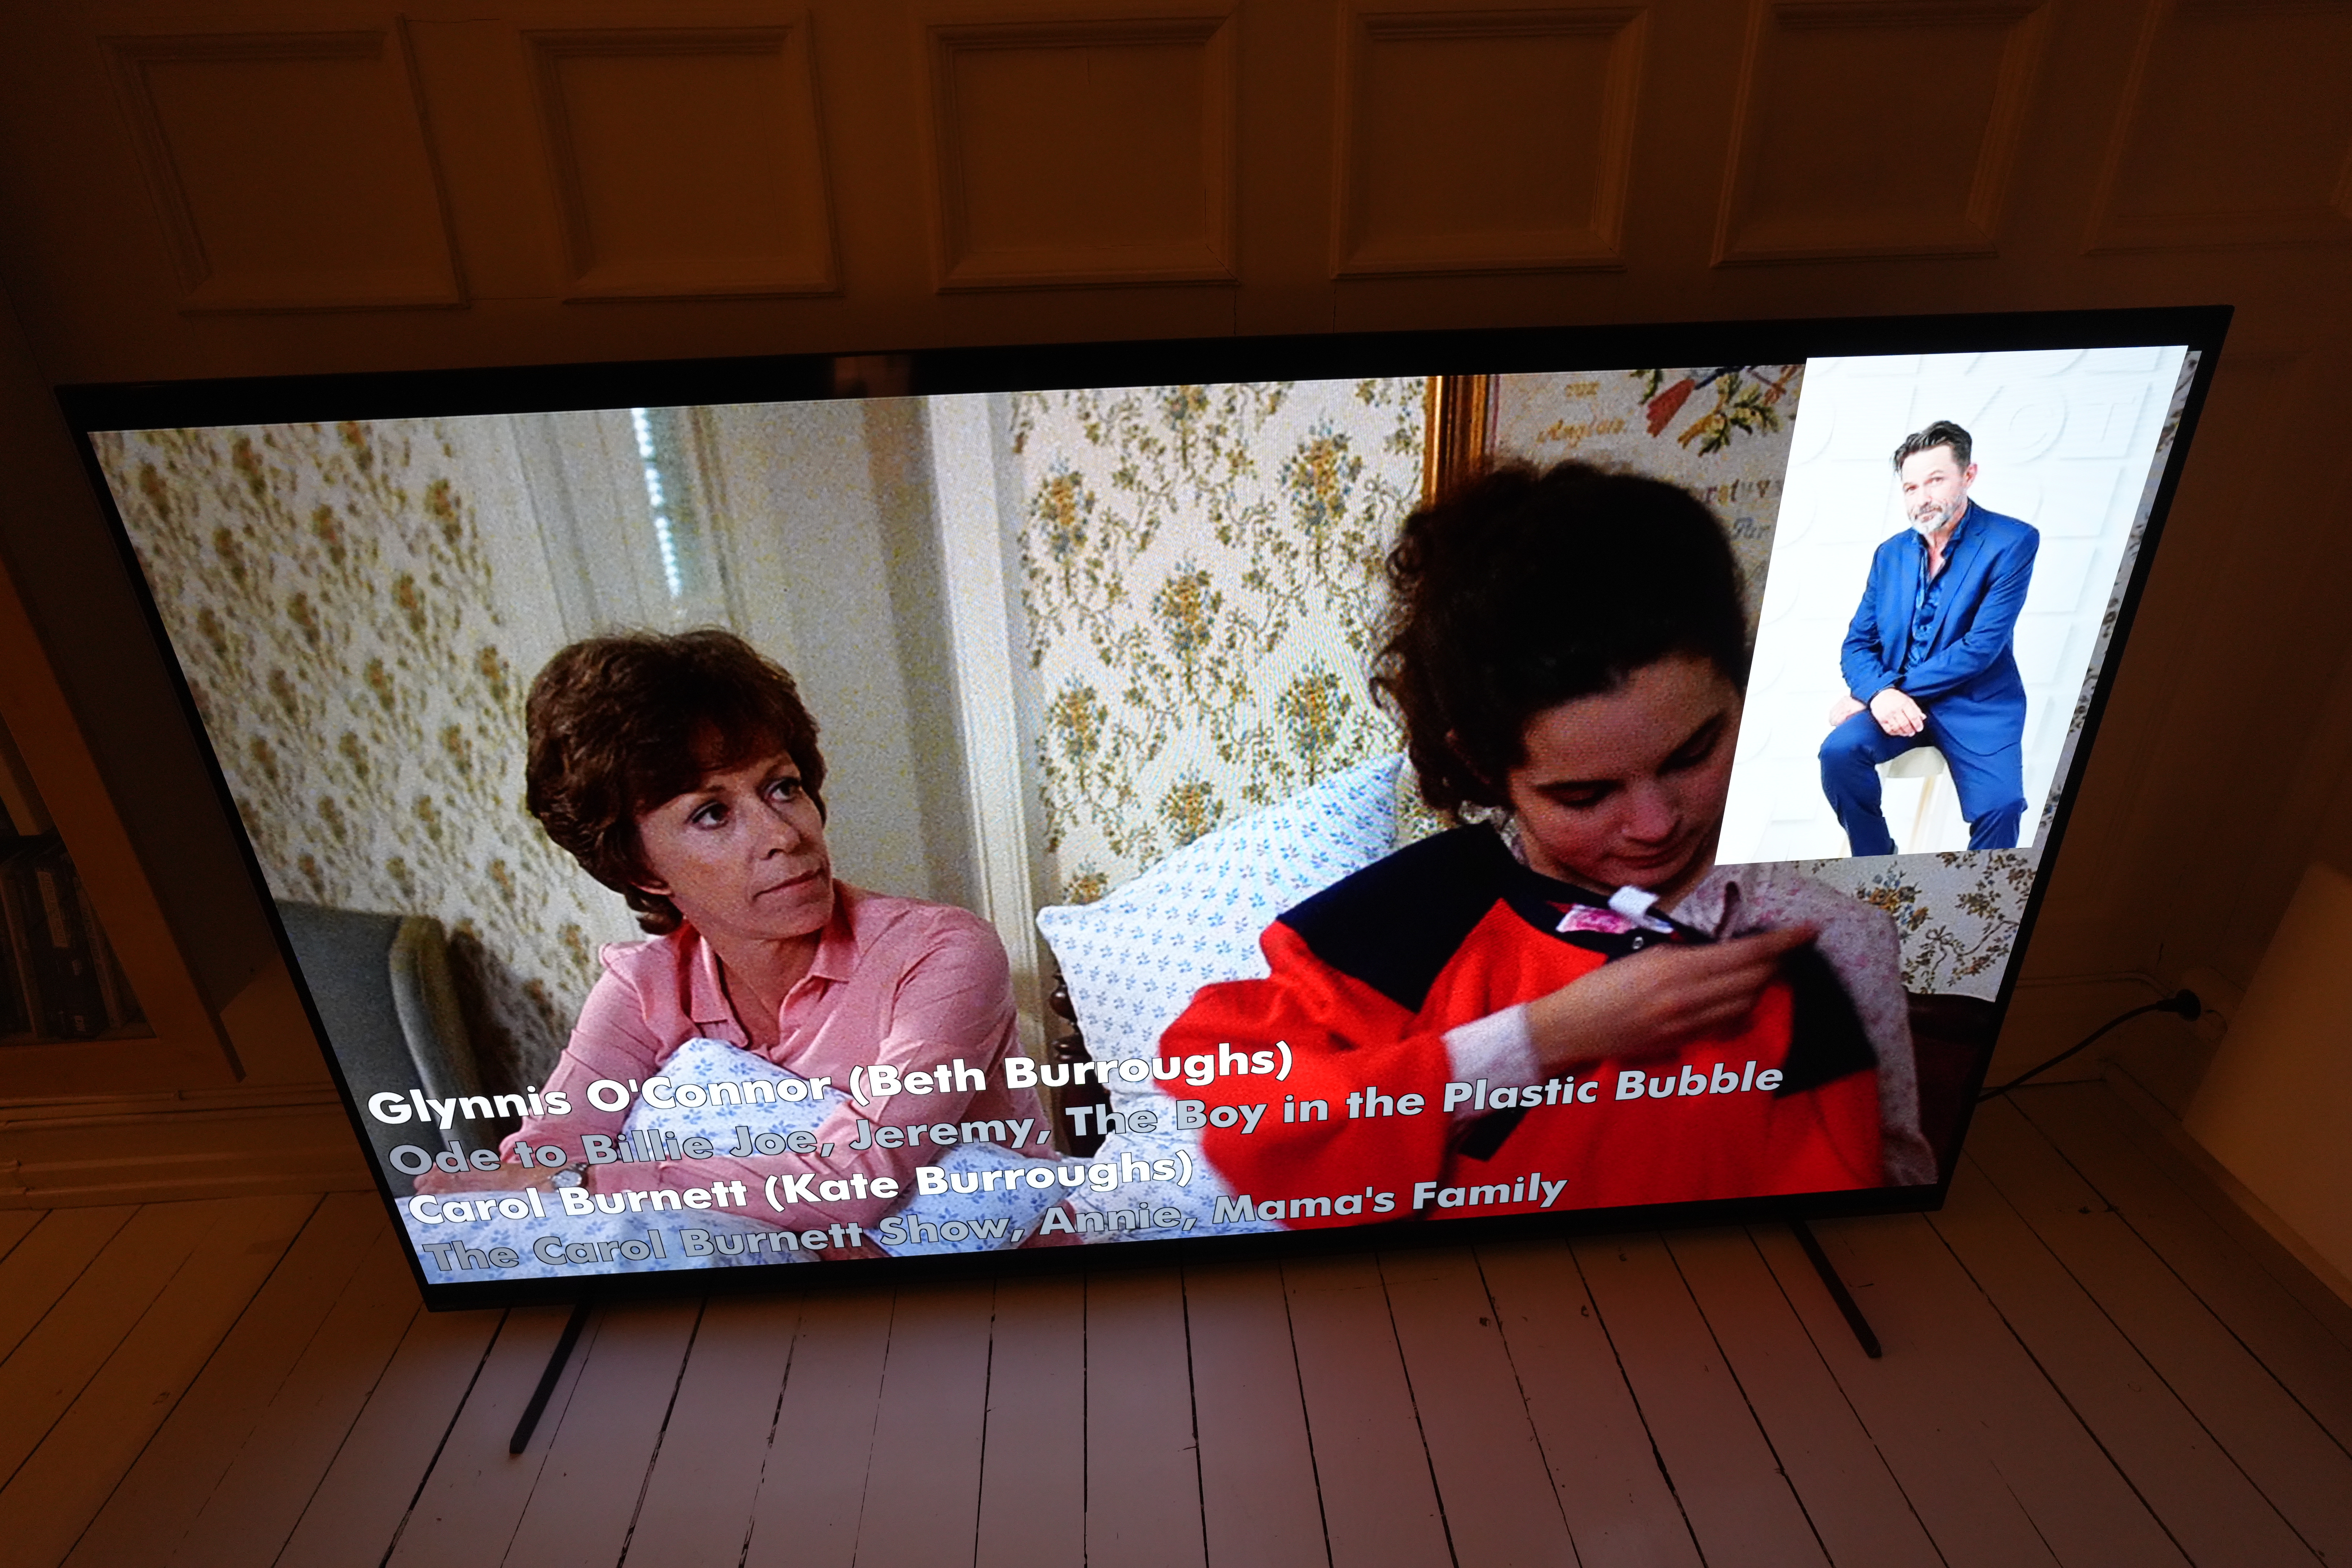
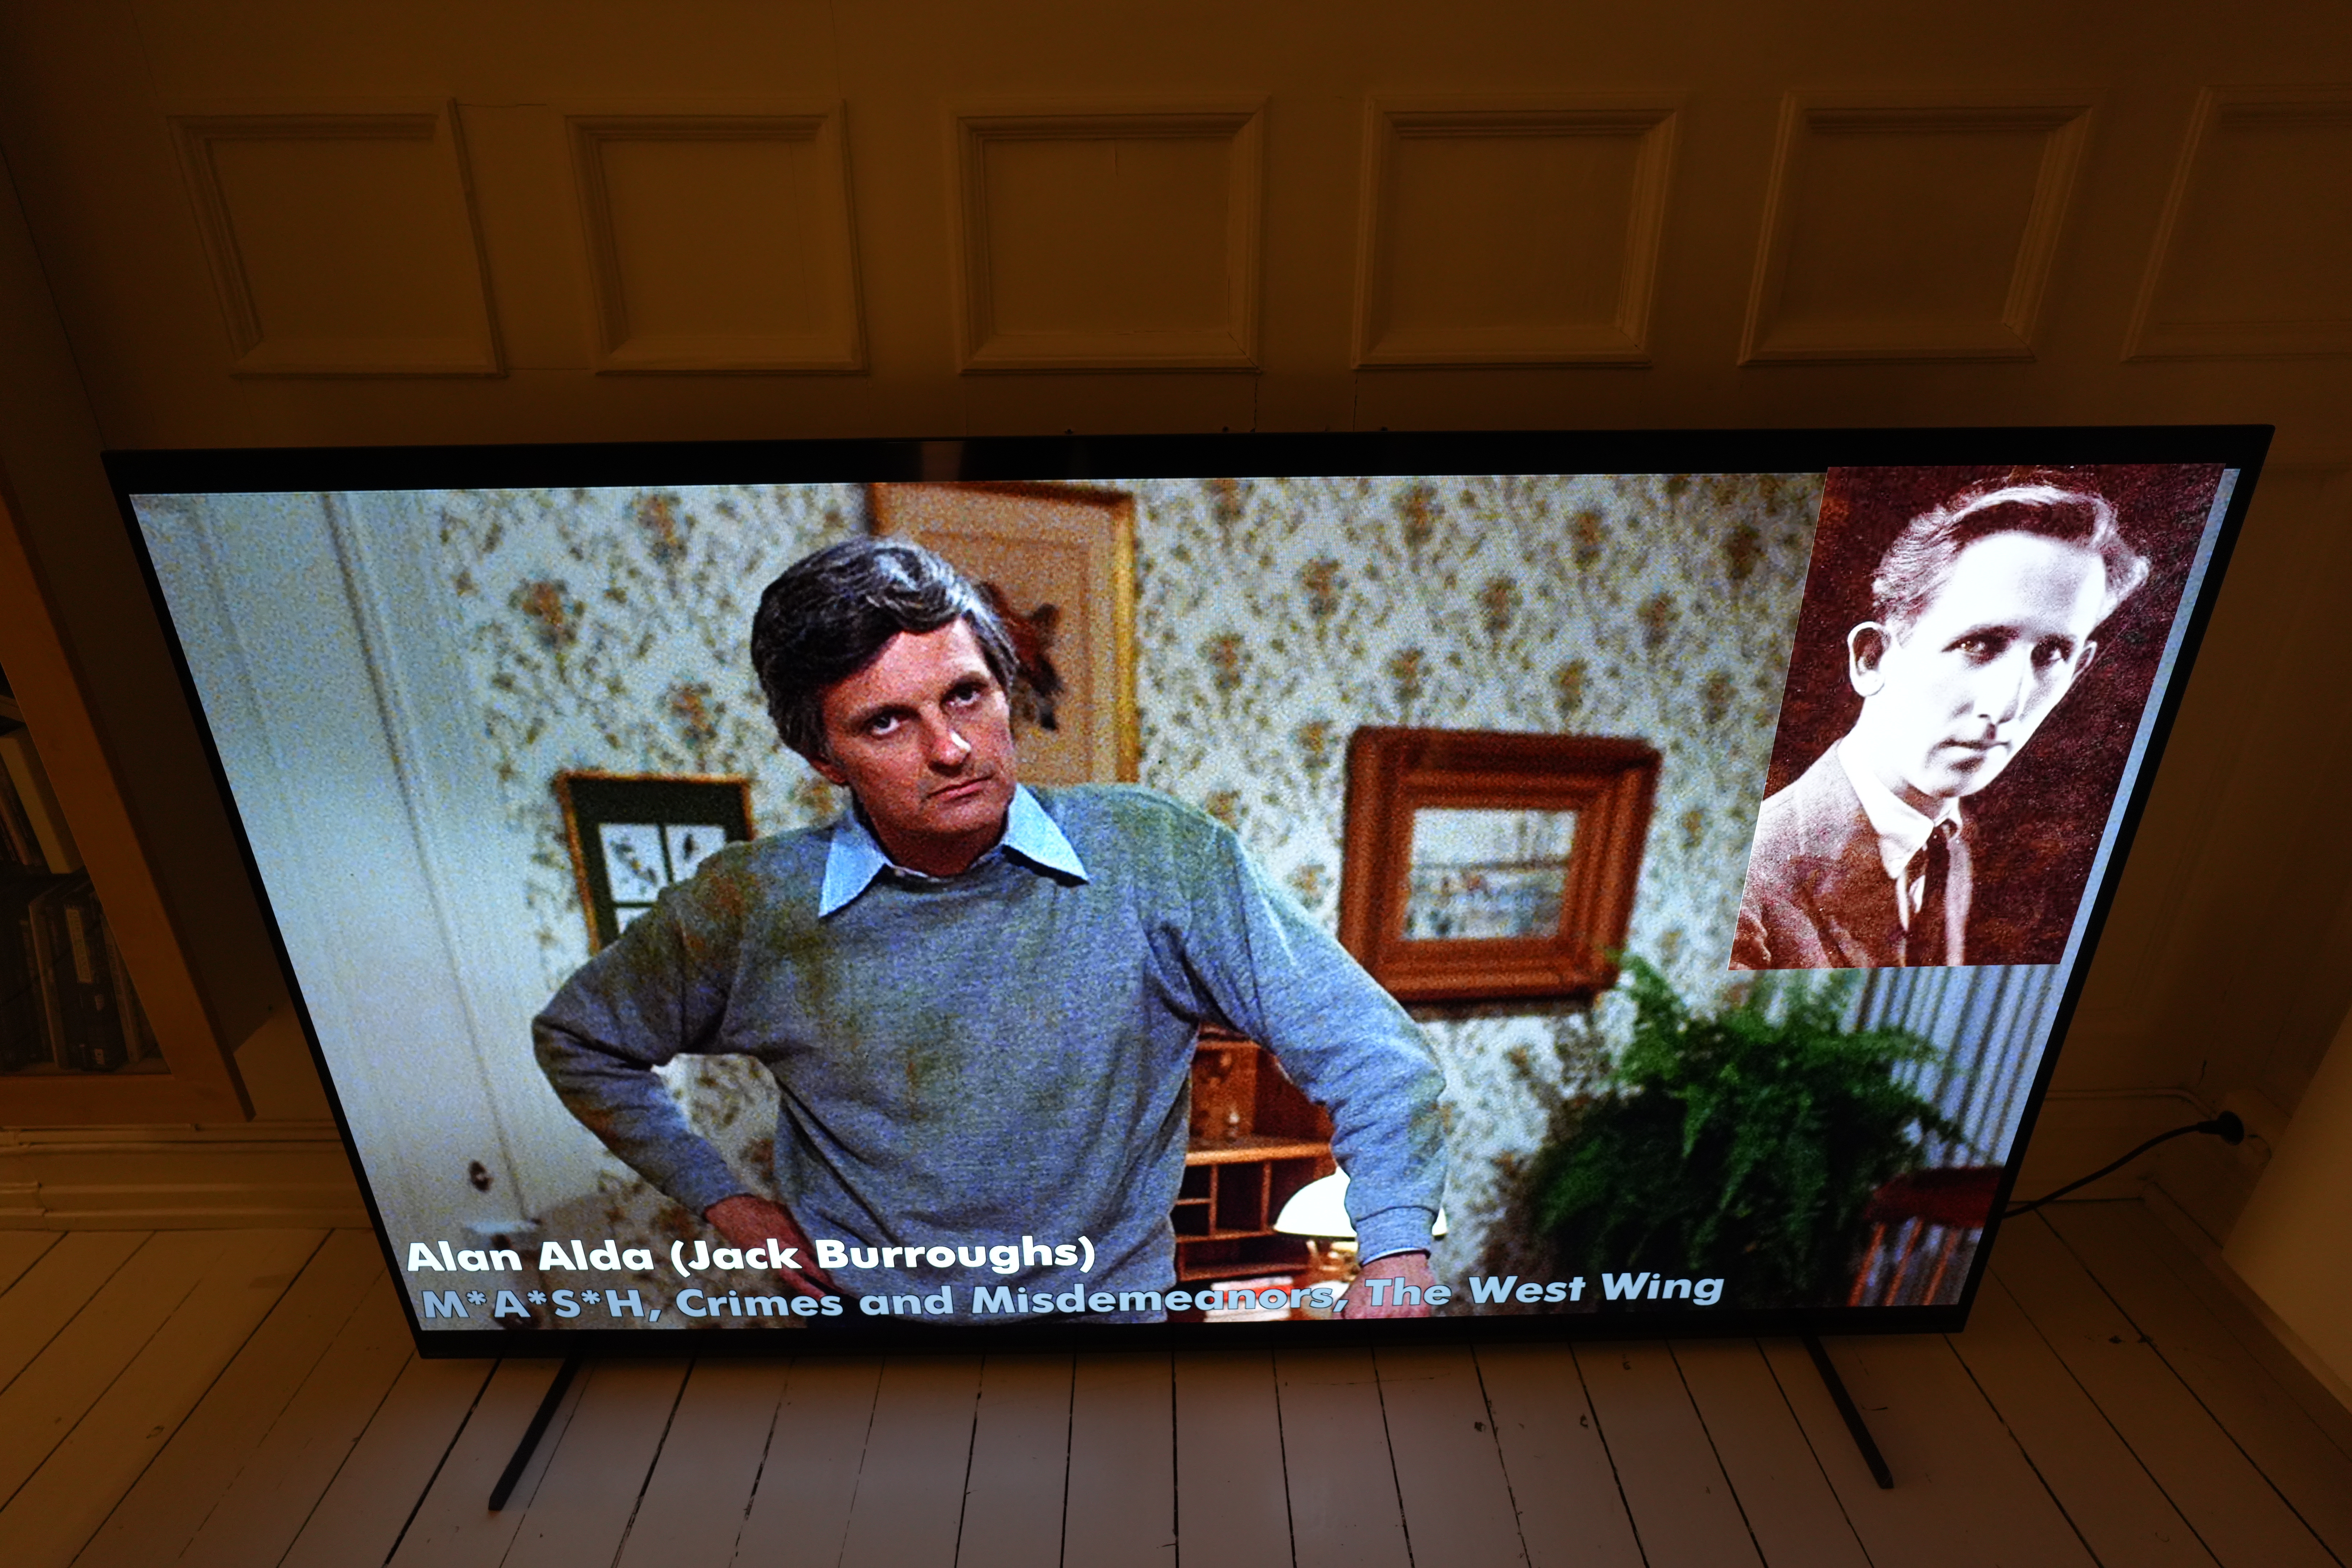
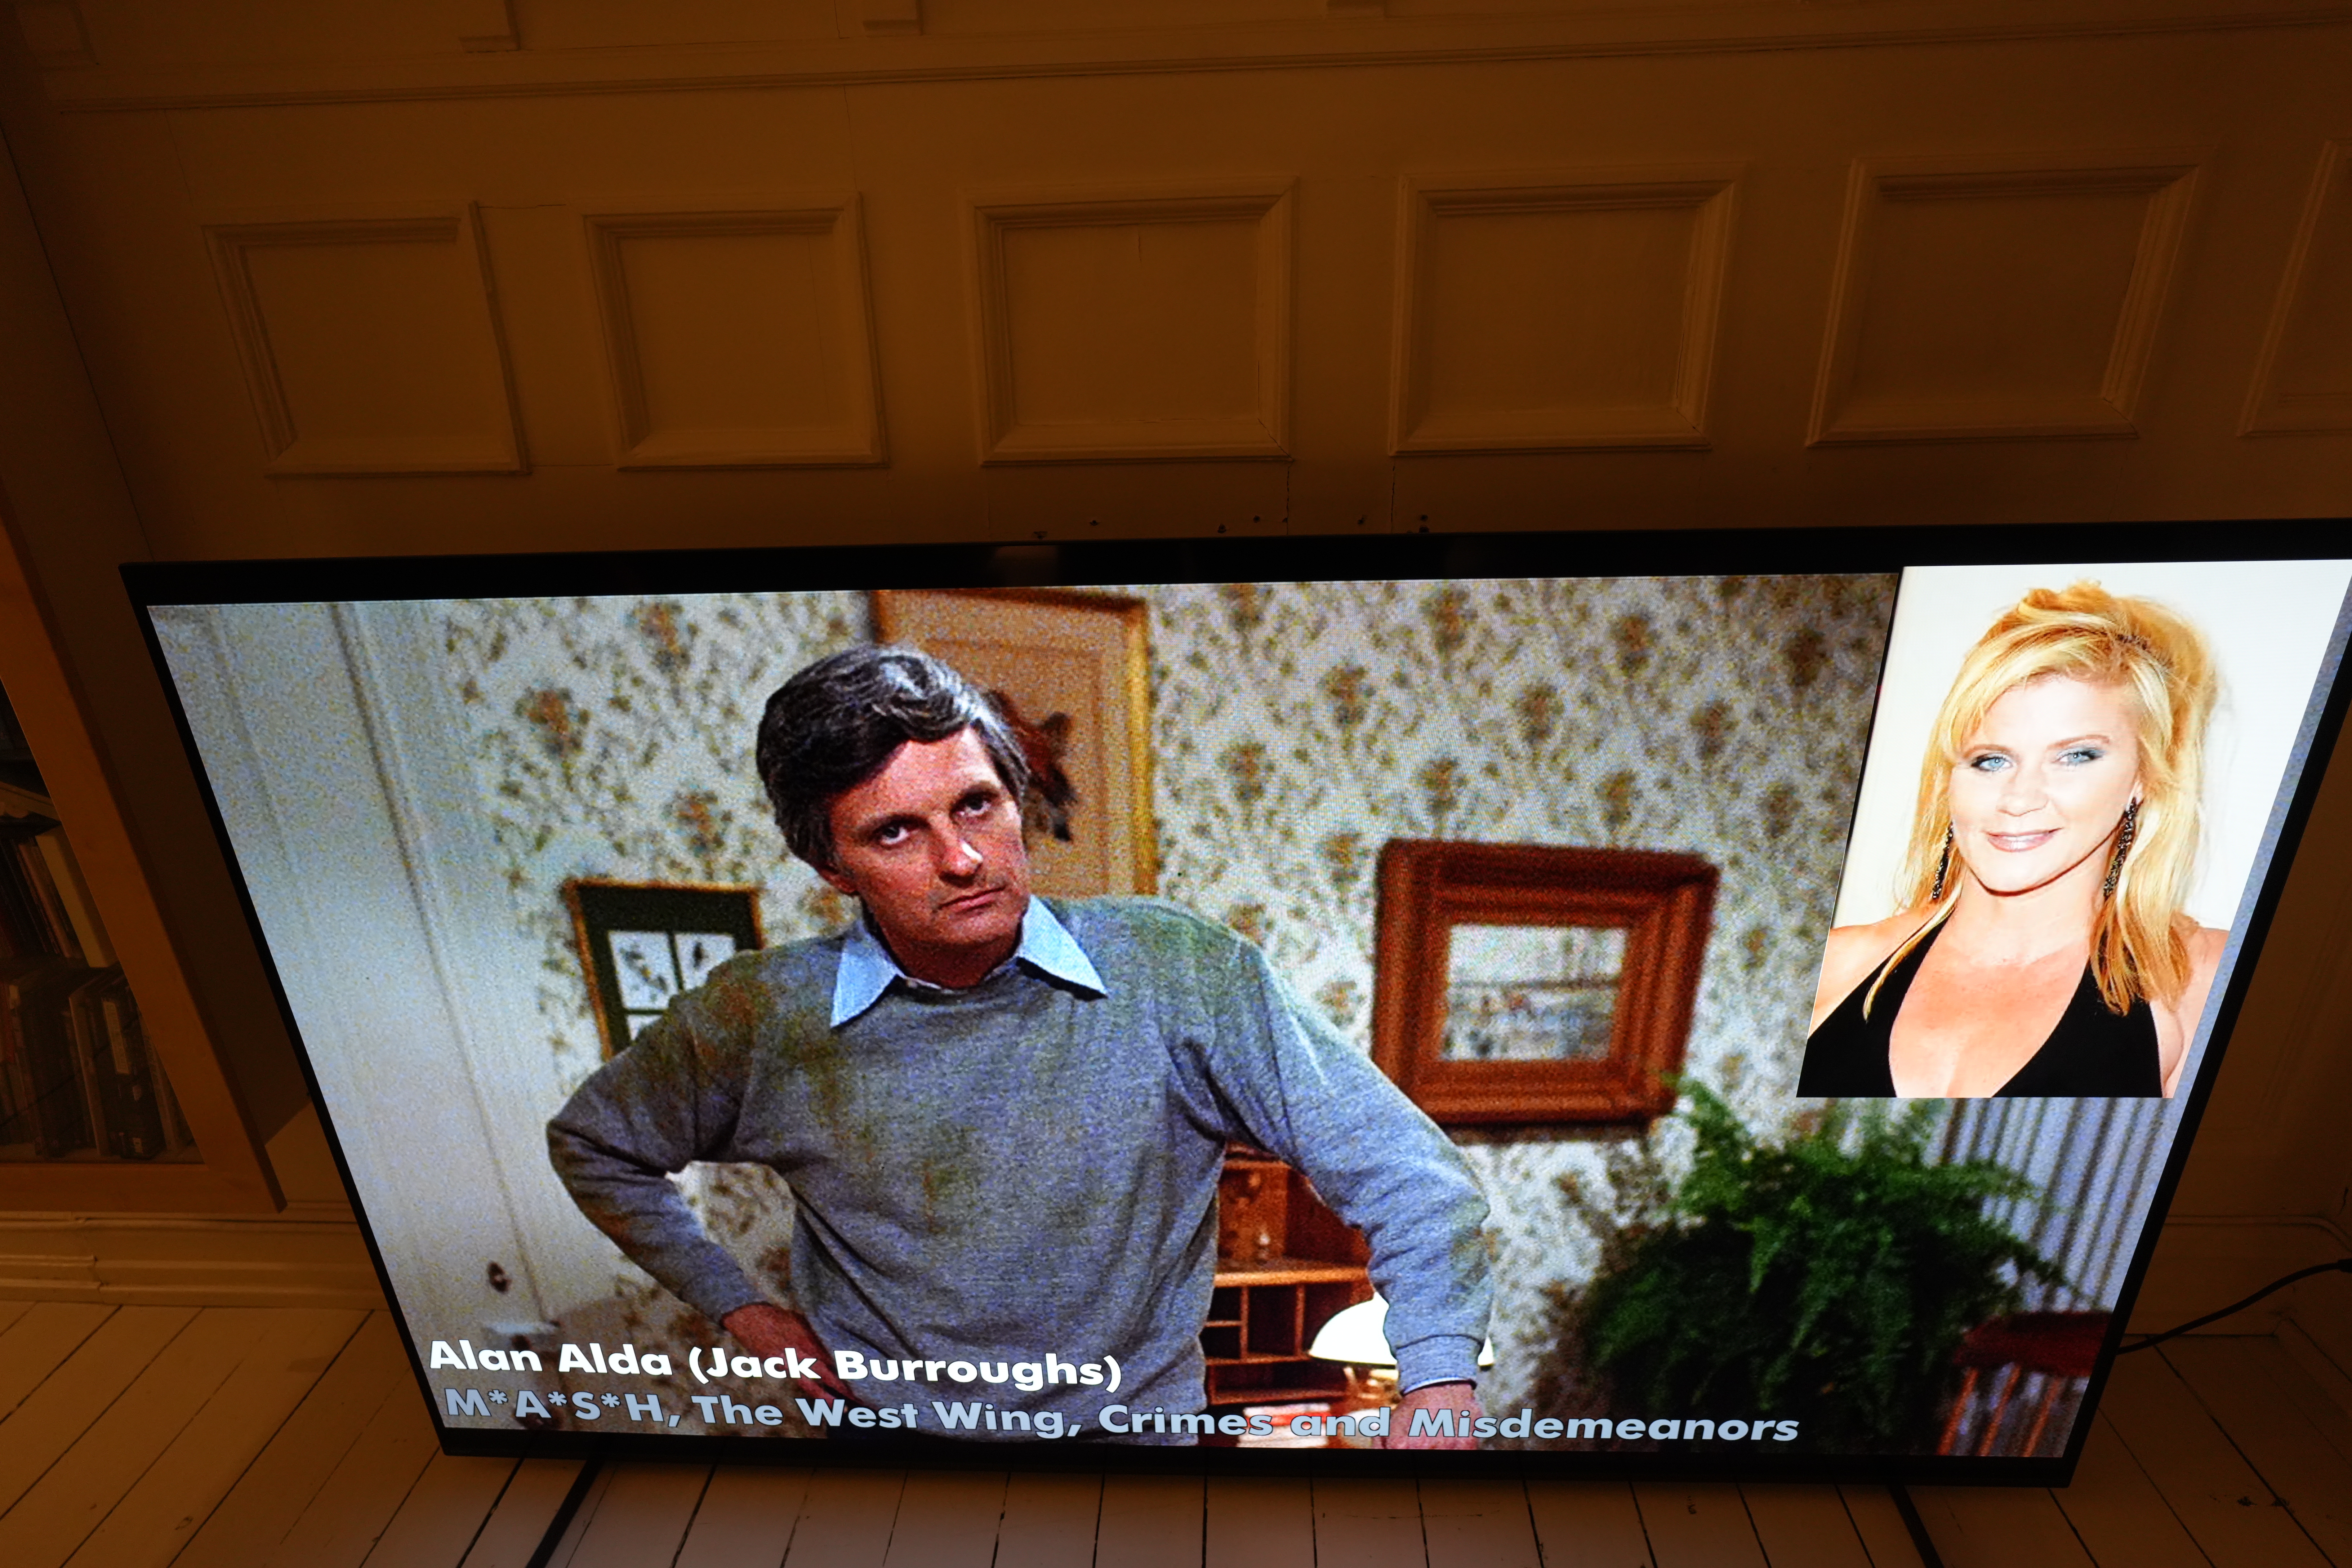
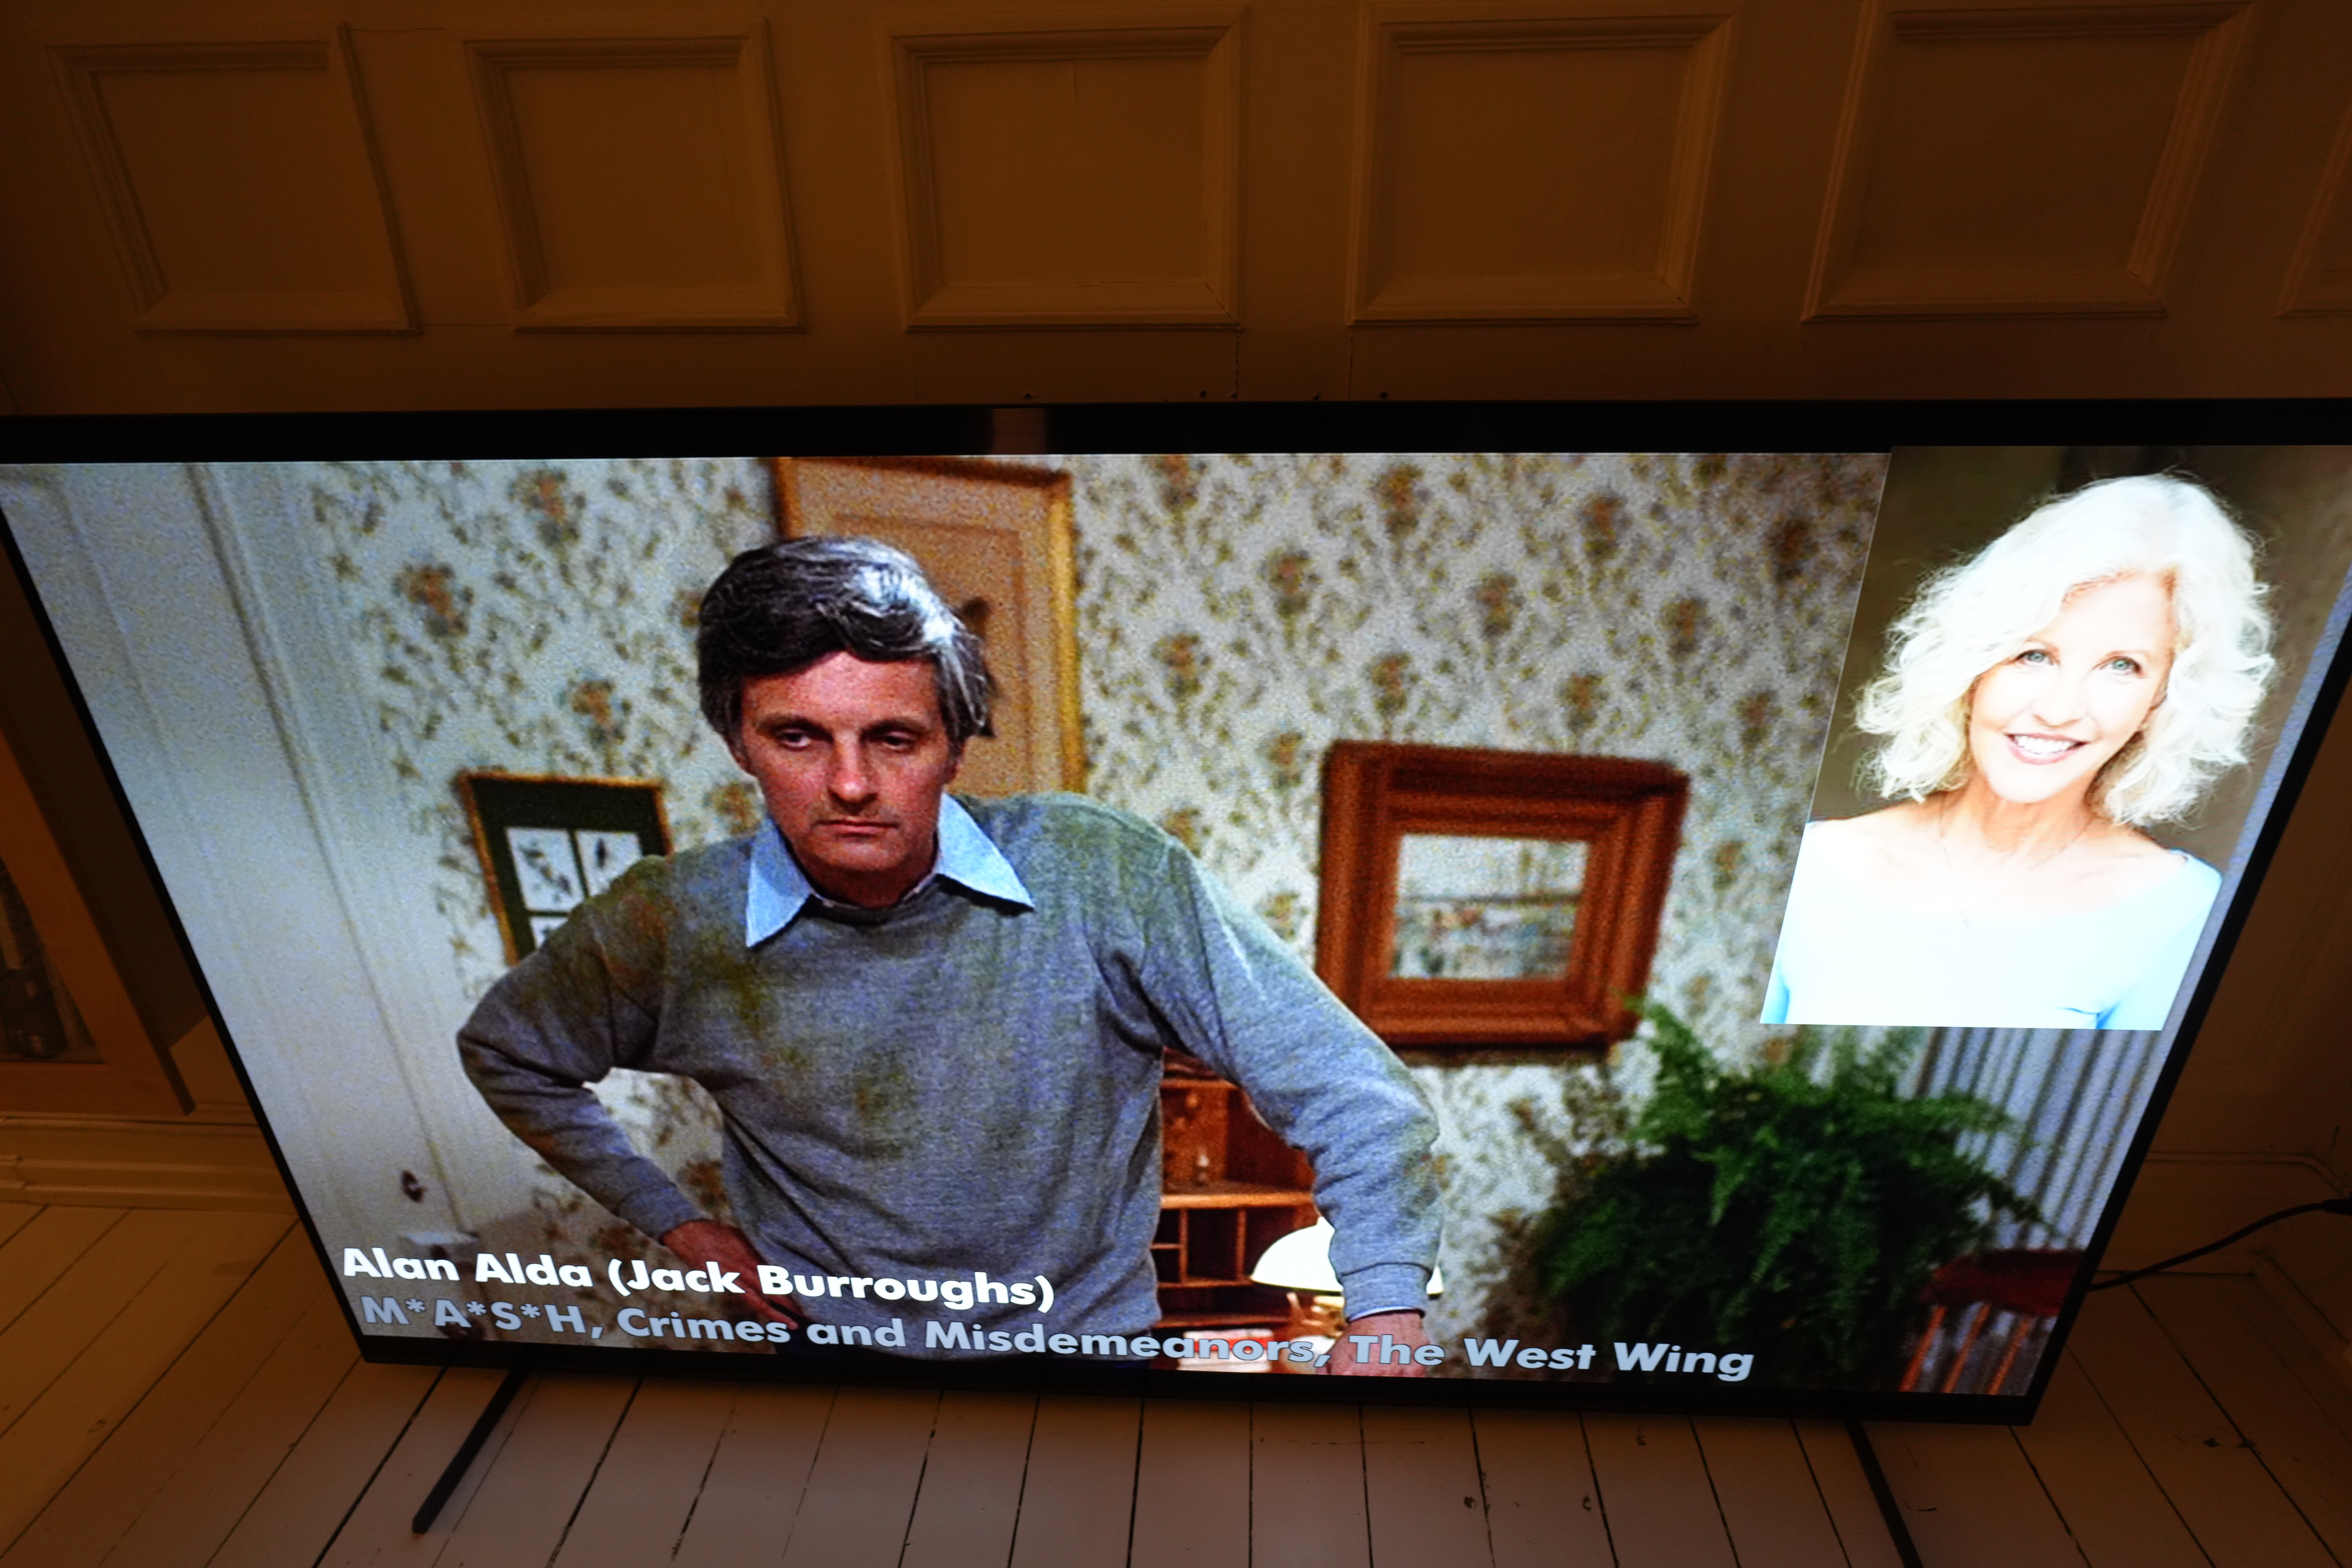
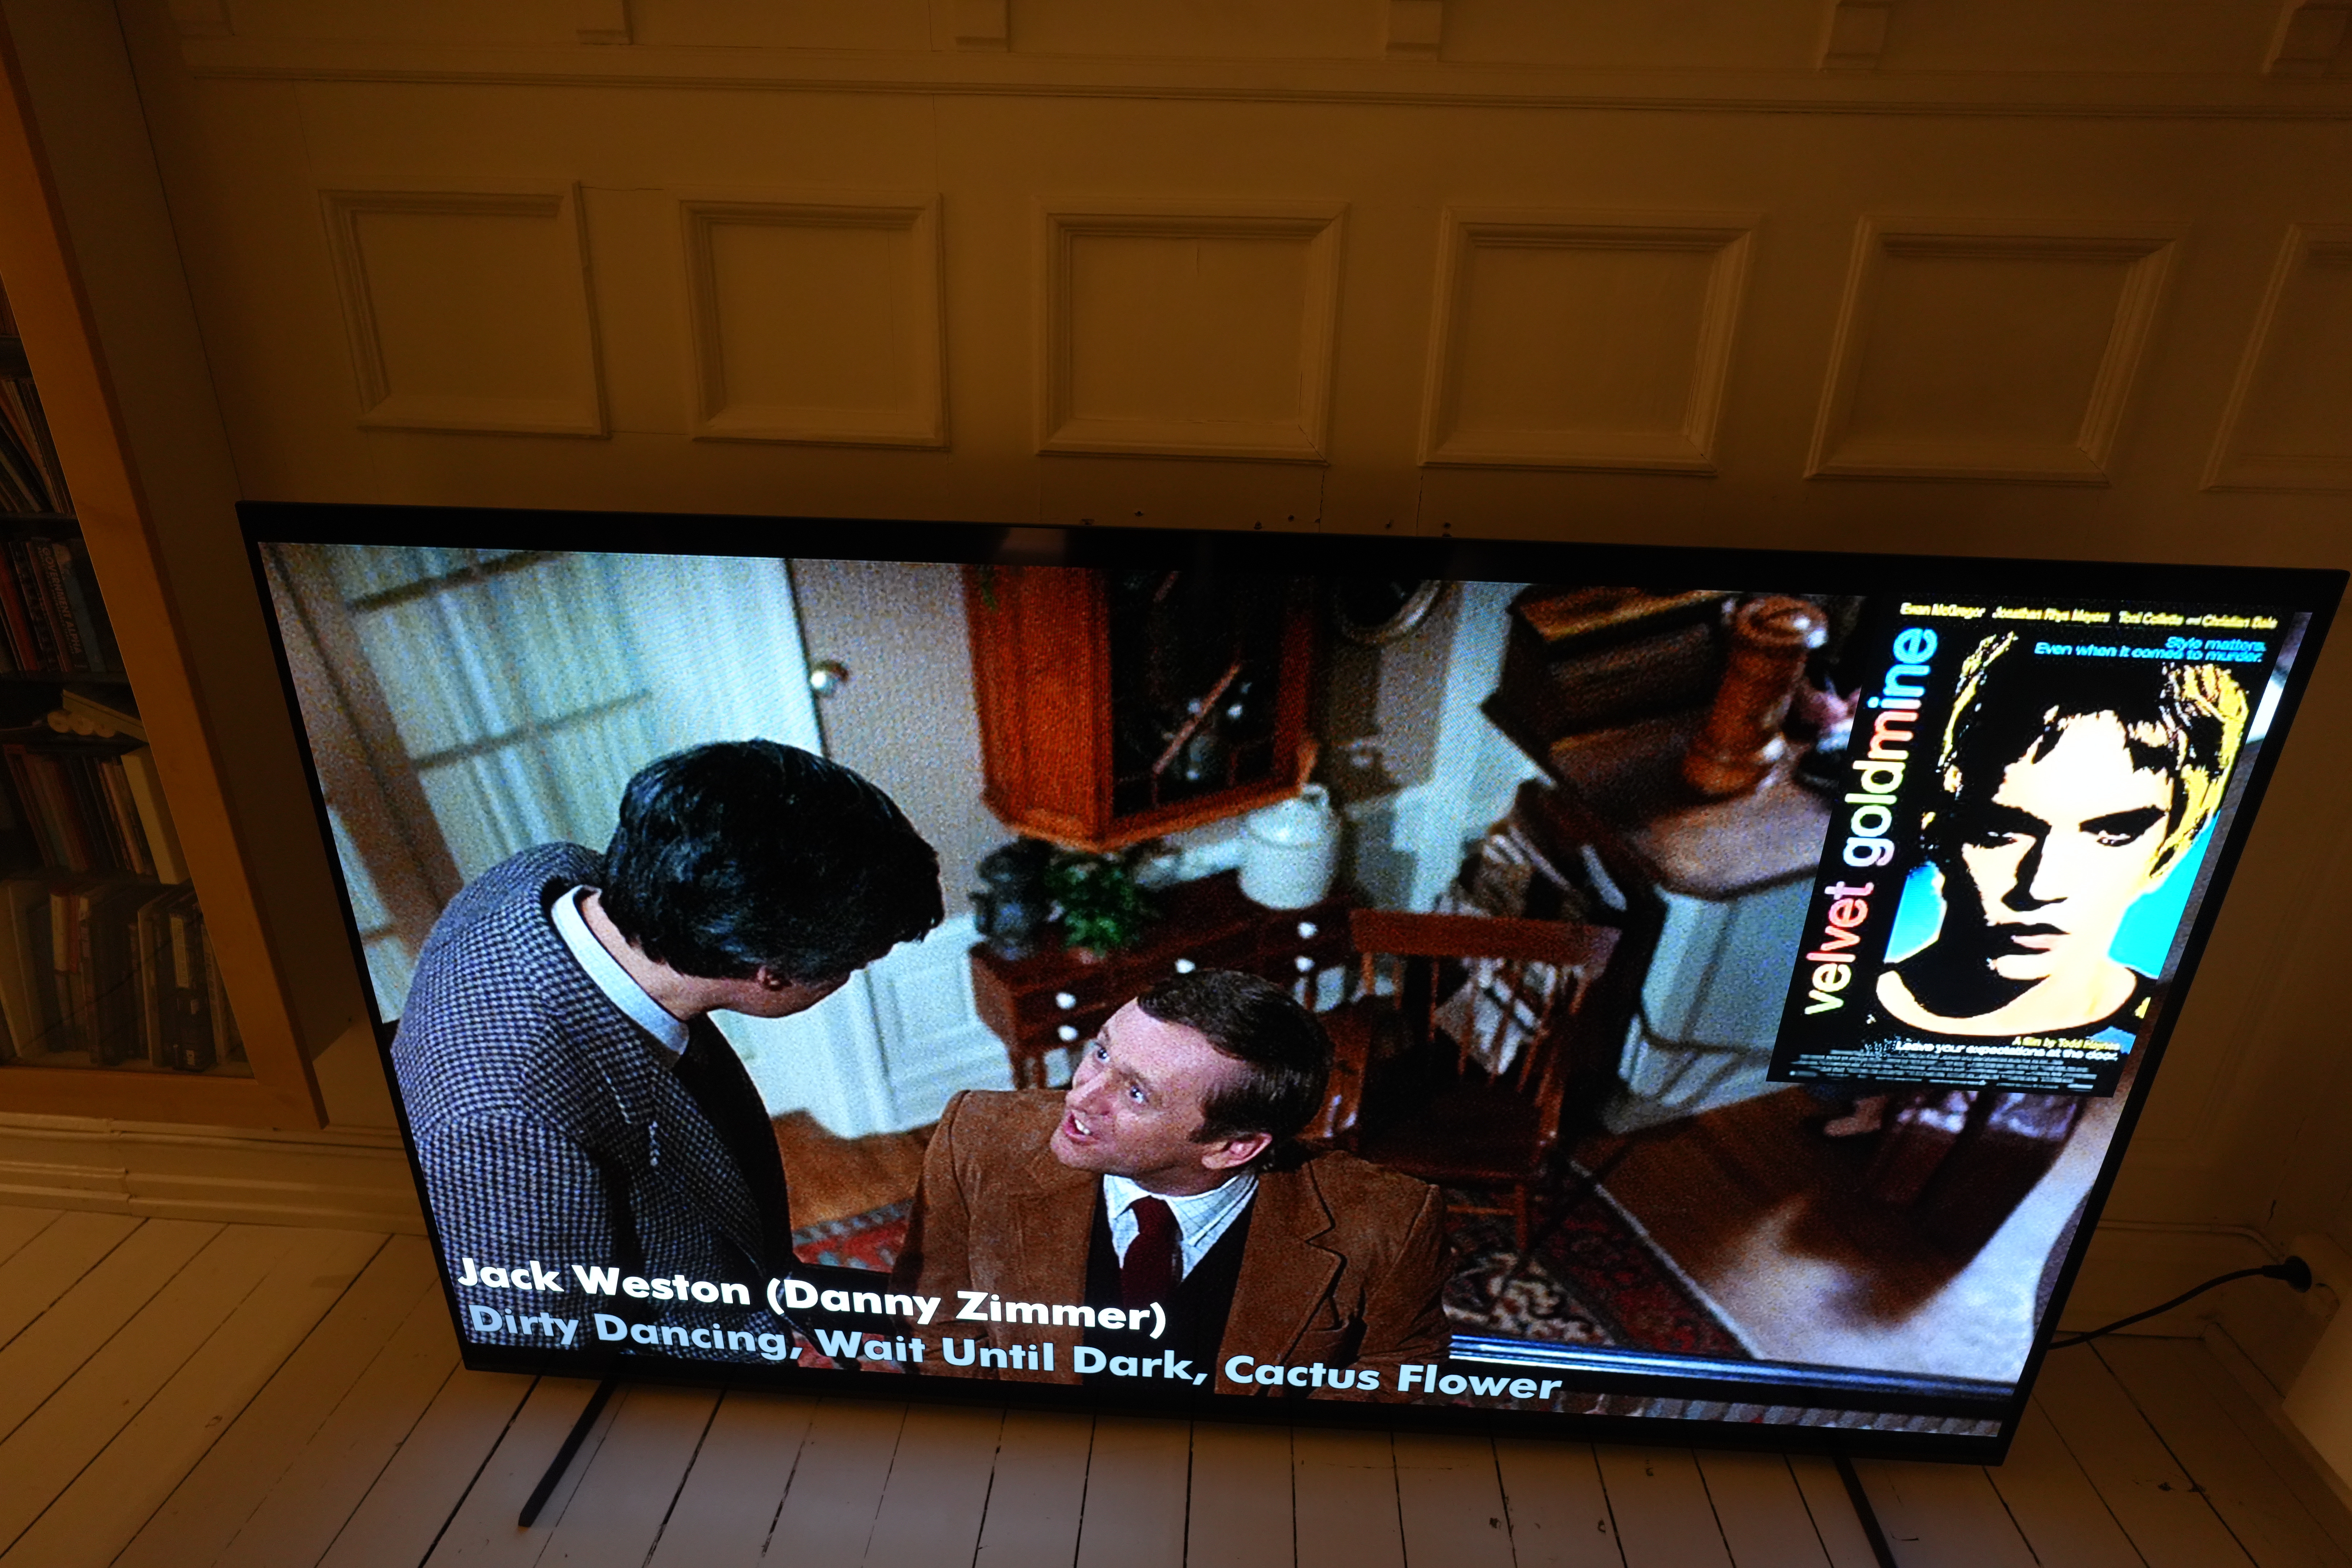
I was watching The Four Seasons yesterday, and there were a couple of actors I wondered who were. I mean, not Alan Alda, but a couple of the others… so I hit the “Emacs, tell me who what is” button on my remote, and nothing much happened.
So things had bitrotted once again, which isn’t weird — the code is a bit of a Rube Goldberg thing which you can peruse here, but I wouldn’t really recommend it.
But I’ve spent the entire day fixing it, so I deserve to complain aimlessly in a blog post, right?
OK?
OK: The main problem is that AI web scrapers are hitting imdb so hard that Amazon has tightened its shield even more. The main motor behind the Actor Guessing Machine is an LLM, and that API still works (if you can call “being wrong half of the time” to “work”), but I’m trying to use imdb to show the actor’s face (see inset on the top right above) so that I can check whether what the LLM said is likely.
My first idea was to just avoid using imdb altogether. Instead I asked the LLM to include an image of the actor, too. Shouldn’t be too hard, right? Well, Gemini will do this if you ask — but it takes 45 seconds or so. Yes! 45 seconds! So that’s not very UX-ey.
I also tried using Claude, but it sternly told me that I was very naughty for even trying to make it output images of real people, and that I should be ashamed of myself. Oh, and then also (since I had asked it to return JSON and nothing else), it also included this in the middle of the rant:
```json [] ```

So… Back to imdb: I’m already using a headless Chrome to fetch imdb data, but now it requires popping up Chrome (once in a while) to click on some hats or something:
How elegant! I’m so proud of the UX!
So what I’m doing is running a “server” (Emacs based, of course) on the laptop, and when the TV computer needs to get some imdb data, it (Emacs) asks the laptop (Emacs), and if it then turns out that it needs to pop up a window, it can do so (Chrome).
*sigh*
So… it’s all a bit stupid. And is it worth it? Eh. It’s probably gonna break in a few weeks anyway. I guess I’m more offended that I have to do this much work more than anything else. The challenge? Eh. Dunno.
But when it doesn’t need a popup, it’s kinda OK:
See? So… eh.
Oh, and while I’m moaning and carrying on:
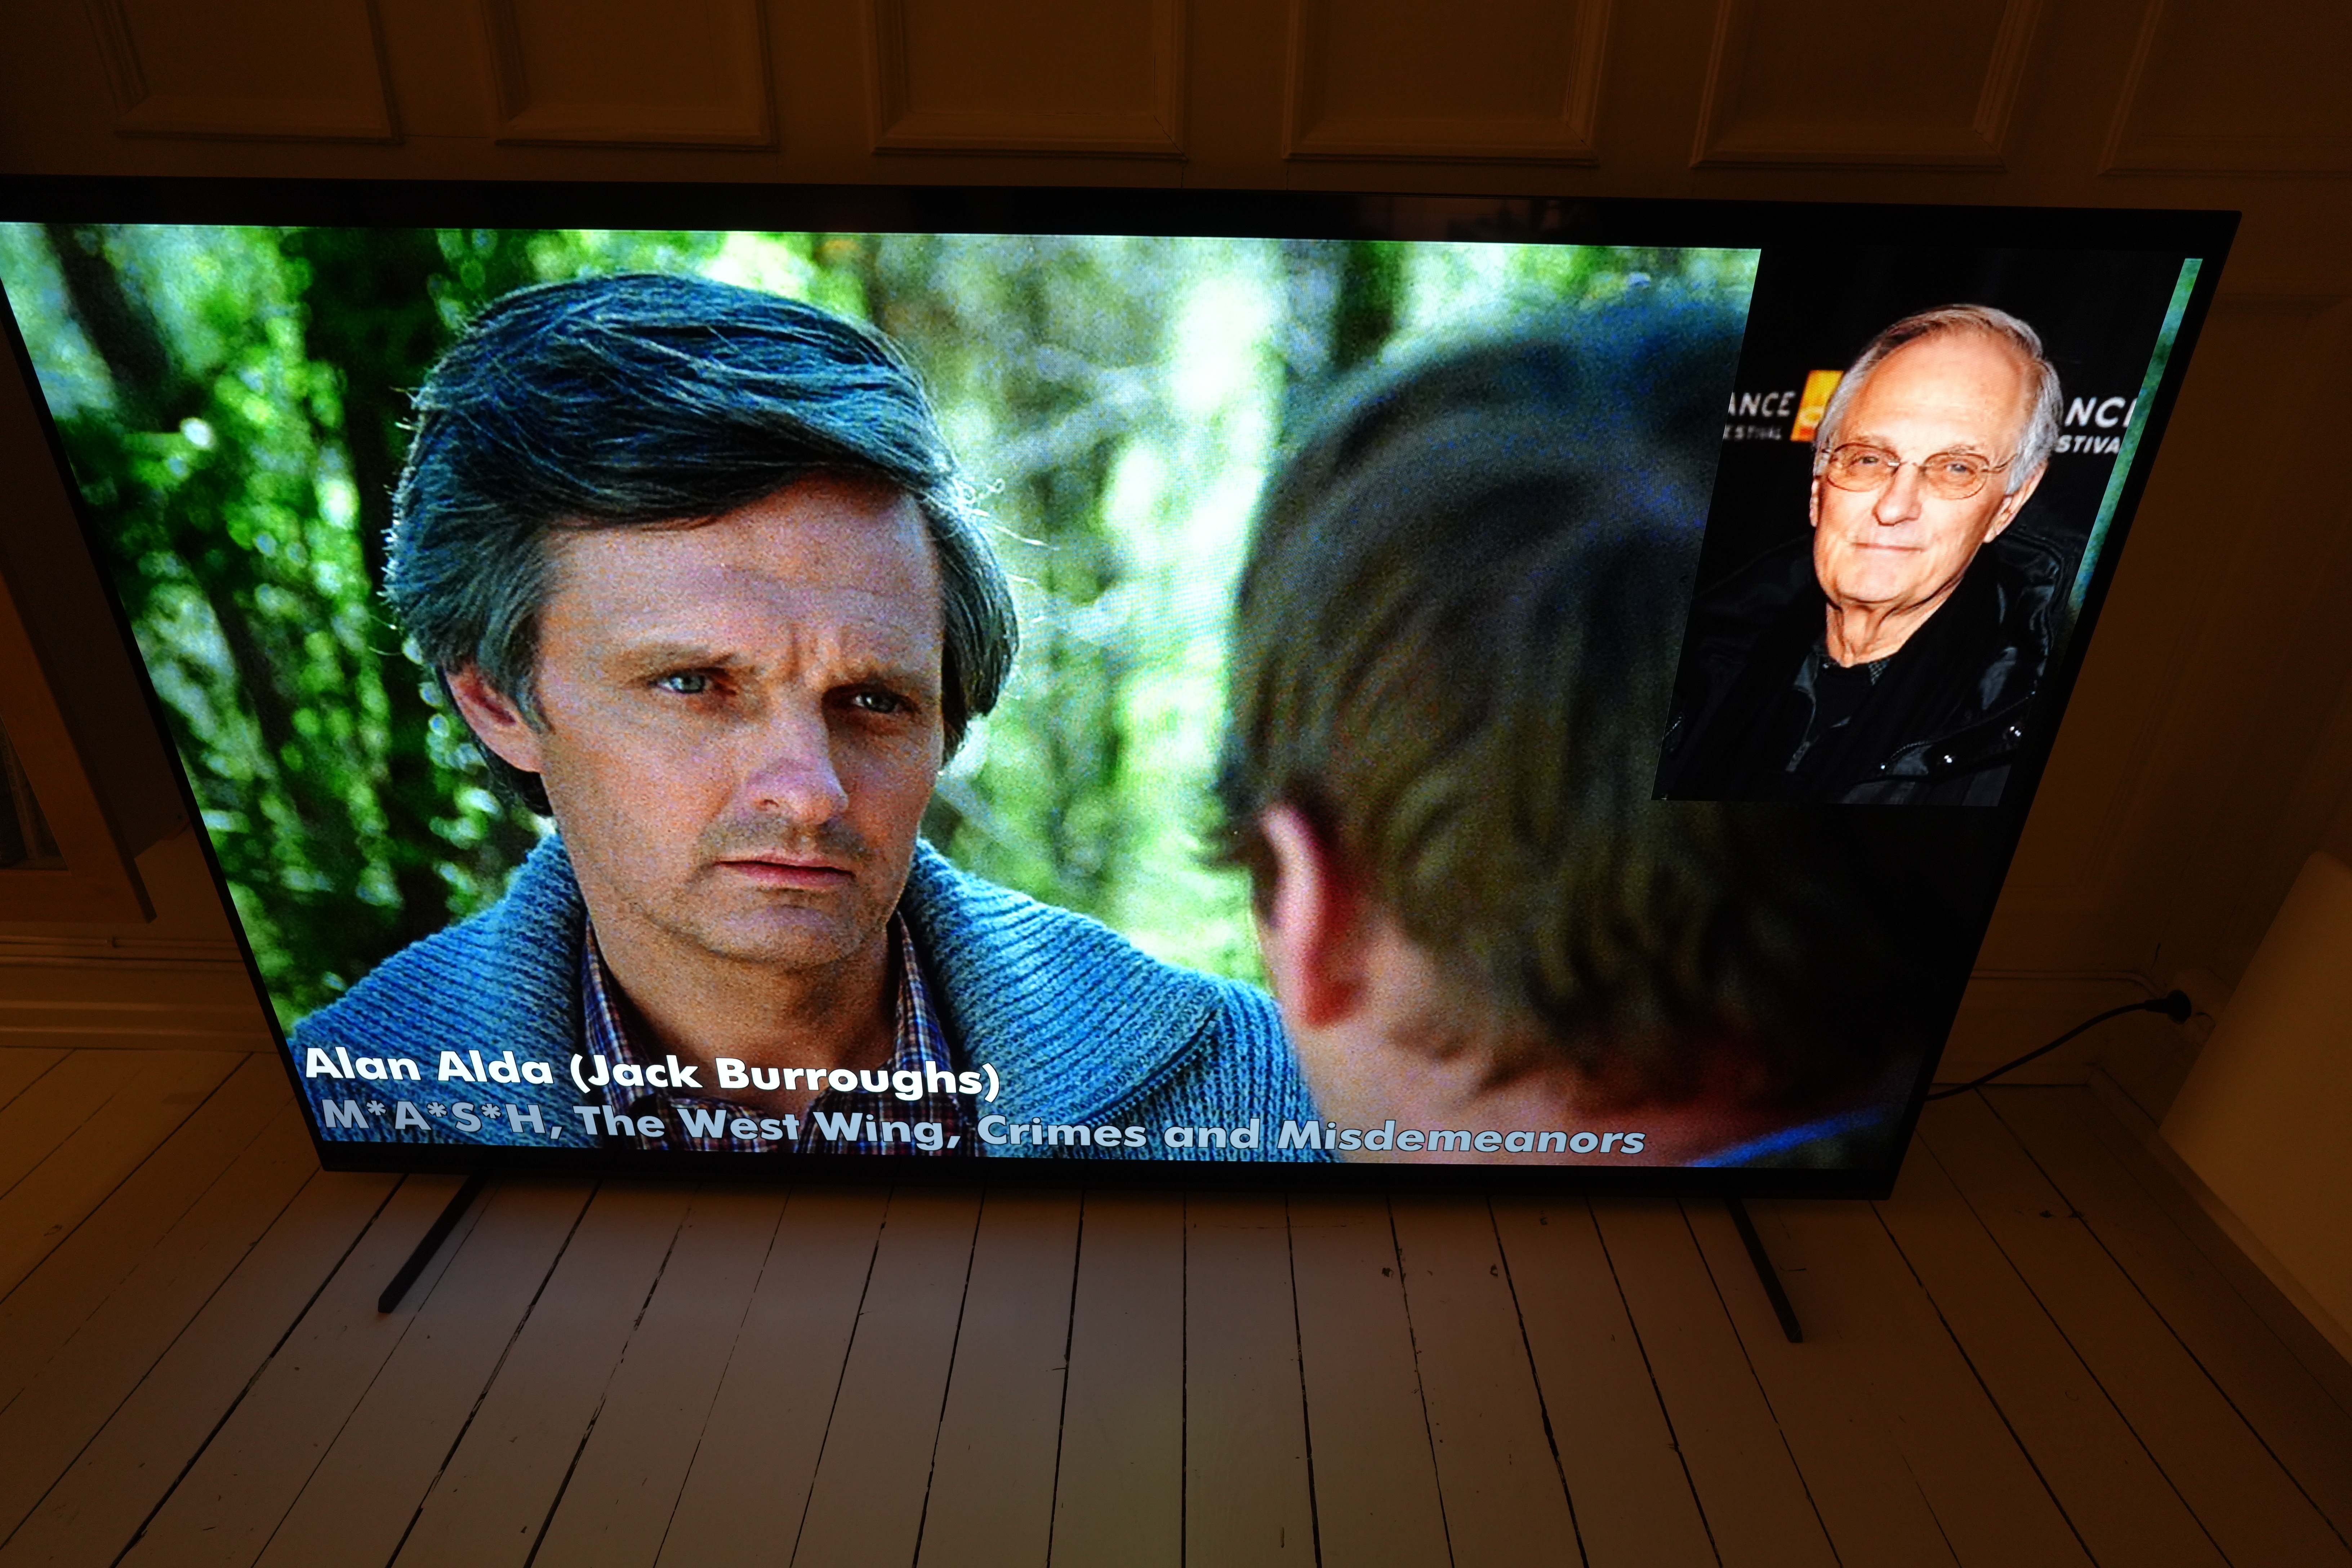
LLMs are still guessomats. I ask the LLM (Gemini, in this case) to include the imdb ID of the actor in the response, and it will totally just make up an ID. So that’s not Carol Burnett in the inset image there.
And is that really Alan Alda?
That’s definitely not Alan Alda.
I guess that could be Alan Alda.
Anyway, since Gemini just makes up imdb IDs, I’m instead resorting to using the imdb data dump — when I get “Alan Alda” back from the LLM, I then look up the name in the imdb data dump database (that I have locally) and use that instead. If the name is spelt differently there than what Gemini returned? Well, them’s the breaks.
So this is totally a toy, but it’s kinda useful anyway.
-1:-- Who’s That Actor? Revisited (Post Lars Ingebrigtsen)--L0--C0--2026-11-07T20:30:49.000Z
My ex-colleague and old friend Watts Martin has an interesting post about BYOK. BYOK is a “writer deck”, a device exclusively for writing that has no distracting apps or even a connection to the Internet. The idea is that writers can’t get distracted when they reach a temporary block by escaping to social media or something similar; they have to push through the block and get on with their writing.
According to Martin, BYOK is better than most devices in its class but there are still problems. He doesn’t like the available fonts and the screen—as you can see from the picture in his post—is pretty small, about 6 lines depending on the font. That seems to me to amount to a rather uncomfortable working environment. Fortunately, I don’t usually find myself distracted when I’m writing.
Then there’s the matter of research. Very often you need to look something up when you’re writing and you can’t do that with something like BYOK so you need to switch devices, pulling you even further out of the flow. And as Martin observes, it’s not easy to integrate your notes either.
The deal buster for me, though, is the builtin editor. It’s not Emacs based and doesn’t even support Emacs keybindings for navigation. As I’ve repeatedly said—as recently as yesterday—I simply can’t comfortably write outside of Emacs anymore. Martin is a relative newcomer to Emacs but he’s already feeling the discomfort. Once the Emacs way sets in, he’ll be just like me and won’t consider doing serious writing outside of Emacs.
Even if I were subject to being distracted by the greater Internet, I would simply turn off my WiFi to produce what is effectively an Emacs based writer deck. One thing for sure, I’m not giving up Emacs and suffering a second rate writing environment.
-1:-- BYOK (Post Irreal)--L0--C0--2026-11-07T16:02:24.000Z
-1:-- [FR] LaTeX preview support Emacs without SVG support (Post Org Mode requests)--L0--C0--2026-11-06T19:20:22.000Z
Over at And now it’s all this, Dr Drang has a post on using TextEdit versus using Pages. He’s a Mac user, obviously, but that doesn’t matter so much. The real argument is over whether one should use a word processor or some sort of text based editor.
There can be no doubt on where I stand on the issue. The only time I can remember using a “word processor” of any type in the last 3 decades was when I had to collaborate on another author’s file as a technical editor1. As I’ve said before, whenever I write in anything other than Emacs, I feel like I’m in Bizarro World where nothing works as it should. That includes even things like iMessage which is why I tend to use emacs-everywhere for it and most other things.
Dr Drang is nominally the same. He says he almost never uses a Word Processor but sometimes for a one-off he thinks it makes sense to use a word processor rather than one of his LaTeX or Markdown templates. That seems backwards to me. Sure, maybe you don’t want to use a template for a technical report to write a quick note to your baby sitter but Pages or any other word processor is not the simple alternative. I’d simply use Org and export it to whatever format seems appropriate. Even if Dr Drang is not an Emacs user, he is a Markdown user so surely the easy thing for him to do is to dash off his quick note in Markdown.
Really, unless you have collaboration issues, there’s no reason to subject yourself to the horrors of a word processor.
That post was so long ago that I was still using Groff instead of Org to typeset documents. I’ve done technical editing since then that also required a Word clone and the experience was no better.
-1:-- Why Use A Word Processor When You Have Org? (Post Irreal)--L0--C0--2026-11-06T15:59:52.000Z
We have a recording session for the EmacsConf 2026 panel on community tomorrow. I want to get my thoughts together so that I can answer concisely, saving the details for this post so that people can dig into it before or after the conversation. So here are some rough notes:
If you want to reflect on the questions, please feel free to do so and to share your responses with me or on your blog. (You don't have to be one of the panelists. =) )
You can e-mail me at sacha@sachachua.com.
-1:-- EmacsConf: Thinking about the community panel (Post Sacha Chua)--L0--C0--2026-11-06T15:50:05.000Z
Time for another bi-monthly update on the work that Clojurists Together are funding this year - my maintenance of nREPL, CIDER and friends. You can find the previous one here.
For a change, most of my focus in September and October was on nREPL itself, not on CIDER. The big themes were the nREPL protocol spec and how well the servers and clients out there actually stick to it. For years building an nREPL server or client that plays well with the rest of the ecosystem came down to trial and error, and this time I finally did something about it. It paid off much sooner than I expected.
The big highlights from my perspective:
ns form, backed by new cider-nrepl and Orchard releasesBelow you’ll find the details, project by project.
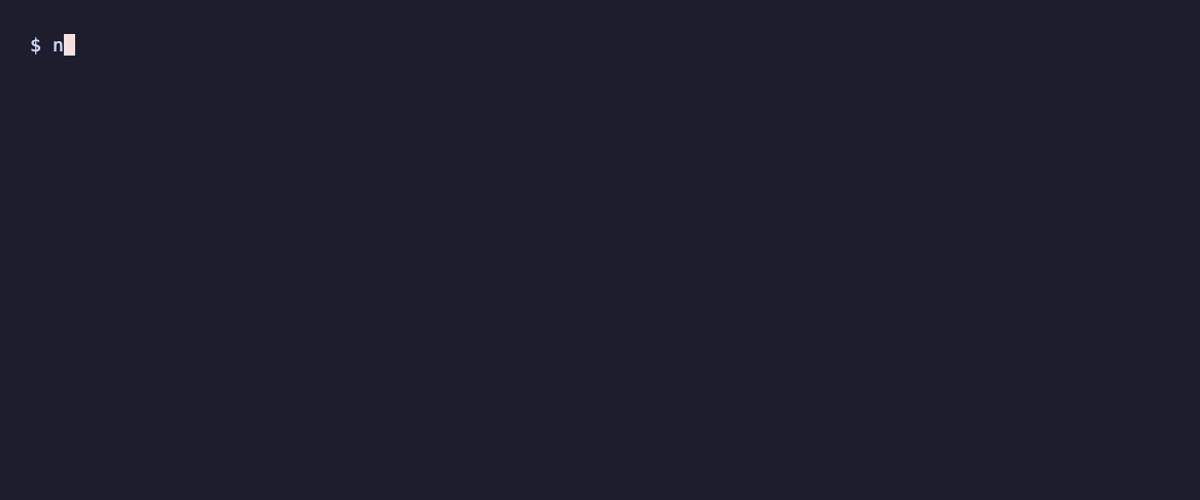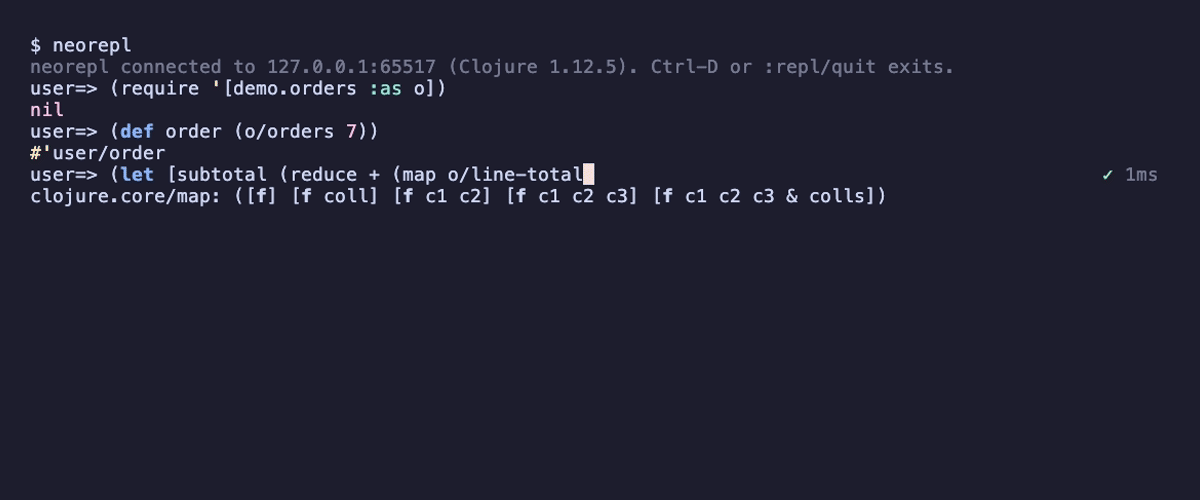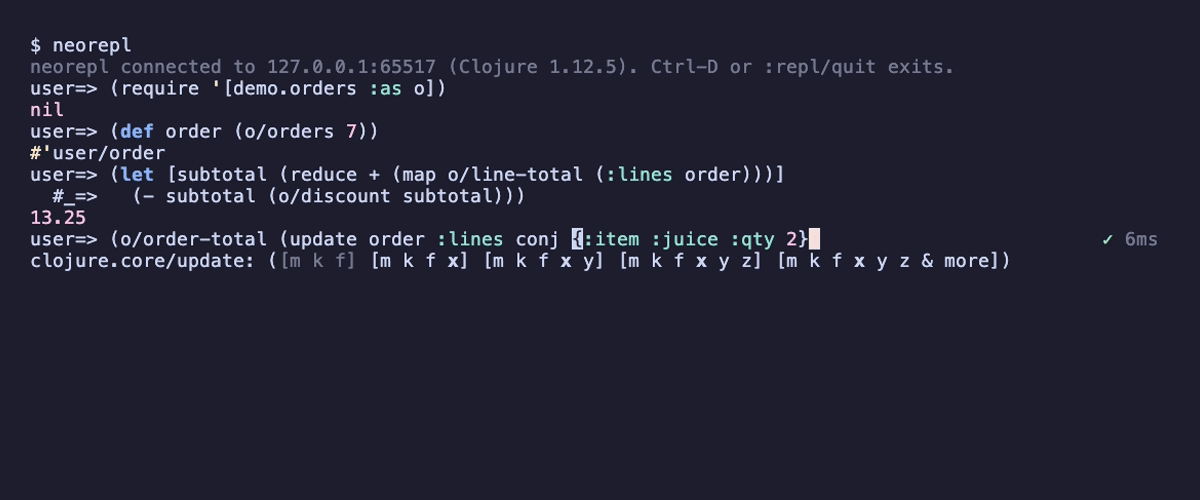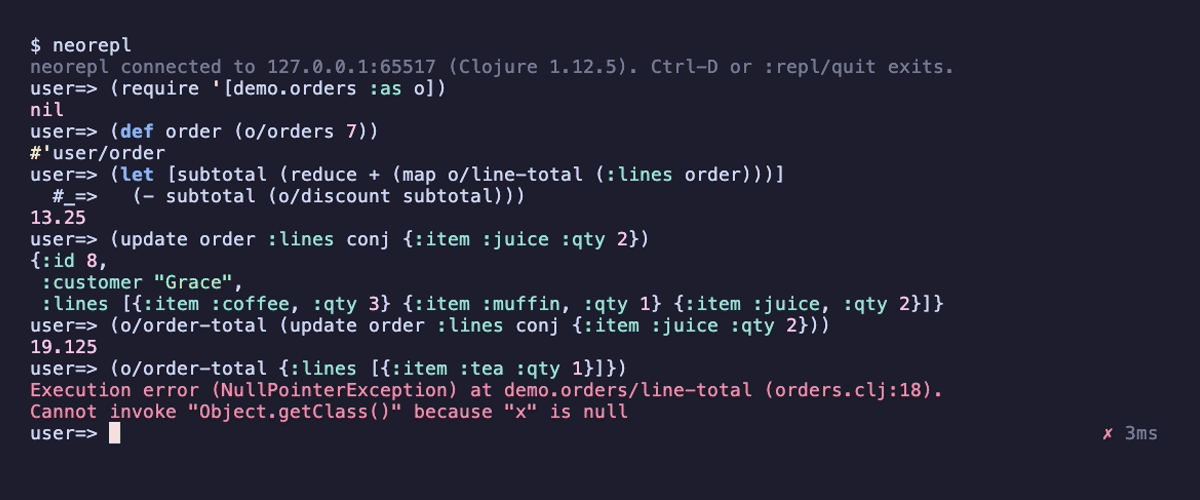
proof is the big new project this time around, and the one I’m most excited about. I’ve been talking about some automated way to check nREPL compatibility for ages (it made my list of things people hate about nREPL back in 2023), so it feels really great to finally see it become a reality. Good things take a while to happen, they said… Does your server work with CIDER? Until now the only way to find out was to implement the protocol, connect CIDER (or Calva, or whatever your users run) and see what breaks. Now you can point proof at your server and it’ll tell you. It’s a single binary that runs about 80 checks against a server. A check fails only when a real client would break (with a link to the client code that depends on the behavior), and everything else is just a warning. proof also comes with client profiles that send exactly what CIDER, Calva, Conjure, vim-fireplace, REPLy and neorepl send, profiles for the servers I know of, and a GitHub Action for running it in a server’s CI.
Once the server side was in place, I started on the clients as well. proof proxy sits between a client and a server and checks what the client sends,
and proof serve is a small server for the test suites of clients, which can mimic the quirks of nREPL, Babashka, jank and others (proof serve -like jank).
I wrote about proof in a lot more detail in proof: How Strong Is Your nREPL?.
proof goes hand in hand with the nREPL spec, the draft Phil Hagelberg wrote earlier this year. When the spec and the existing clients disagree, proof goes with the clients (a spec that breaks CIDER isn’t much use to anyone), and every such conflict, along with the gaps proof ran into, ends up on a list of spec changes. The first few of them are already PRs against the spec: how replies relate to their requests, the status values, how interrupts are answered and the fields of lookup replies.
What I like the most about proof is how quickly it started paying off:
done of an eval interrupted from another connection to the wrong connection (fixed on master), drops the evals waiting behind an interrupted one (#503) and can’t interrupt an eval that hasn’t started yet (#504). Not great!I was also super happy to see other people using proof already. Tom Waddington has been running it against his nREPL implementations
for Janet and Steel Scheme since early October (nrepl-janet even tests its client with proof serve),
Jeaye Wilkerson suggested using it for jank’s nREPL server, and Kyle Cesare is already fixing what it found there.
That’s exactly what I was hoping for!
neorepl is the other brand new project, and it grew up together with proof. It’s a terminal REPL for Clojure (and anything else that runs an nREPL server), and the best way I can describe it is “CIDER in a terminal”: it uses cider-nrepl when it’s around, the same way CIDER does, and falls back to nREPL’s built-in ops when it isn’t. Every lookup the REPL can do is also a command with structured output, and there’s an MCP server and a skill for coding agents, so it’s “CIDER for agents” as well. Five releases in three weeks:
neorepl mcp, a skill that teaches agents to check, load, test and debug Clojure code with the CLI, and neorepl check --fix, which fixes mismatched delimiters the way parinfer does.proof checks every server with the exact requests neorepl sends, and neorepl went through proof proxy and every scenario of proof serve before 0.1 was out.
Its commands are separate processes sharing a session, so neorepl hits nREPL’s interrupt bugs harder than most clients,
and making it work as well on Babashka’s server as with cider-nrepl is where most of the Babashka reports came from.
Even JLine got a few bug reports along the way.
By the time I got around to writing this update, neorepl 0.5 was out as well, with a much smarter line editor, a namespace browser, automatic reloading and a CLI that editors can use without a plugin. I wrote about it in neorepl 0.5: CIDER in a Terminal.
nREPL 1.8.0 came out on October 2 with the URL-based connections and the TLS improvements I mentioned last time,
plus a few session fixes. Sessions survive evaluated code closing *in* or *out*, a race that could split responses between concurrent reads in nrepl.core/client is gone,
and Sashko made persistent sessions re-create their thread when a faulty exec thunk kills it. He also moved the Unix sockets to the SocketChannel API.
Master moved on quickly after the release, much of it because of proof and neorepl:
done of an eval interrupted from another connection goes to the eval’s own connection, where the client that sent the eval never got itTCP_NODELAY on accepted connections, so on Linux an eval’s done no longer waits up to 40ms behind its value:out-limit with separate :out-quota and :err-quota limits, made the bencode transport turn empty lists into nil for ?-ending keys and made building the middleware stack fasterThe interrupt bugs that are still open are next on my list.
load-file failing with “No such namespace” when the file requires a foreign lib (e.g. a cljsjs package).:cljs/quit on nREPL 1.3+, where the session stayed in ClojureScript mode, and made evaluation use the same dynamic bindings as cljs.repl. That means the cljs-repl options (e.g. :warnings) and the bindings tools like figwheel-main set up around it finally take effect, which closes an issue from 2018. It also picked up :as-alias keywords and the :cljs branch of data_readers.cljc.nrepl.org got a facelift at the end of October. The manual moved to docs.nrepl.org, and nrepl.org itself is now a landing page that explains what nREPL is and how its protocol works, with real exchanges between a client and a server next to every feature. It even has a “Try it” section with an nREPL server running right in your browser, which turned out to be a story of its own. That playground is how nrepl-sci, a small nREPL server for SCI that runs entirely in a web page, came to be, and it even led me to take a closer look at clojure-mode for CodeMirror, which powers the playground’s editor.
CIDER got a landing page of its own at cider.mx, made to look like an Emacs frame (mode line, M-x and all), with mini screencasts of CIDER in action.
I had a lot of fun working on both sites!
My toy nREPL implementations were the first things I ran proof against, and all of them got a round of fixes in early October:
close with session-closed, echo the op in unknown-op replies and return a value for every Erlang form in an evalerr, handles unknown sessions and stdin EOF, and checks describe before using completions, lookup and interruptneat’s own integration suite now tests just the client and leaves the servers to proof. None of the three has had a release yet, though.
No CIDER release this time (2.1 is still brewing), but master kept moving:
cider-test-stream-results, on by default): the echo area keeps a running count, and failing tests land in the report as soon as they finish. This closes an issue from 2014! cider-test-fail-fast is now off by default to go with it.ns form: cider-ns-add-require, cider-ns-add-import, cider-ns-add-missing (adds what the symbol at point needs), magic requires (typing alias/ adds the require the alias needs) and cider-ns-clean. These are some of clj-refactor’s most popular features, and they’re backed by new cider-nrepl ops that read your code instead of loading it.cider-connected-hook and friends never ran. proof found this one.nil value are left out of nREPL requests instead of being sent as empty lists, which closes an issue from 2020.cider-nrepl releases:
orchard.test and streams their progress to the client, which is what CIDER’s test streaming builds on.cider/resolve-missing, cider/resolve-alias and cider/clean-ns ops behind CIDER’s ns commands (after three alphas), made the test ops always answer and send what tests print with their own responses on nREPL 1.3+, and fixed the inspector and ClojureScript tests on shadow-cljs.Orchard releases:
orchard.test, the clojure.test runner that used to live in cider-nrepl and can now report progress as it goes, plus Sashko’s string analytics in the inspector and his fix for the stack overflows when printing recursive collections.orchard.ns-form, which takes apart an ns form and tells what it requires, refers and imports that the code doesn’t use, all without loading anything, and fixed some Java doc rendering problems.str) from overflowing the stack.Sashko also added JDK 27 to the CI of nREPL, cider-nrepl and Orchard. Thanks, Sashko!
refactor-nrepl 3.15.0 documented the limitations of its AST-based analysis
and deprecated the ops cider-nrepl has taken over. Back in the spring I said I’d like to move the most useful refactor-nrepl features
to CIDER and cider-nrepl eventually, and the ns editing commands above are the first step in that direction.
No release, but quite a few fixes on main. I fixed clojure-ts-mode on Emacs 31 (e.g. the ClojureScript mode asking for the jsdoc grammar, M-q indenting only the innermost form)
and a pile of refactoring commands that went wrong around metadata, #_ forms and reader conditionals.
Jason Jackson sent a round of indentation and alignment fixes (threading macros, reader prefixes, metadata and comments before arguments),
and Kyle Cesare kept up with jank’s syntax. Thanks, Jason and Kyle!
MrAnderson 0.7.2 stopped bundling pomegranate’s Maven classes in its jar, where they clashed with any other resolver on the classpath and broke cider-nrepl’s build once tools.build pulled in a newer tools.deps. The artifact went from 8 MB to about 200 KB in the process.
There was also a lot of release and CI maintenance across nREPL, cider-nrepl, Orchard, Piggieback and friends (e.g. release notes taken from the changelogs, the docs of a release published by its release workflow), and I revived the CI of parseclj and parseedn.
Big thanks to Clojurists Together, Nubank and the other organizations and people supporting my Clojure OSS work! None of this would have happened without you. You rock!
As for what’s next - last time I said CIDER 2.1 was the obvious next milestone. It still is, but it got delayed, as most of my time went into nREPL instead. I told you I’m bad at predictions! nREPL 1.8 shipped as planned, and mezcaml and the BEAM servers got a lot more reliable thanks to proof, even if neither got a release. While we’ve made solid progress on CIDER and friends as well, my main focus until the end of the year will likely be the broader nREPL ecosystem: fixing the interrupt bugs proof found in nREPL, turning the list of spec changes into PRs against the spec, and getting more servers and clients to run proof.
Keep hacking!
-1:-- Clojurists Together Update: September and October 2026 (Post Meta Redux)--L0--C0--2026-11-06T09:00:00.000Z
For as long as I’ve been involved with nREPL, the question I’ve heard most often from people building servers and clients has been some variation of “Will this work with CIDER?”. And for just as long the honest answer was “Try it and see”. Today I have a better answer for you - proof, a compatibility suite for nREPL servers (and clients). I’ve been working on it since the end of September and proof 0.2 came out a couple of days ago, so I guess it’s high time I told you a bit about it.
The nREPL protocol is tiny. A handful of ops, requests and responses that are
simple maps, bencode on the wire. You can write a basic nREPL server in a
couple of hours, and lots of people have done exactly that. Making it play nice with
CIDER, Calva, Conjure and the rest of the clients out there is a very
different matter, though. What clients actually expect from a server is
spread across the reference implementation, a draft spec, many years of
client code and lots of GitHub issues. Which status values mean what? Is
ops in describe a map or a list? Where does the end of an interrupted
evaluation go? What happens to a session when its client goes away in the
middle of an eval? Server authors usually find out one bug report at a time.
Client authors don’t have it any easier, as every server has its own quirks, and for many years the only way to find them was to try your client with every server you could get your hands on. I’ve been on both sides of this conversation for well over a decade (CIDER is a client, nREPL is a server), so believe me - I know the pain.
Why bother? Because I’ve always seen nREPL as something bigger than Clojure.
Back in 2019 I wrote that nREPL is similar in nature to
LSP, only much simpler, and I
still believe that. For any language that can evaluate code at runtime, nREPL
is a much simpler alternative to LSP. Implement eval, interrupt and
load-file, throw in completions and lookups if you feel like it, and every
nREPL client out there becomes an editor integration for your language.
That’s not just a dream anymore. These days there are nREPL servers for Clojure dialects running on Python (Basilisp), C++ (jank), .NET (ClojureCLR), Go (let-go) and Node.js (nbb), for Janet and Steel Scheme, and even for Erlang and Elixir (more on those later). Still, “language-agnostic” doesn’t mean much if everyone who builds a server has to check it against CIDER by hand.
The idea of a compatibility suite is not new. When nREPL 1.0 came out in 2022 I wrote that improving the protocol spec and the ability to test against it was where our focus should go next, and a year later the lack of a compatibility test suite made my list of things people hate about nREPL. I even asked if one of you was looking for a fun small OSS project. Nobody volunteered, and the idea spent a few more years on the backburner. This year, thanks to the support of Clojurists Together, I finally made a very focused push on it.
It started with the spec. Late last year Phil Hagelberg wrote a draft of the nREPL protocol spec, which landed in May. A spec is great, but you can’t run a spec against your server, so I started proof. The two feed each other - every time proof finds a place where the spec and the clients disagree, or something the spec doesn’t cover at all, it ends up in a running list, and from there in the spec itself. (A few of those are already pull requests against it.)
When the spec and the clients disagree, proof sides with the clients. For
instance, the spec recommends returning the ops in describe as a list, but
CIDER and Calva both expect a map. A server that follows the spec to the
letter, but that CIDER can’t connect to, is not much use to anyone. That’s
also why proof is a compatibility suite and not a conformance suite. You
can only conform to an official spec, and nREPL doesn’t have one yet.
Checking servers is proof’s main job. It’s a single binary1 that talks to your server over a socket, the same way any client would. It knows nothing about the server’s internals and it doesn’t care what language the server is written in. What it does need is a profile - a small TOML file that tells proof how to start your server and gives it a few snippets of code in the server’s language (an idea I borrowed from jupyter_kernel_test):
name = "My server"
[launch]
command = ["my-server", "--port", "0"]
port-pattern = 'nREPL server started on port (\d+)'
[snippets.value]
code = "(+ 1 2)"
value = "3"
Then you install proof and run it:
$ go install github.com/nrepl/proof/cmd/proof@latest
$ proof run my-server.toml
proof starts your server, runs about 80 checks against it and shuts it down
afterwards. (You can also grab a binary from the
releases, if you don’t have Go
around.) Profiles for nREPL, Babashka, nbb, Basilisp, ClojureCLR, jank,
let-go, dialtone and repartee come with proof, so proof run babashka just
works if you have Babashka installed.
The most important decision in proof’s design is how it grades the checks. A check fails only when some client won’t work properly with your server (or when users will lose data), and the report tells you which client it is and links to the client code in question, pinned to a specific commit. If your server simply does something differently from the reference implementation, you get a warning instead. Here’s a failure from a run against Babashka 1.13.226:
FAIL interrupt.other-connection An interrupted eval ends on its own connection
the interrupted eval's done went to the connection the interrupt came from
why: neorepl interrupt stops an eval that another neorepl process
started, and that process waits for the eval's done on its own
connection forever if it goes anywhere else.
see: neorepl interrupt stops an eval from another process
https://github.com/nrepl/neorepl/blob/462a182c.../src/neorepl/main.clj#L374-L385
see: nrepl/nrepl#498 https://github.com/nrepl/nrepl/issues/498
The idea is that a failure should always be worth fixing and never be a matter of taste. If you think some failure isn’t justified, the links show you exactly what you need to argue with.
Some checks go a step further and send exactly what a particular client
sends, the way it sends it. cider.connect sends the requests CIDER sends
while connecting, calva.eval evaluates code the way Calva does, and so on
for Conjure, vim-fireplace, REPLy, neorepl, clojure-cli.repl and
bb repl --connect. That way the report tells you directly whether those clients will
work with your server.
Once your server passes everything it can pass, you can list the failures you can’t fix yet as expected failures in its profile and run proof in your CI with its GitHub Action. When an expected failure starts passing, proof fails the build and asks you to remove it from the list, so the list can’t go stale.
Last, but not least, the bundled profiles run every day and their reports end up in a compatibility matrix, which shows where the different servers agree, where they don’t and where the spec needs some work.
Servers were always proof’s primary focus, but once the foundation was in place people started asking me how they could check their clients with it. That made a lot of sense to me - after all, the same knowledge cuts both ways. proof has two tools for client authors.
proof proxy sits between a client and a server, passes everything along as
is and records it on the way. You use your client for a while (or run its
test suite through the proxy), press Ctrl-C and proof grades every request
the client sent. Here’s a quick neorepl eval going through it:
$ proof proxy -listen 127.0.0.1:7888 babashka
$ neorepl eval --port 7888 '(println "hi") (+ 1 2)'
client
PASS client.bencode Every frame is valid bencode
PASS client.dict Every request is a dict
PASS client.canonical Frames use canonical bencode
PASS client.id Every request has an id
PASS client.active-id An id isn't reused while its request is active
PASS client.field-types Request fields have the right types
PASS client.required-fields Requests carry the fields their op needs
PASS client.need-input need-input is answered with stdin in the same session
WARN client.close Sessions are closed before disconnecting
PASS client.unknown-op Requests use ops the server supports
9 passed, 0 failed, 1 warnings, 0 skipped
The grading rule is the same, just turned around. A client check fails only
when some server breaks, and it links to the server code in question. (That
warning is fine, by the way. neorepl keeps its session around on purpose, so
the next neorepl eval can use it.)
A proxy sees only what goes over the wire, though, so it can’t tell you how
your client copes with the replies of different servers. That’s what
proof serve is for. It’s a small nREPL server for client test suites, which
behaves like nREPL unless you ask it to behave like some other server in some
particular way - send only the value of the last form (like Basilisp, jank and
dialtone), drop what the code prints to stderr, have no interrupt op,
deliver its replies a byte at a time, and so on. None of those scenarios are
made up. Every one of them is something a real server does (or something TCP
can do to any server’s replies). -like turns on all the quirks of a server
at once, so you can run your client’s tests against “jank” without installing
jank:
$ proof serve -listen 127.0.0.1:7888 -like jank
So far, so good. But does it actually find anything? You bet! Here are some of the things proof turned up in the past couple of months:
done after its client goes away in
the middle of an eval (#509).
Oops!eval-error status, sessions sharing *1 and
the current namespace, and a request that throws taking its whole connection
down.Michiel Borkent fixed the Babashka and nbb issues the same day I reported them (or the next one), Conjure fixed its encoder the next day and Calva within a week. That’s the Clojure community for you!
I was also super happy to see other people picking up proof before I even got
around to announcing it. Tom Waddington has been running it against his nREPL
implementations for Janet and
Steel Scheme since early October
(nrepl-janet even tests its client with proof serve), Jeaye Wilkerson
suggested using it for
jank’s nREPL server, and Kyle Cesare is already
fixing what it found there.
That’s exactly what I was hoping for!
The projects that benefited from proof the most were my own, though. This year I built a few toy nREPL implementations, mostly for fun and to see how well the protocol holds up outside of Clojure:
close with session-closed, didn’t echo unknown ops and returned only the
last value of several forms, and fixing those uncovered a race after close
and temporary sessions that never stopped.err and unknown sessions wrong.And then there’s
neorepl,
the CIDER-inspired terminal REPL I’ve been working on lately, which is just as
happy to be used by coding agents as by humans. neorepl and proof pretty much
grew up together. I ran neorepl through proof proxy and every scenario of
proof serve, which caught a few bugs before neorepl 0.1 was out, and proof
checks every server with the exact requests neorepl sends. It’s also how I
found the interrupt bugs in nREPL above, which hit neorepl harder than most
clients. Its commands are separate processes sharing a session, so
neorepl interrupt stops an eval that some neorepl eval started, and that
neorepl eval used to wait for its done forever.
I guess I should spell out who proof is for. If you’re using nREPL through CIDER or Calva you’ll probably never run proof yourself (although hopefully you’ll feel its effects). proof is a tool for tool authors - people writing nREPL servers, clients and middleware.
I really hope that it will make it a lot easier to grow the nREPL ecosystem. These days anyone can put together an nREPL server or client in no time with the help of tools like Claude. Writing the code is no longer the hard part - knowing whether the result actually works with CIDER, Calva and friends is. proof gives you (and your coding agent) a fast feedback loop and failures that explain themselves: what went wrong, why it matters and which client code depends on it. That’s usually all an agent needs to fix the problem.
Naming is hard! Luckily, the nREPL world has a tradition that makes it a bit easier, as many nREPL clients are named after drinks (CIDER, neat, mezcaml, chaser and so on). proof is not a client, so it bends the rule a bit, but it still belongs at the bar. The proof of a spirit is a measure of its strength, which is more or less what this tool measures for nREPL servers. And running it gives you proof that your server works with the existing clients (or a list of the reasons why it doesn’t). Two meanings for the price of one!2
proof is still in its early days, but it already covers the core of the protocol, the exact requests of the most popular clients and the server quirks clients have to deal with. Now it needs more users.
So, if you’re working on an nREPL server or client, please take proof out for a spin and let me know how it went! I’d love to see your server in the compatibility matrix, and if you think some failure isn’t fair, open an issue and let’s argue about it. And if you’re a casual Clojure hacker who’d just like a nice REPL in the terminal, give neorepl a try:
$ bbin install io.github.nrepl/neorepl
Big thanks to Clojurists Together for supporting my work on nREPL, to Phil Hagelberg for getting the spec going, and to the maintainers of all the servers and clients who were so quick to fix the problems proof found. You rock! In the (n)REPL we trust!
That’s all I have for you today. Keep hacking!
Written in Go, of all things. A Clojure tool would have been the obvious choice, but proof shouldn’t favour any of the languages it checks, and a single binary without a runtime is easy to drop into any CI. ↩
“hangover” would have been a good name for what you get when a server forgets to send done, but it’s a hard sell for a project. ↩
-1:-- proof: How Strong Is Your nREPL? (Post Meta Redux)--L0--C0--2026-11-05T21:00:00.000Z
Here's my contribution to this month's Emacs Carnival, which explores how we discover Emacs features.
I'm adding bookmarks into my workflow. I tend to get lost among
multiple windows in which several Org files reside, as well as windows
that browse the Internet (*eww*), or house *Help*, *Apropos*,
*Messages*, *Customize* (or TBD). It's important that I can jump back
to my main task. I'm tired of flailing away
with other-window and next-buffer . I suppose I could globally
bind C-c C-x C-j to org-clock-go -- that certainly would help.
But I may need to access a window of secondary importance. Also, some
windows have nothing to clock into, so I'd still need a mechanism that
works outside of Org.1
Bookmark keybindings share a prefix with rectangle commands, namely
C-x r . But since I use rectangle functions, too, I
might devise a new set of keystrokes to divorce the bookmark commands
from rectangle commands. This would make the C-x r C-h
help window easier to understand. It makes sense that the rectangle
editing commands are grouped under
C-x r, but why are bookmarks shoved in there, too?
Perhaps it's because C-x b already was dedicated to
the switch-to-buffer function, so it had to go
somewhere.2
How often do I adopt a new feature? Based on the versioning of my init file, I make 0.65 changes on average every day. But perhaps 75% of the changes are minor adjustments due to preference or to not having grepped a new feature correctly. So let's say 0.16 changes per day, or about 5 every month.3 It would be higher, but I have to eat, too!
When I was getting paid for my productivity, I belonged to the Set and Forget team. I would devise and validate workflows, trading that effort for the real work I was supposed to do. Other software programs forced updates on users. This annoyed me, especially when a feature was removed or a keystroke changed. I greatly appreciated Emacs for not doing that. I'd install a new Emacs version only when provided with a new computer.
Now that I answer to no one4 exploring Emacs features has become my past time.
I learn about Emacs from many sources. The following list of examples is not all-inclusive:
When you're committed to self-improvement and life-long learning as I am, discovering Emacs features becomes an obsession!
1 I've also started to use the mark-ring, popping mark to navigate within a buffer.
2 Buffer functions came first. I infer this from the initial copyright years of window.el and bookmark.el, which are 1985 and 1993, respectively. window.el provides the functions.
3 Here are the dates of my first and latest init file updates since I started the current versioning system:
4 I answer to no one except for my wife.
2026-11-10 Change timestamp of emacs01, as requested by Anonymous Commenter. And actually, the real name of the file is .emacs.~1~, although it was simplified for this article.
-1:-- Emacs Carnival November 2026 (Post Raymond Zeitler)--L0--C0--2026-11-05T19:31:34.544Z
-1:-- Tracking issues with Emacs and Org mode dynamic blocks (Post Isa Mert Gurbuz)--L0--C0--2026-11-05T16:47:00.000Z
neorepl 0.5 is out! When I announced neorepl last month, I wrote that I’d always wanted a terminal REPL that felt like CIDER, without the Emacs part. A few releases later I think neorepl is mostly there, so this one went out with “CIDER in a terminal” for a tagline. It also has everything from the “What’s next” list in the 0.4 post, which almost never happens with my plans.

That’s where you spend most of your time in a REPL, so that’s where most of the work went:
defn lines up with doc-string?. The lookups happen in the background
now, so typing never waits on the server.$EDITOR, as it does in bash, for
when a form outgrows the line editor.set editing-mode vi in ~/.inputrc gets you vi’s keys. neorepl takes
the readline settings JLine knows from there, and what’s under
$if neorepl is for neorepl alone.Not everyone likes that much going on around the cursor, so ,set lists
the REPL’s settings and turns them on and off, C-x C-h, C-x C-p and C-x C-q
toggle eldoc, pretty printing and quiet mode, and
~/.config/neorepl/config.edn says what they start as:
{:eldoc false
:print-length 100
:autoreload true}

,ns without a name opens a full-screen browser of the project’s
namespaces, or every loaded one after you press a. Type / and part of a
name to narrow them down, → to see a namespace’s public vars with their
docs, Enter to switch to it and e to open it in your editor. ,spec does
the same for the spec registry: a spec’s form, the specs it names one key
away, and x for an example generated from it, as long as test.check is on
the server’s classpath. (With cider-nrepl, x only works since
0.5.1, which came
out today as well. I found that bug recording the GIF above.)
,refs lists the functions that use a var, and ,deps the ones a function
uses, courtesy of cider-nrepl’s fn-refs and fn-deps. They come in handy
before you change a function’s arguments, and even more so for coding
agents, which get them as neorepl refs and the MCP refs tool. They only
look through the project’s code that’s loaded, mind you.

,autoreload has the REPL reload the namespaces whose files changed before
each evaluation, and before ,test, ,inspect and ,ns, so you’re never
calling yesterday’s version of a function. It’s
clj-reload under cider-nrepl, which
reloads the namespaces that depend on the changed ones too, in the right
order, and keeps what defonce defined. When a reload fails you get its
error, rather than an evaluation against half-reloaded code.
Coding agents need this even more than people do, as they edit files all
day long and forget to load them about as often. neorepl eval --reload and
the reload option of the MCP eval tool take care of that.

A few more things CIDER users will recognize:
tap> show up above the prompt, and ,tap opens the last
one in the inspector, with cider-nrepl 0.64 or newer.,profile times every call of the functions you name, or of a whole
namespace, and without a name shows what it measured: how many calls each
function had, and how long they took, on average, in all, at the shortest
and the longest. neorepl profile does the same from the shell.The CLI was meant for scripts from day one, and it turns out an editor
doesn’t need a plugin to use it. neorepl eval -f FILE --line N:COL -
evaluates the top-level form at the cursor in the file’s namespace, with
the buffer’s text on standard input, so unsaved changes count too, and
neorepl eval --ns NS - does the same for a selection.
Helix can’t send a buffer to a command, so there
the keys save the file first, and that’s all it takes:
[keys.normal."+"]
e = [":write", ":sh neorepl eval -s editor -f %{buffer_name} --line %{cursor_line}:%{cursor_column}"]
l = [":write", ":sh neorepl load %{buffer_name}"]
doc/editors.md
has complete setups for Neovim, Emacs and Helix. (Yes, Emacs. Please don’t
tell anyone.) The REPL sees whatever the editor evaluates, as they share a
server, so with the REPL in a split next to your editor you get a pretty
decent setup out of a few lines of config. The setups evaluate in a session
of their own, called editor, so ,sessions editor takes the REPL there,
and ,pst shows the last error your editor ran into.
neorepl’s tests run against fakes that behave like cider-nrepl, which says
nothing about the next cider-nrepl, or the next babashka. So now CI also
runs neorepl against the real thing: nREPL with cider-nrepl, started by the
Clojure CLI and by Leiningen, babashka’s server, ClojureScript on Node
through piggieback and through shadow-cljs, nbb and Basilisp. That turned
up a fair share of bugs on both sides of the wire. Running a ClojureScript
namespace’s tests through piggieback failed with a circular dependency, a
ClojureScript test’s error came with the line NaN, code that threw on nbb
didn’t fail neorepl eval, and source, macroexpand and apropos didn’t
work on Basilisp. All fixed now.
neorepl needs babashka 1.13.227 or newer these days, as that’s the first release with all the JLine and socket classes it used to work around.
in-ns, and Michiel fixed them within a day or two.
They’ll be in the next nbb release. Thanks again, Michiel! On the
babashka side, the test output going to the wrong message and info
knowing nothing about namespaces are fixed on master.0.6 is about getting neorepl to more people:
After that comes 1.0, where the CLI’s exit codes, its edn and JSON output and the MCP tools become a contract I promise to keep.
$ bbin install io.github.nrepl/neorepl
$ cd my-project
$ neorepl
The CHANGELOG has everything I skipped here, and the README has the details. Please keep the issues and ideas coming!
Keep hacking!
-1:-- neorepl 0.5: CIDER in a Terminal (Post Meta Redux)--L0--C0--2026-11-05T15:34:00.000Z
I’m happy to announce that neocaml 0.11 is out! I never got around
to writing about 0.10, which was mostly about neocaml-utop (a utop
backend that talks to utop via its native editor protocol), but 0.11 is a
different story. Its changelog is twice as long as that of any release before
it, and by now I’ve stopped pretending that a grand 1.0 is just around the
corner.1 There’s a lot in there, but three things stand out for me - OxCaml
support, indentation styles, and much better support for documentation. Here’s
why…
OxCaml is Jane Street’s set of extensions to OCaml - modes and
modalities, kinds, unboxed types, stack allocation and so on. You can use them
today with an OxCaml compiler switch, and Jane Street’s libraries use them all
over the place. A lot of the heavy lifting happened upstream, as
tree-sitter-ocaml 0.26 learned to parse OxCaml, and
Tim McGilchrist bumped neocaml’s grammars to it. Pieter
Goetschalckx (the tree-sitter-ocaml maintainer) once again cut an
ABI 14 build of the release, so we didn’t have to break anyone’s
Emacs. (see the 0.9 post
for the whole ABI saga) Huge thanks to both of them!
A grammar that parses the code is only half of the job, though. Here’s a bit of OxCaml, the way neocaml shows it:

neocaml now highlights and indents all of this. The new keywords (stack_,
exclave_, local_, global_, borrow_ and kind_), modes and modalities,
kinds, unboxed types and literals (float#, #1.0, #(...)), immutable
arrays ([: ... :]) and comprehensions are all covered. The indentation
follows the way ocamlformat lays out Jane Street’s own OxCaml
libraries (e.g. portable, unique and parallel), which is why the body of
an exclave_ isn’t indented, while those of stack_ and local_ are.2
Kind definitions also show up in imenu and work with the defun navigation
commands.
If you don’t write OxCaml, nothing changes for you - plain OCaml looks exactly
the way it did before. If you do, there’s nothing to turn on in neocaml. Just
make sure Emacs sees your OxCaml switch and you’ll get its ocamllsp
and ocamlformat as well. The docs have all the details.
Here’s a confession - neocaml’s indentation used to be a bit of a mix. Some
layouts followed ocamlformat’s conventional profile, some followed
janestreet, and a few followed neither. That’s a problem, as OCaml doesn’t
have one indentation style everyone follows. ocamlformat ships several
profiles, Jane Street’s code doesn’t look like the compiler’s, and plenty of
projects never run a formatter at all.
So 0.11 lets you pick one of three styles via neocaml-indent-style:
ocp-indent, which indents the way ocp-indent does out of the boxconventional, after ocamlformat’s default profile (used by ocaml.org, ppxlib and Irmin)janestreet, after ocamlformat’s janestreet profile (used by Jane Street’s libraries, dune and ocaml-lsp)They agree on most things and differ on a handful of layouts, e.g. how far the body of a match case goes:
1
2
3
4
5
6
7
8
9
10
11
(* ocp-indent and janestreet *)
match value with
| Some payload ->
finish payload
| None -> 0
(* conventional *)
match value with
| Some payload ->
finish payload
| None -> 0
The best part is that most of the time you won’t have to pick a style yourself.
By default neocaml looks for the project’s .ocamlformat and picks the style
that matches its profile (it also respects cases-exp-indent). Without an
.ocamlformat it checks for an .ocp-indent file, and without either you get
the ocp-indent style, as that’s what most projects that don’t use
ocamlformat indent with. (e.g. opam, Rocq, Frama-C, Eio and the
compiler itself) You can
also set the style per project in .dir-locals.el, or switch it for the
current buffer with M-x neocaml-set-indent-style.
I also wanted to know how well all of this works on real code, instead of
guessing. So I wrote a couple of small scripts (they live in dev/) that format
a bunch of OCaml files with each ocamlformat profile and count the lines
neocaml would indent differently. I ran them on the almost 300 files of the
opam packages in my default switch (mostly Jane Street’s base), and 0.10
didn’t look great. About one line in ten had no indentation rule at all, so
TAB simply left it wherever you typed it, and only 81.9% of the lines landed
where ocamlformat’s conventional profile puts them (77.8% for janestreet).
Ouch! With the matching style, 0.11 gets 97.5% and 98% of them right.3 Not
perfect, but pretty close!
Keep in mind that indentation only places the lines you’ve broken, it doesn’t
break them for you. If you run ocamlformat on save it has the final word
anyway, but with the matching style less of what you type moves around when
you save.
The third big theme is documentation. A few months ago Matthieu Lemerre
suggested (#60) that neocaml should render the ocamldoc markup in
comments, instead of showing it as a soup of braces. I loved the idea, and in
0.11 doc comments finally look like documentation - {b bold} is bold, {i
italic} is italic, [code], {[ ... ]} and {@ocaml[ ... ]} are shown as
code, and {!references} and tags like @param get faces of their own. This
is the new doc-markup font-lock feature, and it’s enabled at the default
font-lock level. Here’s how the doc comments in an interface file look now:

Tim also contributed neocaml-odoc-mode (#46) for odoc’s
standalone .mld documentation pages, built on Tim’s own Tree-sitter grammar
for odoc. You get font-lock for headings, inline markup,
references, links, tags, lists and tables, plus indentation and imenu. On
Emacs 30+ the code in {@ocaml[...]}, {@dune[...]} and {@opam[...]} blocks
is highlighted as well, using the grammars for those languages:

Run M-x neocaml-odoc-install-grammar to get started, and check out the
docs for more.
While I was at it, I also fixed M-q and M-j in comments. Embarrassingly,
M-q used to always fill the first paragraph of a comment, no matter where you
were in it, and it merged code blocks into the text around them. M-j now
continues the * of comments that start each line with one.
Those are just the highlights, of course. Here are a few more things that I think you’ll like:
neocaml-mlx-mode for .mlx files (OCaml with JSX, as used by
Melange and React), contributed by Akira Komamuradune’s
promotions (C-c C-o T, C-c C-o = and C-c C-o P), with their own
bindings in neocaml-cram-modedune project in a monorepo gets its own REPLneocaml-format-buffer replaces only the text that changed, so point and
the window positions stay putHere’s the REPL highlighting in action:

Most setups will keep working just fine, but a few changes in this release require some action on your part:
tree-sitter-ocaml 0.26 now, so reinstall the OCaml grammars
with C-u M-x neocaml-install-grammars. The dune grammar moved to its new
home, ocaml-dune/tree-sitter-dune, so reinstall it as well
with C-u M-x neocaml-dune-install-grammar. neocaml will warn you if your
grammars are too old.ocaml-eglot and
merlin, so they had to move. In
the REPL minor modes sending the phrase at point is now C-c C-e, sending it
and moving to the next one C-c C-s, loading the file C-c C-u and
interrupting the toplevel C-c C-q. The dune commands moved from C-c C-d
to C-c C-o.ocamlformat
nor ocp-indent a few layouts will move, so set neocaml-indent-style if the
ocp-indent style is not your cup of tea.With OxCaml, mlx and odoc on board, neocaml now covers pretty much every kind
of OCaml file I can think of. Famous last words, right?
So, what’s next? I don’t really have any big plans for 0.12. I’d like to switch
neocaml-mlx-mode to the dedicated grammar from
tree-sitter-mlx once it has an ABI 14 release, and there’s
the usual pile of smaller ideas in the roadmap. No promises, though.
Big thanks to Tim McGilchrist, who did a ton of work on the grammars
(OCaml, dune, opam and menhir) and the odoc support! Thanks
to Akira Komamura for bringing mlx to neocaml, and to Alessio
Duè for fixing a sexp navigation bug! And thanks to everyone who reported problems
and shared ideas - many of the improvements in 0.11 started as an issue on
GitHub.
As usual - update from MELPA, play with it, and let me know how it goes. The full list of changes is in the release notes.
That’s all I have for you today. Keep hacking!
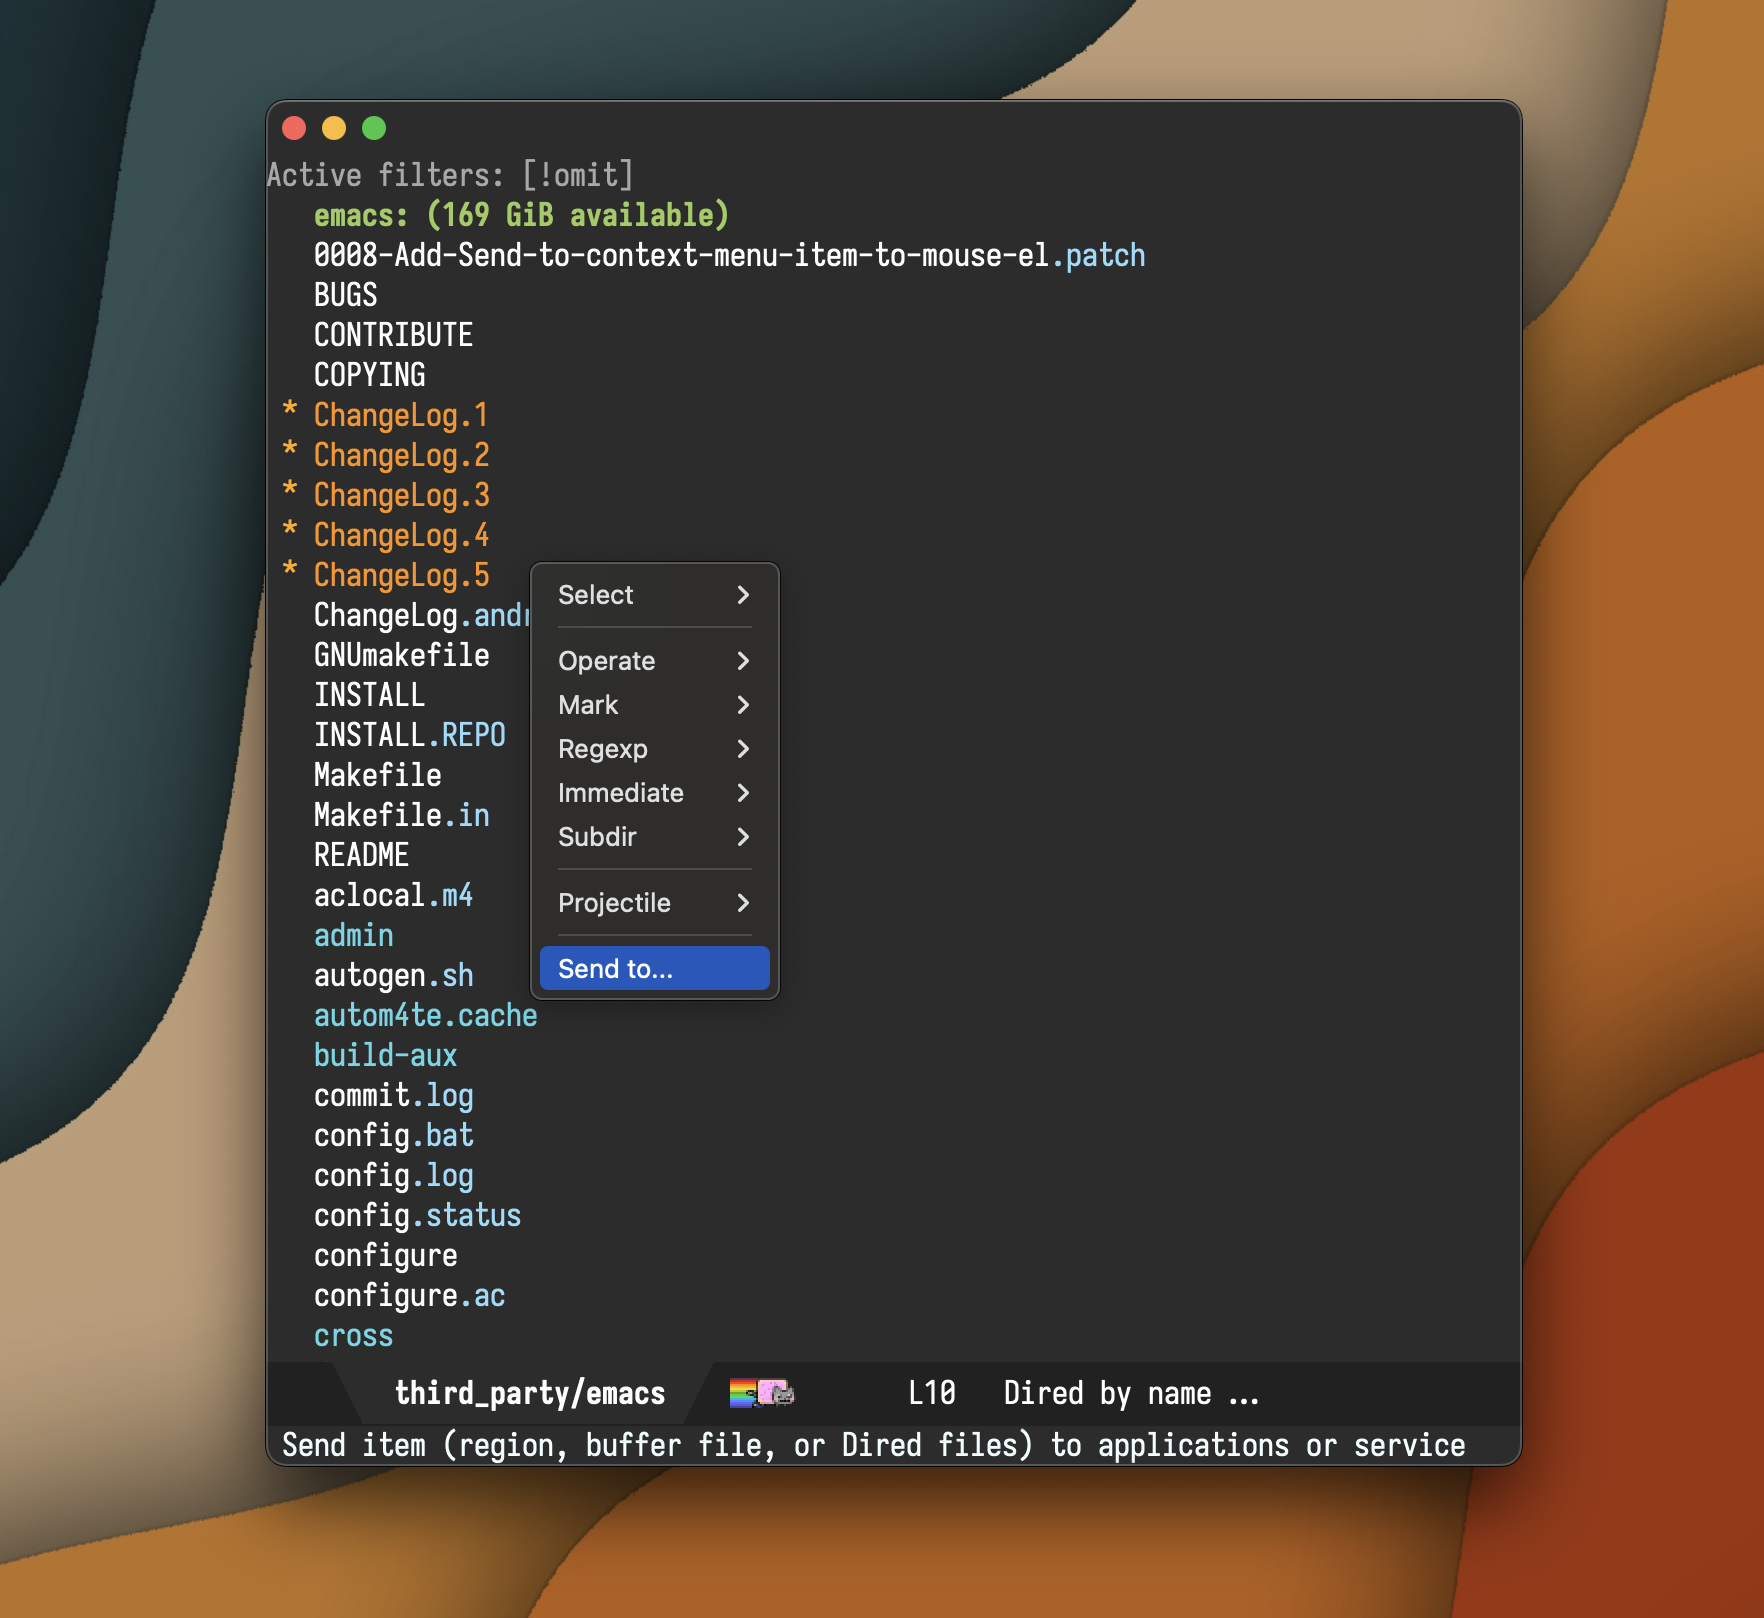
-1:-- Neocaml 0.11: OxCaml, Indentation Styles, and odoc (Post Bozhidar Batsov)--L0--C0--2026-11-05T05:30:00.000Z
A comment from Dave on Emacs salmagundi, 2026-10-11:
I preload compile-history in some directory trees via .dir-locals.el, and then I can just type M-x compile and choose something from the history. I document this at https://davemq.github.io/2026/05/12/remote-linux-dev-with-emacs.html.
That's a very nice tip!
He continues
This multi-compile package looks interesting. But neither your article or the README for the package have examples of running it. Do I type M-x multi-compile?
No, the command is actually M-x multi-compile-run. I probably should have
mentioned that at least once when writing about it.
In the upstream repo the information is located at the very end of the README. It probably should be mentioned much earlier.
-1:-- Follow-up: Emacs salmagundi, 2026-10-11 (Post Magnus)--L0--C0--2026-11-04T19:09:00.000Z
A long while ago (in February this year) I got nice comment from Mike on my switch to project.el
That said, I was surprised to see your comment about having to set
vc-handled-backendstonilbecause otherwisevcinterferes withmagit, as I have not seen any such conflicts myself, and I made the transition toproject.elseveral years ago.Maybe it's not worth it to get into it: you obviously found a straightforward workaround, and perhaps there's additional background that you simply didn't include, or I'm over-interpreting "interfere" when you just mean some quirk that I just no longer notice having lived with it for long enough—but it seemed worth it to mention that this may not be universal, and thus might be worth looking into?
I did a search through my commit history and found that I disabled it in August 2024:
Disable VC completely
Apparently VC was activated when loading the config as all of it is in git repos (thanks to straight). This resulted in a question about following a symbolic link in a git repo (thanks to 'vs-follow-links being set to 'ask). I could have turned off the asking, but since I prefer to use magit anyway and I don't use any other VCS I decided to turn VC off completely for now.
Yes, there's a type in there, vs-follow-links should be vc-follow-symlinks I
believe.
I reverted about two years later when I switched to elpaca:
Remove the config for VC
It looks like the need for disabling VC disappeared with the move from straight. Now only .projectile is an extra marker for projects.
I would be very surprised if my workaround is still needed when using straight.
-1:-- Follow-up: Switching to project.el (Post Magnus)--L0--C0--2026-11-04T18:59:00.000Z
If you’ve been around Irreal for as little as a year and a half, you know that my most important and most used iOS app is Journelly. I use it as my memo book to record my daily activities and random things that I want to remember. For example, if I see some article or ad in my browser, I can ask Safari to share it with Journelly and a Journelly entry is automatically made complete with a link to whatever it was I wanted to capture. Each entry contains a date/time stamp as well as the location of where the entry was made.
Best of all, Journelly keeps its data as an Org file so I can query or edit it in Emacs. Of course, Journelly has a search function but sometimes I want to do a more complicated search or even to just count the number of entries in the database (4361 as of right now). Having the database as an Org file means that my data is available on all my devices, even if that device is a Mac.
I’ve been using Journelly since March 2025, ever since it was in beta, and have never looked back. Lately, however, it’s been getting a bit laggy, something I put down to my large database. I was on the verge of truncating my active data to the most recent entries in order to improve performance when Álvaro Ramírez pushed a new beta—v1.5(4)—that completely solved the problem. Now Journelly performs just like it did when I started.
If you are an Emacs user and are using an iPhone/iPad, I can’t think of any reason why you wouldn’t want to use Journelly. It allows you to integrate your day-to-day note taking with the power of Org mode. Even if you aren’t an Emacs user, you’ll probably find Journelly useful. It can also save its data as a markdown file so you can still get all the benefits of an easily accessible and editable database even if you prefer another editor.
-1:-- A New Journelly Beta (Post Irreal)--L0--C0--2026-11-04T15:47:04.000Z
This is in response to issue 12 in my dotfiles.git. I am posting it here since (i) some of the information is useful in general and (ii) it is easier for me to find it here.
The specifics of my Emacs configuration:
What is the motivation to divide between what seems to be like e.g. prot-lisp consisting of what seems to be just functions (library) and prot-emacs-modules which seems to be just package configuration (like what you’d fine in the body of a use-package declaration)?
I keep prot-emacs-modules and prot-lisp separate because they have
a different role. The latter consists of what effectively are Emacs
Lisp “packages”. I write them in the same style as actual packages
that I maintain (check https://protesilaos.com/emacs).
The modules are the specifics of my configuration. They have the exact preferences I rely on in my current session. A package may define options. The module picks one among them.
This is exactly what we all do when we configure a package from GNU
ELPA, for example: the package defines options and in our init.el we
set it up as we see fit.
Strictly speaking, this distinction is not necessary for a personal Emacs configuration. All the code is mine. I could easily hardcode values, not provide abstractions, and not bother with clear points of entry. Doing so would work well for my use-case, which is the main goal of all this code, anyway. But that would be a counterproductive habit; “counterproductive” because I want the code I write to be easy for others to copy and adapt. It also conditions me to be more thoughtful with my programs and more organised with my writings.
There are some exceptions where a function is defined in the modules. This is either because the function really is about my configuration or it is part of some experiment I am doing.
Also, is there anything you’d suggest to make it easier to try out e.g. your modeline from the config and and tweak from it into my own? Copying the contents of those two files and trying to evaluate it is not enough as it depends on other functions. I guess the only way is to take your whole config and play with it in a separate emacs –init-directory and dig around for relevant parts, right?
It is probably better for you long-term to follow the video I did about writing a custom modeline and tweaking its colours:
By understanding those concepts, you will be prepared to copy only the
parts you need from prot-modeline.el and tweak them accordingly.
That granted, here is how you can get my code into your setup (and
anything from prot-lisp/ for that matter). The use-package for
prot-modeline is the equivalent of what I have in my modules right
now.
(use-package prot-common
:vc ( :url "https://github.com/protesilaos/dotfiles"
:lisp-dir "emacs/.emacs.d/prot-lisp"
:main-file "prot-common.el"
:rev :newest))
(use-package prot-modeline
:vc ( :url "https://github.com/protesilaos/dotfiles"
:lisp-dir "emacs/.emacs.d/prot-lisp"
:main-file "prot-modeline.el"
:rev :newest)
:config
(setq mode-line-compact nil) ; Emacs 28
(setq mode-line-right-align-edge 'right-margin) ; Emacs 30
(setq prot-modeline-show-frame-name (alist-get 'undecorated initial-frame-alist))
(setq-default mode-line-format
'("%e"
prot-modeline-kbd-macro
prot-modeline-narrow
prot-modeline-buffer-status
prot-modeline-window-dedicated-status
prot-modeline-input-method
" "
prot-modeline-buffer-identification
" "
prot-modeline-major-mode
prot-modeline-process
" "
prot-modeline-frame-name
" "
prot-modeline-vc-branch
" "
prot-modeline-eglot
" "
prot-modeline-flymake
" "
mode-line-format-right-align ; Emacs 30
prot-modeline-which-function-indicator
prot-modeline-notmuch-indicator
" "
prot-modeline-misc-info)))
use-packageIt seems you don’t use use-package (I see
(require ...in the modules) anymore? Curious why.
I consider this “sand in the gears”. It forces those who read my configuration to slow down and be careful about what they are copying. If they just paste my Elisp into their setup, they will get an error. Slowing down gives them the chance to read the code and think about what they are working towards.
Yes, this sounds like I am doing them a disservice. But I think they will benefit from this practice long-term. Copying willy-nilly is how you never learn.
Concretely about the use of require, in the modules I use my own
macros. Every require should be wrapped in a prot-emacs-configure.
Not all my modules rely on require though. I have some packages that
are loaded when a certain condition is met, typically via a hook.
In prot-lisp/ the use of require is standard: this is how packages
are supposed to do it.
By the way, writing my own configuration macros has helped me understand things at a deeper level. It also gives me maximum control over my setup. But the real reason is the sand in the gears that I alluded to.
Is there any reason to autoload features? I’ve come across some guides on using Emacs and it seems people tend to prefer to autoload everything as much as possible but I feel like it only makes sense to autoload only features you might not use during a session. The time to load on startup when you front load instead of autoload seems less important than the time it takes to load when you actually use a feature during a session. Especially if running Emacs as a server or using a single long-running instance.
With use-package you get deferred loading when you use keywords such
as :bind and :hook. Internally, this depends on the autoload
mechanism that Emacs has. Autoloads are hints that inform Emacs about
the existence of some function or variable in a certain file. When
that symbol is called for the first time before its file is loaded,
Emacs goes to the corresponding file, evaluates everything, and then
runs the original code. For example:
(autoload 'prot-test-hello "prot-test")
If we call prot-test-hello, Emacs evaluates prot-test.el, and runs
prot-test-hello. This works only if the file is in the load-path.
Users generally do not need to understand the technicalities. When
installing a package, Emacs generates an index of all the autoloads
automatically. If you are curious, go to the elpa/ subdirectory of
your Emacs directory, find a package, and read the autolaods file
(e.g. denote-autoloads.el).
Strictly speaking, deferred loading is not necessary. If you are going run Emacs for several hours non-stop, then the ~60 seconds it takes to load an average configuration do not matter. Even ten minutes are not be important in such a scenario: you can brew a coffee in the meantime.
Deferred loading is still beneficial though:
Autoloads help you discover new features. For example, when you press
M-x in a generic Emacs you are presented with thousands of options.
Most of those are not loaded yet. Emacs just knows the symbols and
will load their files when you make the selection. A package developer
can leverage this feature to provide functionality that may be useful
only under certain circumstances. That is a helpful way for the user
to notice the before and after states. It also gives the user maximum
control of what to load and when, which improves confidence in one’s
Emacs configuration.
Do you ever run Emacs on the terminal or GUI only and do you always have a single long-running instance or do you sometimes use multiple instances?
I always use the GUI. It can combine different font families and font sizes and it can also display images—how else am I supposed to check my selfies? The terminal is fine in its own right and is especially useful for remote connections. But I do not have that use-case.
My terminal emulator is xterm, by the way. It works well, though I
do not rely on it. Everything that could be done in a terminal is
handled by Emacs. I also am on Debian stable, so trying the newest
programs is neither a straightforward option nor a priority: I have a
stable setup and focus on getting work done.
I use a single instance of Emacs. In my configuration I also have
server-start. This gives me the option to evaluate Emacs Lisp code
even when Emacs is not focused, such as when I switch the theme of my
entire desktop environment or window manager.
I do not run Emacs for long hours. When I am done with whatever I am working on, I switch off the computer. The typical workflow is for 2-3 hours maximum. Then I will do some outdoor activity.
Any thoughts on using Evil?
It is fine and I am indifferent to it. What makes Emacs so nice is that you can evaluate Emacs Lisp live and work with the new state. The choice of keybindings is a personal choice. There is no better or worse.
People will, of course, argue about which paradigm is more efficient. This is the kind of knowledge that seldom translates into real-world productivity. The bottleneck is how fast and how well you can think. Then what matters are the qualities of your output. Moving text around quickly does not make you productive per se or, indeed, a decent writer/programmer.
This is a matter of comfort though, which can indirectly influence your productivity simply by improving your mood and willingness to write. I put colours and fonts in that same category. If it makes you feel better, then use it.
That granted, to configure evil-mode properly you need to have a
solid understanding of Emacs and be willing to control every part of
your setup. Otherwise you will run into cases where something does not
work as expected and you will not know how exactly to change it.
It seems like you’re willing to embrace Emacs defaults–is there anything you’ve still maintained Emacs to be more Vim-like, e.g. modal and arguably more ergnomic/mnemonic?
The general scheme of Emacs default keybindings is good enough for me.
Though I change plenty of keybindings to do what I want. Actually, I
plan to rebind basics such as C-n, but I have not found the time to
do it thoroughly. There are many default keybindings that I do not
like.
I do not think Vim is ergonomic by default. Impulsively reaching out to the Escape key is not helpful, especially if you are twisting the wrist in the process. Typing Shift with the relatively weak small fingers is not beneficial either. Yes, you can circumvent those, but I am referring to the out-of-the-box experience, because if you are thinking about making changes then you might as well do the same for the Emacs-style keys.
Emacs keys are not ergonomic either. Ergonomics is a matter of the entire office setup, from the keyboard, to the desk, the placement of the monitor, the typing style. I have an article on the matter: https://protesilaos.com/codelog/2026-05-04-emacs-keyboard-ergonomics/.
My custom keyboard has hjkl mapped to the arrow keys on a so-called
“layer” that I can activate with my thumbs. The yuio keys above
correspond to Home, PageDn, PageUp, End, respectively. Those
are the bigger motion counterparts of the cardinal directions. Extend
this to Ctrl and one of those keys to perform a different motion,
like C-<home> to go to the beginning of the buffer, C-<right> to
move forward by a word. This works everywhere, by the way.
I actually have plenty of articles on the topic of keyboards, if you are so inclined: https://protesilaos.com/keeb.
I may have missed this, but how do you approach persistent session (if at all)?
I do not. This is not necessary in my workflow. I have bookmarks for the buffers/files I visit frequently. Then I have Git projects that I always keep in a clean state with a history that is meaningful. When I need to work on something, I switch to the bookmark/project and start from where I left it.
I like that if I return a project I’ve worked on a few weeks ago, restoring these aspects is a good way to suggest where I last left off instead of starting from scratch (little things like window layout or set of open buffers is suggestive of progress of the project).
This is a matter of how one’s brain works. Mine is more abstract, so
having things in a specific spatial arrangement does not add much
value. Configuring Emacs to take care of all relevant cases is thus
not appealing to me. I will commit my changes and leave everything in
a condition that makes the next step obvious. I am happy to write
TODO and FIXME comments in my code and/or have a relevant task in
my Org agenda. This is a matter of logical sequencing. It is easier
for me to reason about it.
I used to load the built-in desktop.el. Then I realised that loading
hundreds of buffers for something that I might not need is
counter-productive. Furthermore, storing a specific state for a
potential future occasion requires that I remember to load the right
file, manage all such files, and so on, which is cognitively
burdensome and ultimately no more efficient than working with Git.
🔷 Consider making a donation.
-1:-- Reply to Emacs questions about configuration, Evil, and more (Post Protesilaos)--L0--C0--2026-11-04T00:00:00.000Z
Today is election day in the United States, and if you’re eligible to vote and have already done so, thank you. While we await the results over the next several days, here’s something to help pass the time, particularly if you use Org mode HTML export in Emacs.
As with many tools that export HTML, Org mode leaves most aesthetic decisions like CSS layout and typography to the user to define. Org mode’s default HTML export output is serviceable, but why settle for that? In particular, my expectations for HTML export in 2026 are this:
CSS has long supported both of the above with media queries. More recently, CSS has a light-dark() function for handling OS appearance changes.
Org mode has numerous ways to customize how CSS is used in export (see org#CSS support). For my purposes, setting the customizable variable org-html-head-extra serves my needs as it will be the default behavior for exporting Org to HTML. For any special cases, I can locally override that variable.
The Elisp I use in my Emacs initialization file is as follows:
1 2 3 | |
Using the function insert-file-contents lets me specify the CSS in a separate file. For the above example, I’ve defined my CSS in the file cc-org-html.css. Readers are welcome to use or modify cc-org-html.css to their satisfaction.
Adaptive Dark Mode
Just as I was finalizing this post, I saw this WebKit post (Introducing Adaptive Dark Mode | WebKit) pop up in my feed today: apparently Safari 27.3 beta includes support to automatically adapt a website that does not support OS appearance changes. This is an early and browser-specific feature, so I still think specifying light and dark behavior is worthwhile, especially since the light-dark() function makes this so easy to do and is widespread.
Addendum Nov 6, 2025
At the date of posting, the file cc-org-html.css had errors in the call to light-dark() which are now corrected. The above link to this file has been amended to point to the corrected file.
-1:-- Beautifying Org HTML Export (Post Charles Choi)--L0--C0--2026-11-03T21:45:00.000Z
Randy Ridenour has taken another step in the journey so many of are on: moving everything inside Emacs. Regular Irreal readers will recall that Ridenour is a Philosophy professor so he doesn’t have much need for high powered math tools but he does have to deal with grade calculations and various budget items. He had been using Soulver for this but, of course, this meant leaving Emacs, something all we Emacers hate.
Then he stumbled on literate-calc-mode. It did everything that Soulver did and Ridenour didn’t have to leave Emacs to use it. It’s been a win for him and he’s happy with it.
When I read Ridenour’s post, something seemed familiar. It turns out that I’d written about literate-calc-mode six years ago. It had just been released and no one had any experience with it yet. I meant to follow up but, of course, life intervened and I never did. I’m glad to see that it’s still around and has lived up to its potential.
I’m tempted to install it but I’m reasonably proficient with Calc itself so I probably wouldn’t use it enough to make it worthwhile. Still, if Reverse Polish Notation is not your thing and you’d rather deal with normal infix notation, literate-calc-mode may be a good fit. It’s easy to try out so give it a spin if you’re interested.
-1:-- Ridenour On Literate Calc Mode (Post Irreal)--L0--C0--2026-11-03T15:34:56.000Z
You can set up a capture template that creates a new Org heading. If
you define jump-to-captured to be
non-nil, org-capture will jump to that new heading. It
will also create a bookmark named org-capture-last-stored
at that line.
Bookmarks can help you find your way back to a line of code or a line
in an essay, and you don't have to be using Org. Before you navigate away to look something up, invoke
bookmark-set ( C-x r m ) to save your place.
This will place a character-sized image in the left fringe at the
line. Invoke bookmark-jump ( C-x r b ) to
return to your work.
If you have nothing better to do, you can change the shape of the
bookmark.1 First, design it with define-fringe-bitmap.
Then set the variable bookmark-fringe-mark to your new
bitmap using customize.
The Lisp expression in the following source block defines a Z-shaped
pattern that's 8 pixels wide and 8 pixels tall and names it
bookmark-zeit. Figure 1 shows the default bookmark and
this new bookmark for comparison.
(define-fringe-bitmap 'bookmark-zeit
[#b11111111
#b01111111
#b00001111
#b00011100
#b00111000
#b11110000
#b11111110
#b11111111])
![]() |
| Figure 1 -- Above, default bookmark; below, custom, Z-shaped bookmark |
The pattern can be a different size, but I'd recommend making it the same width as the fringe, which is 8 pixels by default. But you could make it taller. Figure 2 shows a Z-shaped pattern that's 12 pixels tall; note how well it stands out!
![]() |
Figure 2 -- A Z-shaped bookmark 12 pixels tall |
Recently I wrote about how to make the active window stand out. Originally, I thought to change the color of the left fringe to something much brighter. Now it occurs to me that one might leverage the bookmark system to fill the fringe with a pattern that's 64 pixels tall. Unfortunately it seems Emacs renders only the first 16 rows. In this case, adding eight 16-pixel-tall bookmarks on successive lines can fill up a 64-pixel vertical portion of the fringe. This is shown in Figure 3.
(define-fringe-bitmap 'bookmark-16
[#b01111110
#b01111110
#b01111110
#b00011000
#b00011000
#b01111110
#b01111110
#b01111110
#b01111110
#b01111110
#b01111110
#b00011000
#b00011000
#b01111110
#b01111110
#b01111110])
Figure 3 -- Eight 16-pixel-tall bookmarks on consective lines |
One important caveat to all this is that this re-defining of bookmarks affects all bookmarks everywhere, not just the latest one or the next one. At least that's true of Emacs version 30. Who knows, maybe we'll see a fringe-decor package eventually. As if there's isn't enough to play with now ....
1 But if you do have better things to do and want to
change fringe bitmaps, you could check out the
packages fringe-helper or modern-fringes
on melpa.
-1:-- Emacs Bookmark -- Just a Bitmap in the Fringe (Post Raymond Zeitler)--L0--C0--2026-11-02T22:37:19.150Z
Belated happy 50th birthday, Emacs!
In other news, you can now reach Emacs News at https://emacs.news. Enjoy!
Links from reddit.com/r/emacs, r/orgmode, r/spacemacs, Mastodon #emacs, Bluesky #emacs, Hacker News, lobste.rs, programming.dev, lemmy.world, lemmy.ml, planet.emacslife.com, YouTube, the Emacs NEWS file, Emacs Calendar, and emacs-devel. Thanks to Andrés Ramírez for emacs-devel links. Do you have an Emacs-related link or announcement? Please e-mail me at sacha@sachachua.com. Thank you!
You can e-mail me at sacha@sachachua.com.
-1:-- 2026-11-02 Emacs news (Post Sacha Chua)--L0--C0--2026-11-02T14:20:32.000Z
-1:-- My blogging setup in 2026: reducing friction (Post Diego Zamboni)--L0--C0--2026-11-02T13:16:00.000Z
Please note that planet.emacslife.com aggregates blogs, and blog authors might mention or link to nonfree things. To add a feed to this page, please e-mail the RSS or ATOM feed URL to sacha@sachachua.com . Thank you!